#LLM
Curated coverage on «LLM»: releases, research, benchmarks, open-source.

Your Own AI Server: Stop Torturing Your Home Laptop and Ignore the Influencers
Stop believing fairy tales about powerful AI on old laptops. Here's how to build a hardware foundation for your own AI that actually works.
OpenAI vs. your job: three announcements that change everything
OpenAI is in turmoil, but releases ship on schedule. Three updates could turn your AI into a doctor, a coworker, or your replacement. Is it time to panic?
Tesla Optimus Gen 3: a million metal workers and the end of the manual labor era
Elon Musk is building an army of humanoids. The third-gen Optimus learns just by watching us and is gearing up for a mass rollout into factories.

Grok wants an Oscar: why Elon Musk is hiring the world's best writers

Oracle goes all in: $50 billion for AI cloud
Layoffs or "AI-washing": how corporations hide their problems behind neural networks
Deep Intelligent Pharma: A "Bionic Brain" Instead of an Army of Lab Technicians

Kimi K2.5: China's Brainy Underdog Outplays OpenAI and Goes After Dollars
Moonshot AI has released K2.5. It's already in OpenRouter's top ranks, and overseas revenue has beaten domestic for the first time. 300 people may be able to beat…

NVIDIA Bets Big on OpenAI as Apple Engineers Flee to Rivals
Jensen Huang lines up NVIDIA's biggest deal ever, Apple loses talent to Meta and Google, and Elon Musk wants data centers in space. Here's the tech news that…
Qianxun AI: Chinese algorithms are coming for HR departments' jobs
The Yuan Wars: Chinese Tech Giants Burn Billions to Win AI Traffic
China's Margin Call: Why the AI Bubble Is Starting to Deflate

Qwen App: Alibaba burns through 30 billion on a Lunar New Year offensive
Grok in Indonesia: Elon Musk Learns to Bargain With Censorship
Indonesia is opening its doors to Grok. Why Musk's rebellious AI had to accept the authorities' terms, and how that may shift the balance of power in Southeast Asia.
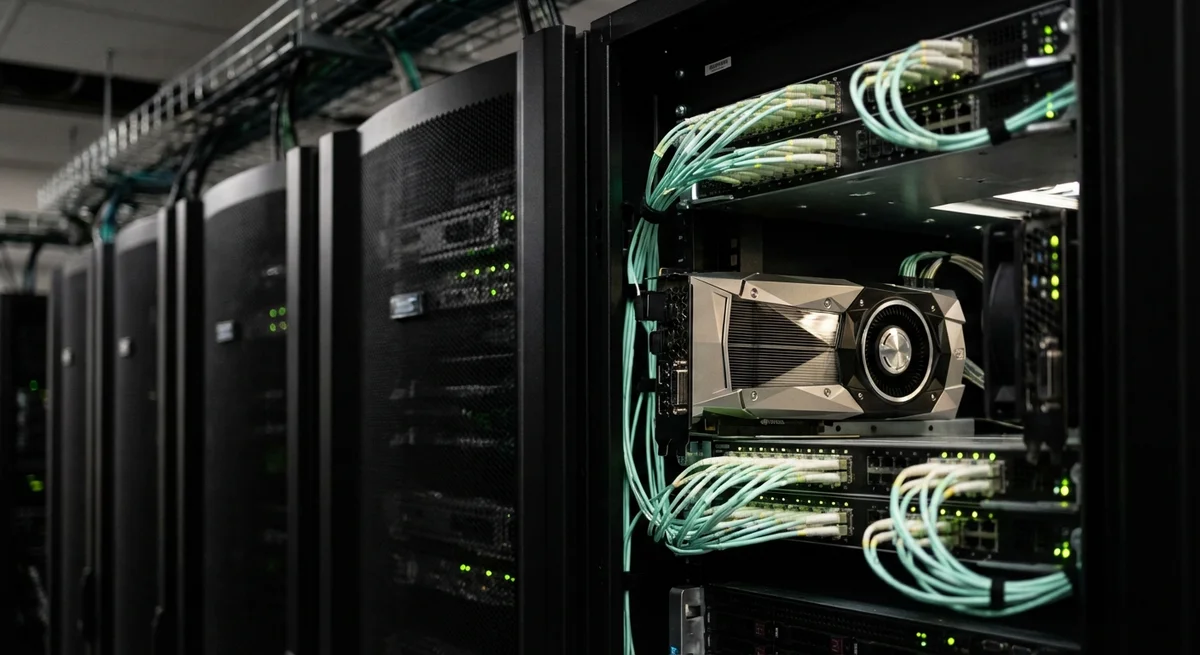
NVIDIA QAD: How to Squeeze a Model Into 4 Bits Without Losing Its Brains
NVIDIA's new QAD method tackles the quality loss LLMs suffer when quantized. 4-bit models now keep their accuracy in math and code while running on ordinary…