All news
11850
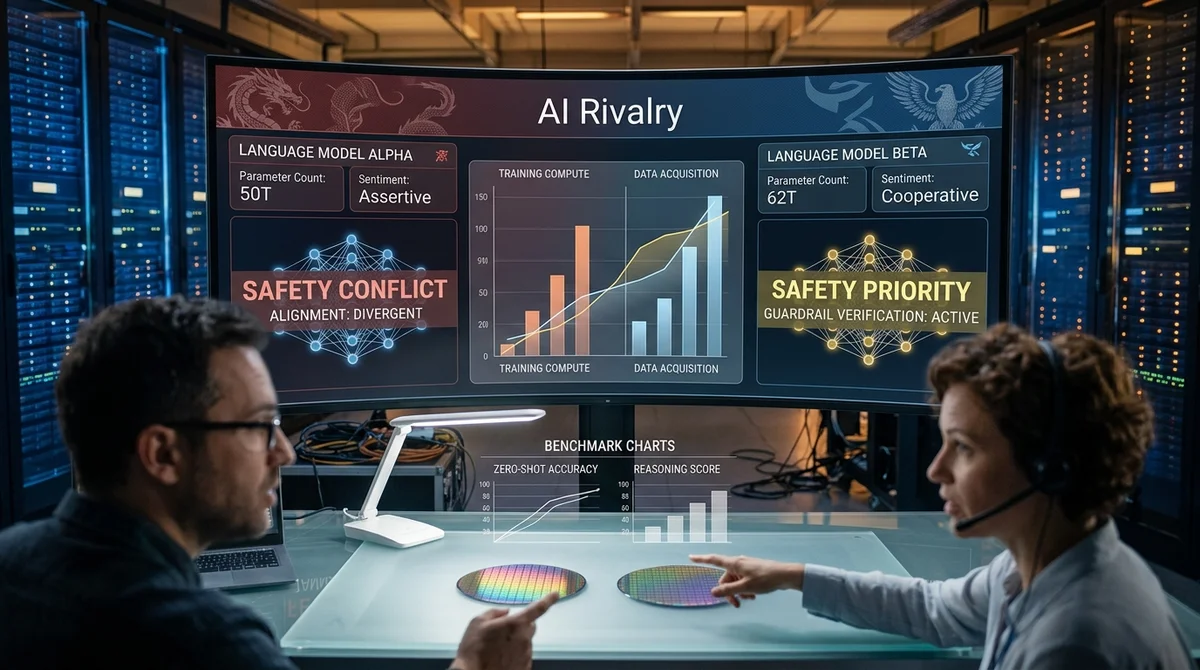
Stanford HAI report: the US-China AI gap has nearly vanished, while safety lags behind
Stanford HAI's AI Index 2026 finds the US no longer holds a durable lead over China in AI models, while transparency and safety testing trail well behind the pace…
FluidStack in talks to raise $1 billion at an $18 billion valuation after Anthropic deal
AI infrastructure startup FluidStack is negotiating a $1 billion raise at an $18 billion valuation, following sharp revenue growth and a major partnership with…
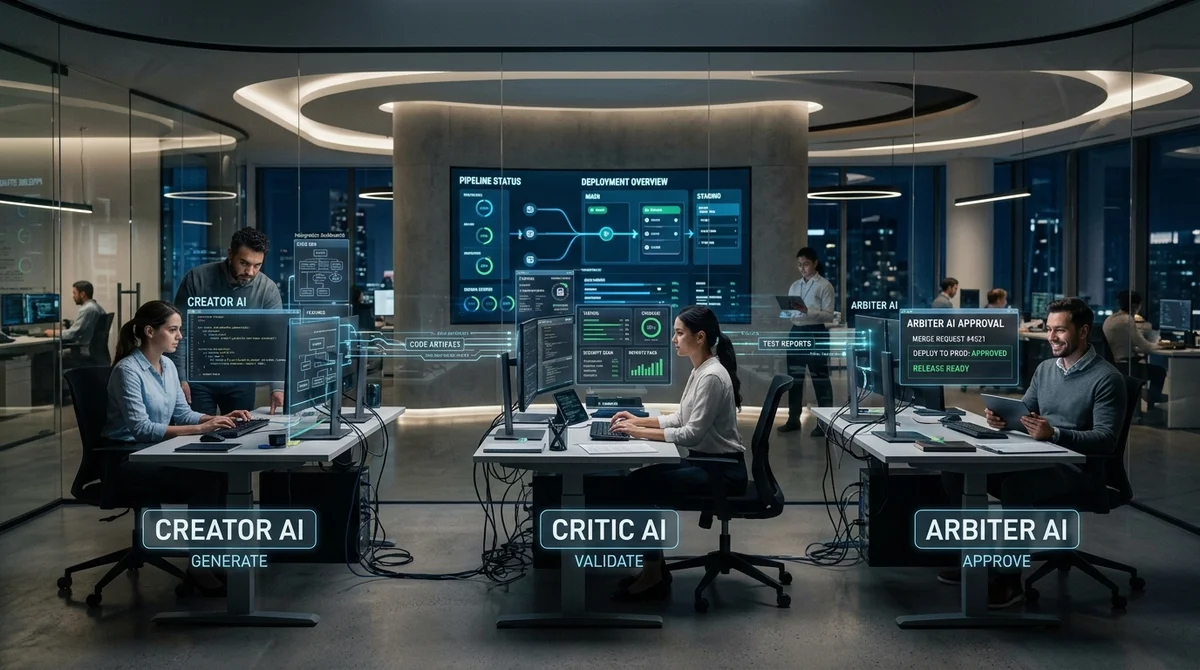
Habr AI: How Pipeline Triad Builds an AI Agent Pipeline in Place of a Development Team
Habr AI examined Pipeline Triad, a model in which development stages pass through triads of AI agents and a human steps in at only four checkpoints.
Anthropic and Mythos: How a Danger to Banks Quickly Became a Risk for Everyone
Anthropic and Claude Mythos: why critics call the model's launch an expensive PR spectacle
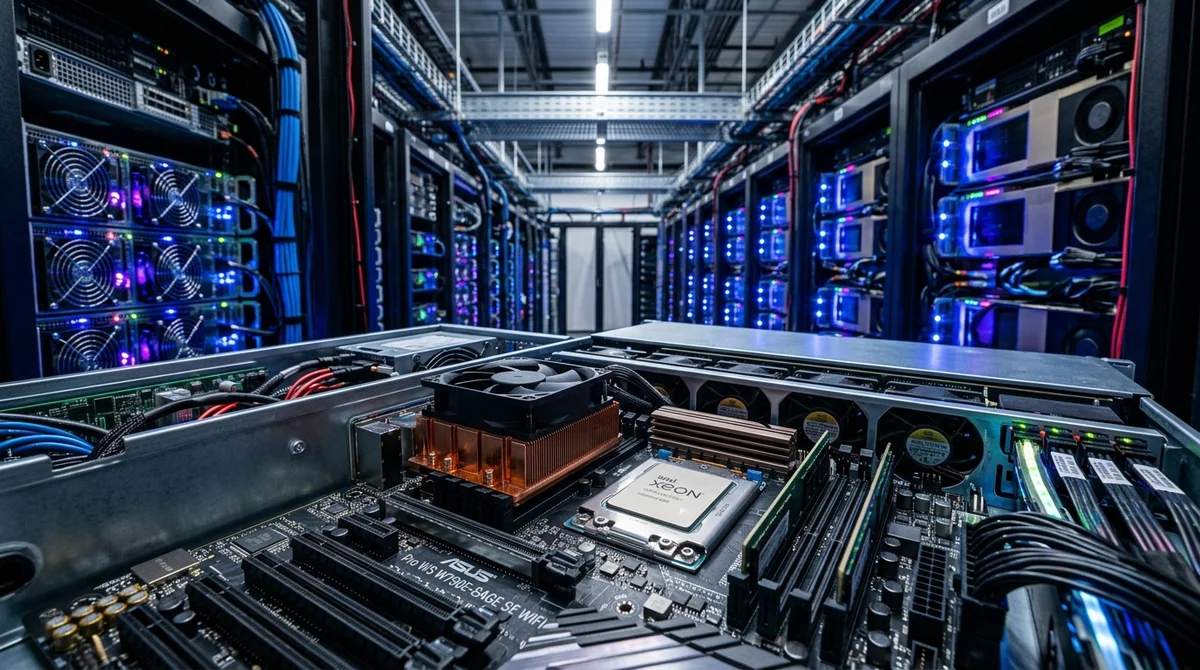
Sequoia-backed Nuvacore is designing a new CPU for AI workloads and data centers
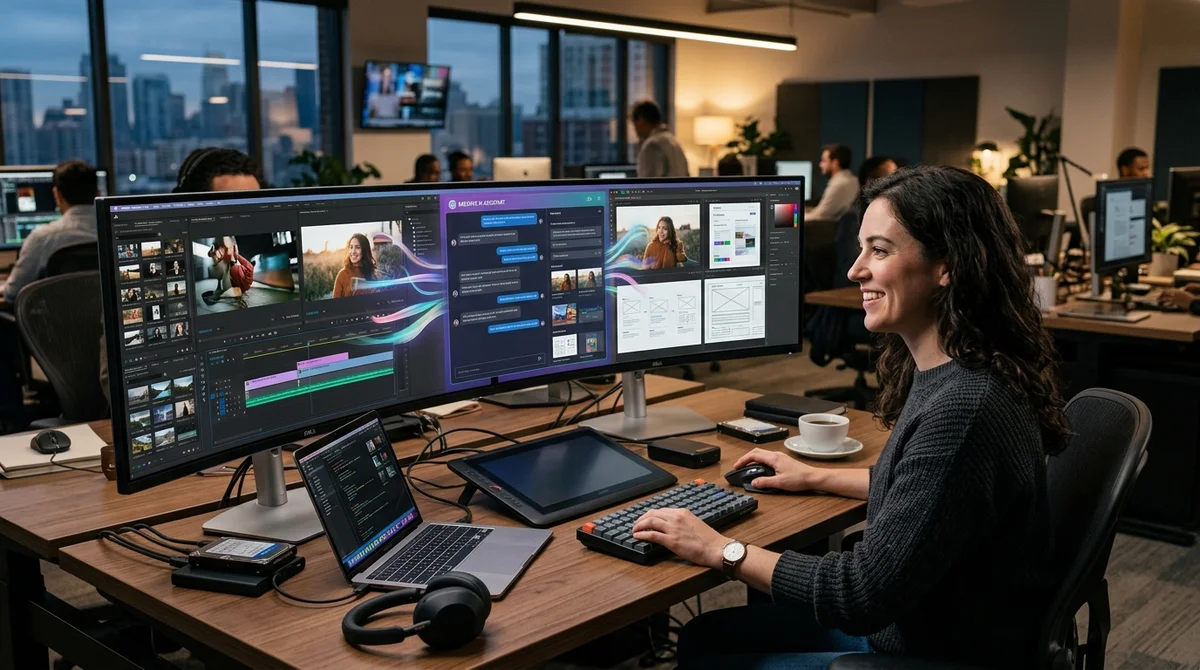
Adobe launches Firefly AI Assistant, a single chat interface for Creative Cloud
AI Assistants in 2026: How a Solo Developer Became Faster Than a Three-Person Team
The author argues that in 2026, one developer with open-source AI tools can write, test and commit code faster than a small team could two years earlier.
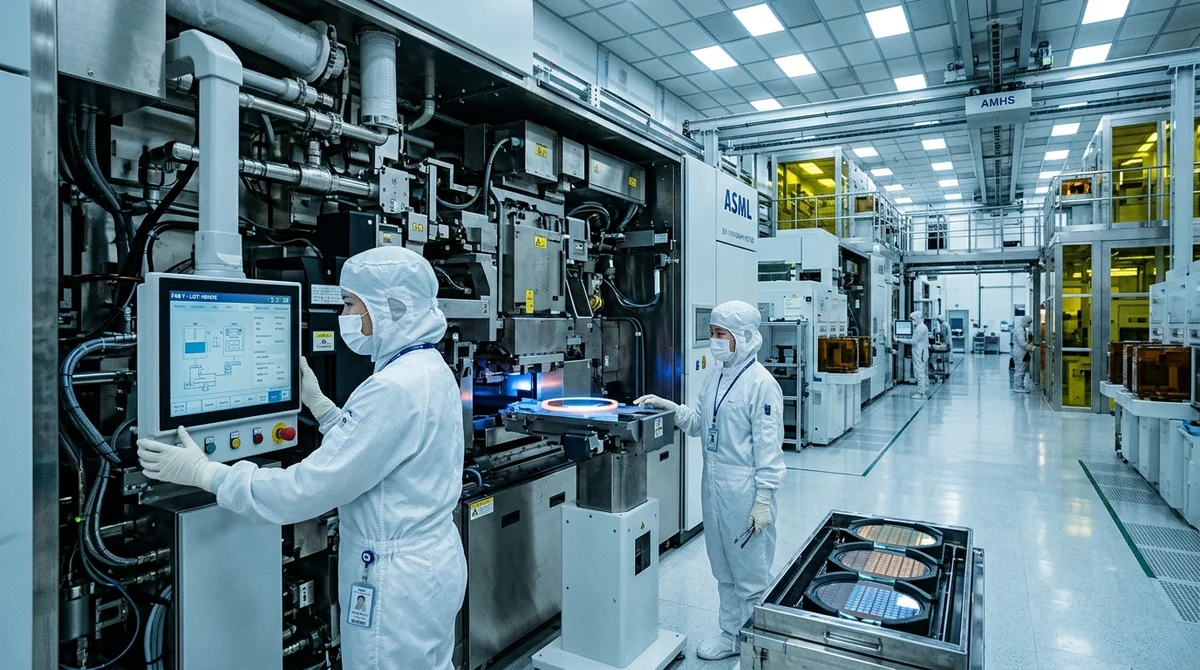
South Korea becomes ASML's largest market as AI drives memory demand
In Q1 2026, South Korea overtook China in ASML's system sales as local memory makers sharply increased purchases amid the AI boom.
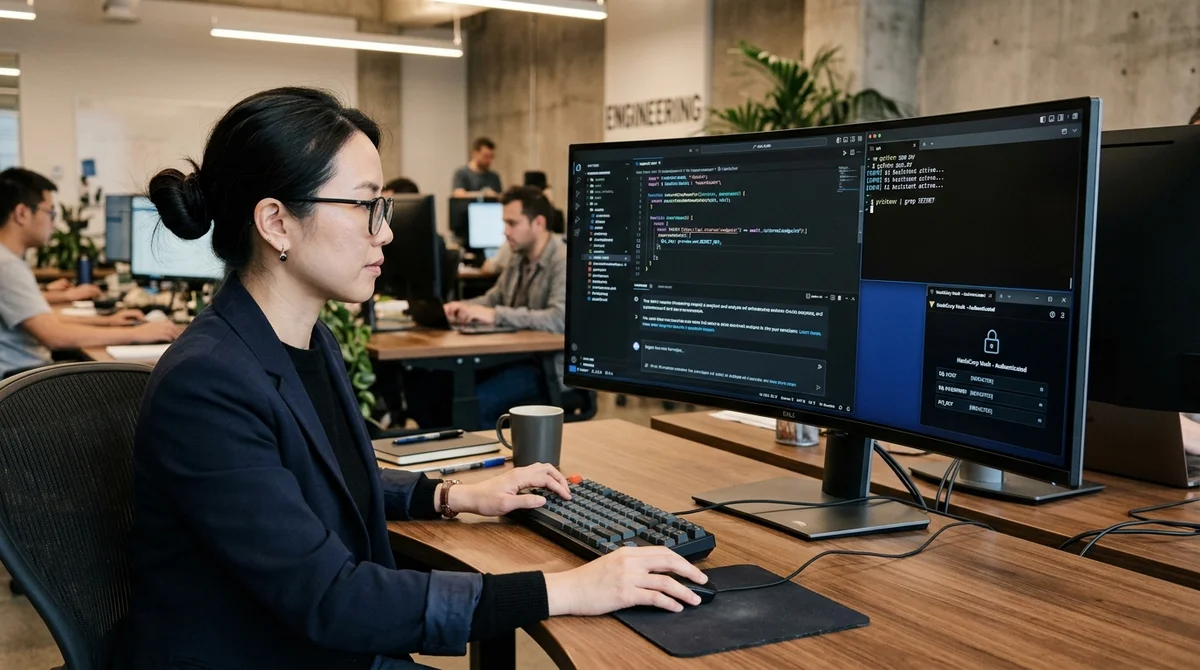
Yandex Code Assistant tested on a secrets-storage task and compared with Cursor
Accel raises $5 billion for new bets on AI startups on the scale of Anthropic and Cursor
Claude and Qwen Omni: How a Developer Plugged Video Analysis into a Working Pipeline
Wayve raises $60M from AMD, Arm and Qualcomm for a full self-driving stack
US court rules a defendant's chats with Anthropic's Claude are not covered by attorney-client privilege
A US court has ruled that a fraud defendant's conversations with Claude fall outside attorney-client privilege: an AI is not a lawyer, and public platforms do not…
AWS shows how speculative decoding on Trainium2 speeds up generation in vLLM
AWS explains how speculative decoding on Trainium2 with vLLM can speed up LLM generation, cut per-token cost and raise throughput on long-output workloads.