Claude and Qwen Omni: How a Developer Plugged Video Analysis into a Working Pipeline
A developer has shown how to turn Claude into a practical tool for video analysis by connecting it to Qwen Omni. Instead of slicing video into frames, which loses the motion, the pair of models automatically described and sorted 29 character animation references. The practical point is simple: Claude's strong reasoning can be extended with an external multimodal layer, saving an hour to an hour and a half of manual routine.
AI-processed from Habr AI; edited by Hamidun News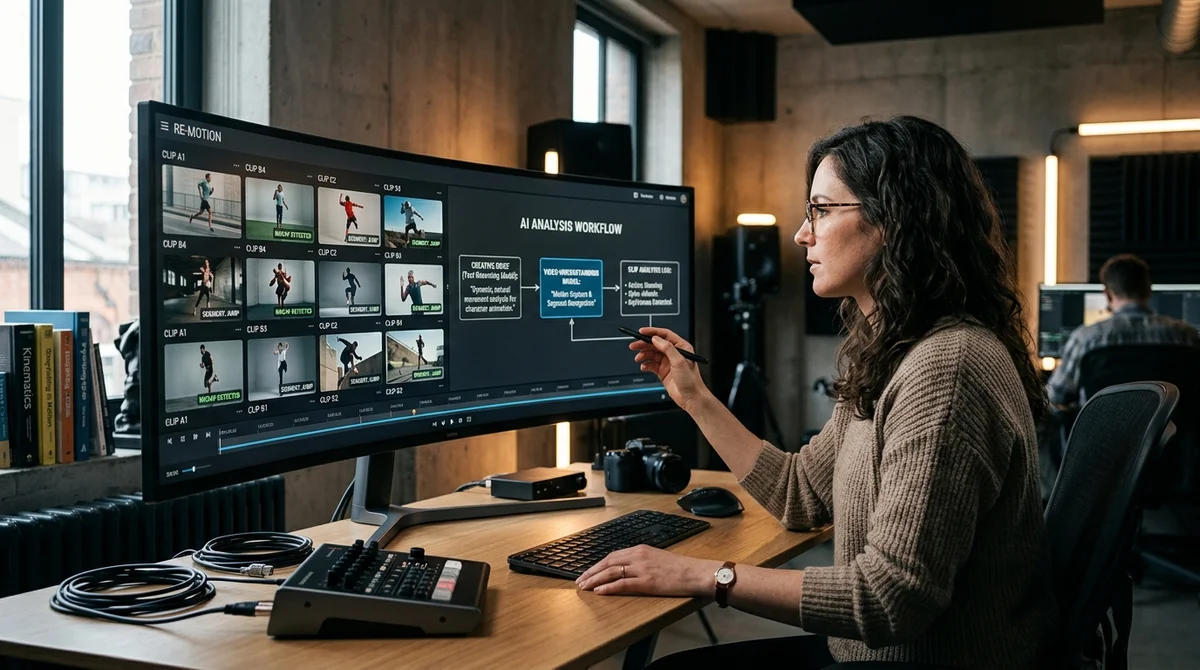
In a new Habr post, a developer describes a simple but useful way to extend Claude for tasks that call for analyzing video rather than individual images. Instead of waiting for Anthropic to add native video support, he built a chain of two models: Qwen Omni handles multimodal perception, while Claude handles analysis, structuring and writing up the result. In practice, this turned a tedious manual job into an automated pipeline that saves time and preserves the context of movement better.
The problem he ran into is familiar to anyone who works with animation, motion graphics and visual references. If you cut a video into frames and send them to a model one by one, you lose what matters most: the link between states, the tempo, the camera trajectory, the transitions between poses and the overall shape of the action. For static scenes, this workaround is still tolerable, but for motion analysis it quickly hits its limits.
For tasks such as breaking down camera techniques, syncing gestures, tracking shot changes and evaluating a character's final design, the compromise is nearly useless. The model sees a set of pictures rather than a coherent event, and a person still has to piece the meaning back together by hand.
The actual task was entirely practical: the project folder held 29 generated video references of character animation, which needed to be sorted into categories and briefly described in terms of movement. Doing it by hand would have taken the author roughly an hour to an hour and a half, and for work with little added value: open a file, watch it, identify the type of movement, write a description, move to the next. For creative professionals this kind of routine is especially painful, because it eats time not for creating but for taking inventory of material that already exists.
The solution came from Qwen Omni, which the author was already using in another project, a real-time digital character assistant. The idea turned out to be logical: if one model understands multimodal input well and another is strong at interpretation and producing clean text, they can be linked into one workflow. In this setup, Qwen Omni first receives the video and extracts meaningful features and a description of what is happening.
Claude then uses that material as the basis for easier categorization, comparisons and written conclusions. From there, you can get not just a raw retelling but uniform descriptions, lists, tags and short takeaways for every clip in the folder. This is not a "magical" transformation of Claude into a full video model, but a practical composition of specialized tools.
The approach itself matters from an engineering standpoint. Rather than hunting for one universal model for every task, the author assembles a stack of components with different specializations. For users, this offers a more realistic path to multimodality: instead of waiting for a favorite LLM to learn everything at once, you give it external sensors and intermediate layers. The pattern is especially useful where not only recognition but also the reasoning that follows is valued: scene analysis, describing a character's behavior, identifying typical movement patterns, preparing notes for production or for team communication. The same scheme can be used to analyze storyboards, tutorial videos, interface recordings and test generations before editing.
The Claude and Qwen Omni story shows that a model's limitation does not always mean a dead end for the whole process. If you break a task into stages (perception, description, classification and conclusion), it becomes clear which part an outside tool can already cover. For visual content creators, animators and AI artists, this is a good signal: value increasingly comes not from a single "smartest" model but from a well-assembled chain in which each system does what it is genuinely good at.
- Nov 2, 2026Karpathy builds a YouTube clone with 6454 videos from Hacker News recommendations in two hours
- Nov 2, 2026Karpathy used Claude to build HackerTube from 6,454 videos recommended on Hacker News
- Nov 2, 2026Arca gives AI agents finance tasks lasting up to 10 days, but leaves the trades to humans
- Nov 2, 2026Anthropic needs to grow revenue 32% a year to cover $850 billion in contracts
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.