Local LLMs
Local LLMs are language models that run directly on your own hardware — a laptop, a PC with a GPU or a home server — with no cloud, no subscriptions and no data leaving your machine. Ollama, llama.cpp and LM Studio, plus quantized GGUF builds of Llama, Qwen and Gemma, make it possible even on a decade-old graphics card. Here is all our coverage of running AI locally: guides, hardware tests, quantization and privacy.
Epotos implemented local AI for claims and moved complaints to Bitrix24
Fire suppression systems manufacturer Epotos automated customer claims processing: a local Tesseract, Qwen, and Bitrix24 stack reads emails and attachments.
deepvk USER2-base model nearly matched OpenAI in a case-law embedding benchmark
The author compared 7 embeddings and 4 rerankers on 858 intellectual property cases and found that the local deepvk USER2-base performs almost on par with OpenAI…
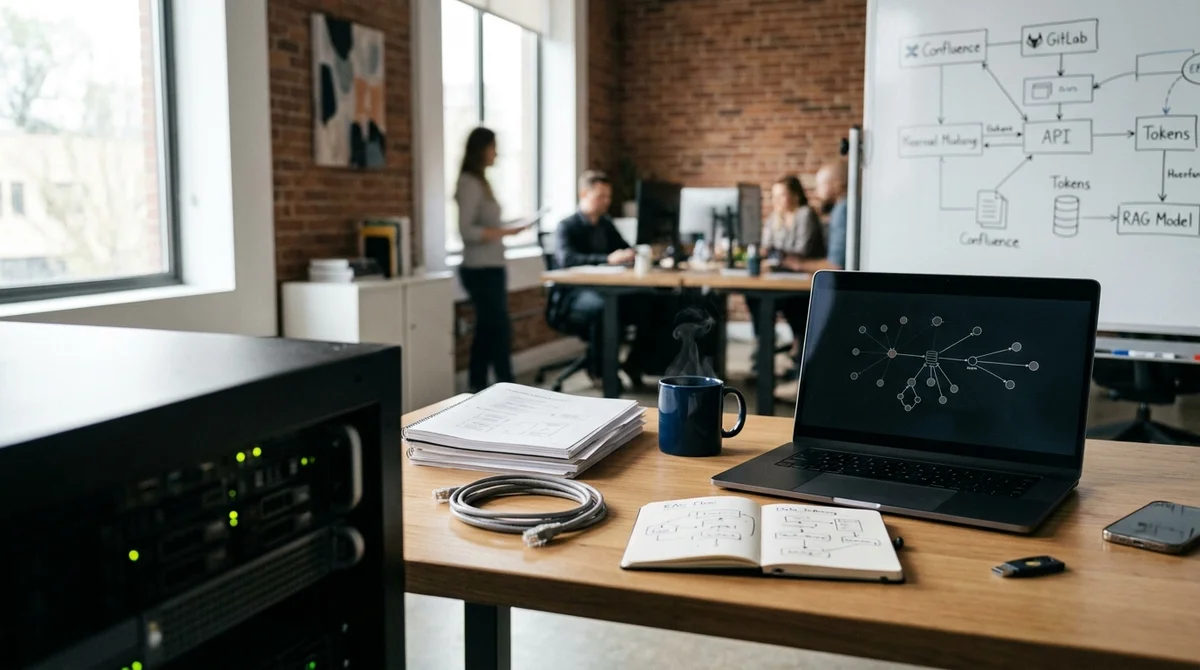
Runity showed how it is building an enterprise RAG assistant for Confluence and GitLab
Runity is preparing an internal RAG assistant that searches across Confluence and GitLab, checks access permissions via user tokens, and runs on local…
Habr AI showed how to build your own RAG retriever in LangChain for names and terms
Ollama accelerates local AI on Apple M5: a Mac with at least 32 GB of memory is required
Google released Gemma 4 on Hugging Face: multimodal models for local inference
5 Docker containers for AI agent developers: spin up and get to work
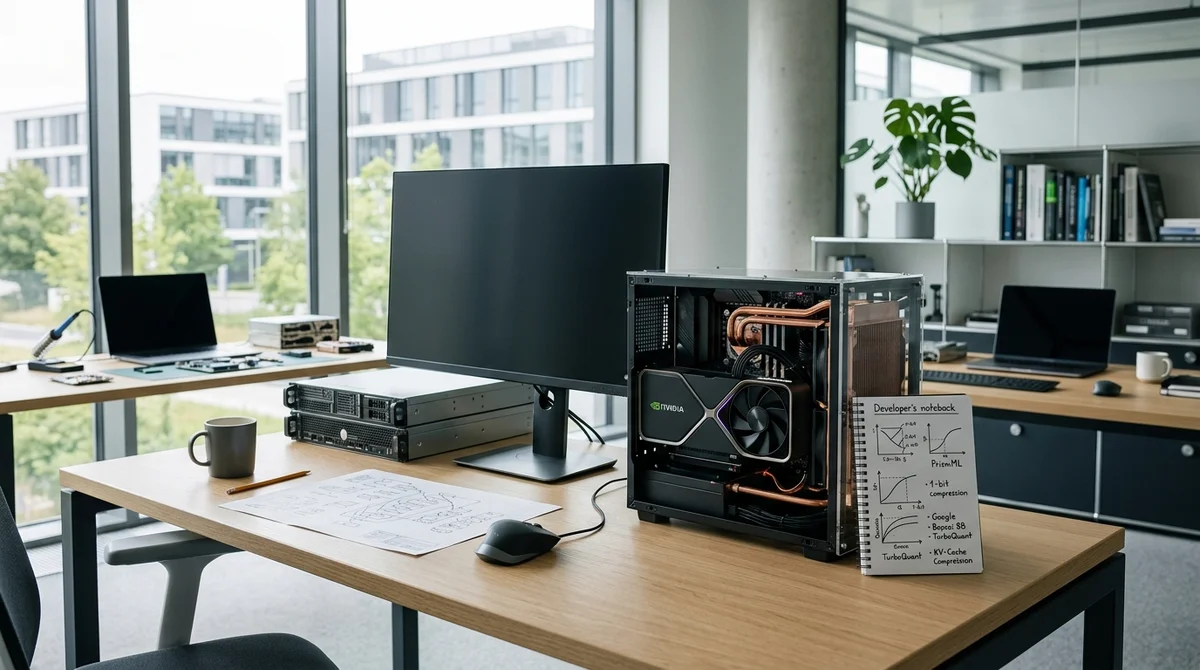
PrismML and Google Bring Local 200B Model Inference Closer with Bonsai and TurboQuant
PrismML unveiled 1-bit Bonsai 8B, while Google Research introduced KV-cache compression through TurboQuant: together, these approaches make the idea of running 200B…
OpenClaw: five projects for building a personal AI assistant, from chats to a server
A selection of five projects shows how to turn OpenClaw from a chatbot into a personal assistant by connecting messaging apps, local models, Google Workspace, a…
Habr AI lists six local neural networks for autonomous offline work in 2026
WACV 2026 in Tucson showed Computer Vision's shift toward multimodality and synthetic data
Google’s Gemma 4: how to run tool calling locally with Python and Ollama
KDnuggets showed how to run Qwen3.5 on an old laptop with Ollama and OpenCode
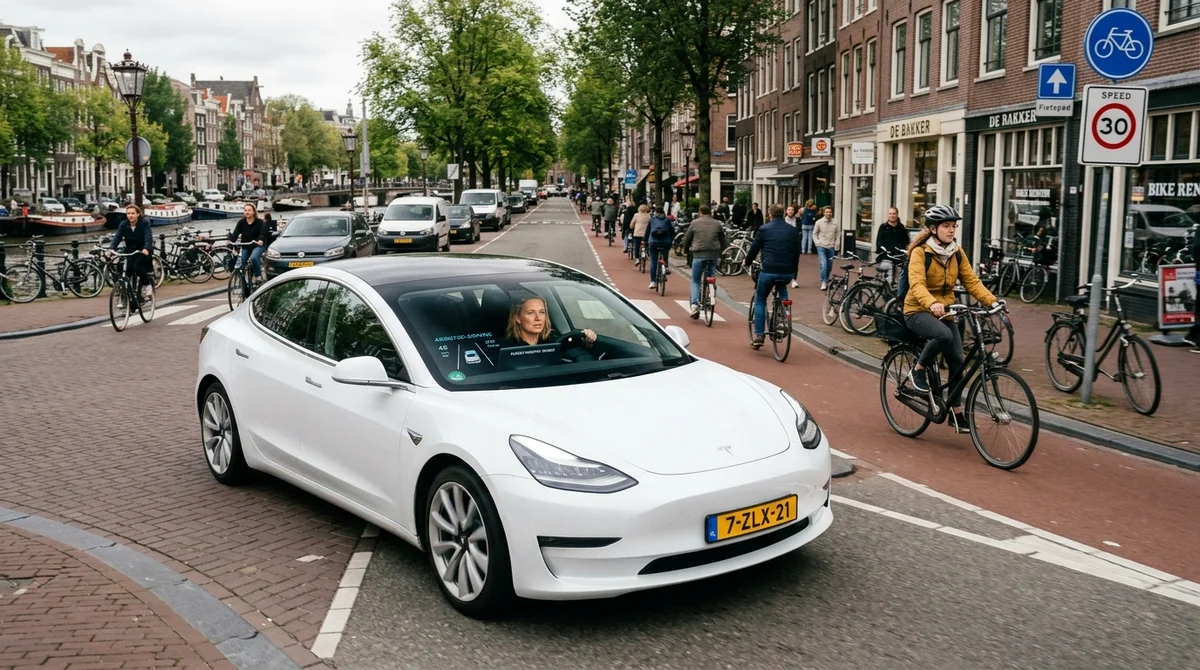
Tesla gets Europe's first approval for FSD Supervised — launch begins in the Netherlands
Dutch regulator RDW approved Tesla's FSD Supervised in the Netherlands, marking Europe's first approval for a driver-assistance system of this kind under UN…
Google Gemma 4 forced companies to reassess AI controls on local devices
The release of Google Gemma 4 intensified the problem of corporate control over AI: models now run directly on employees’ laptops, bypassing cloud gateways, logs…