Local LLMs
Local LLMs are language models that run directly on your own hardware — a laptop, a PC with a GPU or a home server — with no cloud, no subscriptions and no data leaving your machine. Ollama, llama.cpp and LM Studio, plus quantized GGUF builds of Llama, Qwen and Gemma, make it possible even on a decade-old graphics card. Here is all our coverage of running AI locally: guides, hardware tests, quantization and privacy.
NVIDIA Tesla V100 for local AI models: testing on real-world tasks
The 2017 Tesla V100 16GB handles modern LLM models like Qwen35B and GPT-OSS-20B. In tests, it generated websites, games, and document summaries at speeds of 38–109…
Cohere releases Command A+: 218 billion parameters for agents on two GPUs
Cohere has unveiled the open Command A+ model with 218 billion parameters and multimodal capabilities, running on two H100 GPUs and supporting 48 languages.
How Researchers Bypassed Safeguards in AI Models: Simple and Dangerous
Researchers found that built-in restrictions in AI models can easily be bypassed through simple modification. This raises serious questions about the safety of the…
Claude blocks Russian IPs: how to avoid losing your AI project
How Claude Code and ChatGPT pull users into expensive plans: a way out via multi-agents
NVIDIA packed 3 models into one file and made training 360× more efficient
Local LLM on a 2017 Graphics Card: AMD RX 580 + Vulkan + Ollama
Vector Database Comparison in 2026: Nine Systems by Cost, Scale, and Architecture
Nine leading vector databases are now key infrastructure for RAG and agential AI. A review of architecture, cost, and scalability helps choose the right system for…
Gemma 4 and Qwen Coder vs. the cloud: local LLMs in production
Local LLMs (Gemma 4, Qwen Coder) successfully handle production coding tasks on GPUs with 16 GB of memory — with the right parameter settings.
AI Memory Shortage Splits the Chip Market Into Leaders and Laggards
Deepseek-agent: how to write your own Claude Code in 2,000 lines of code
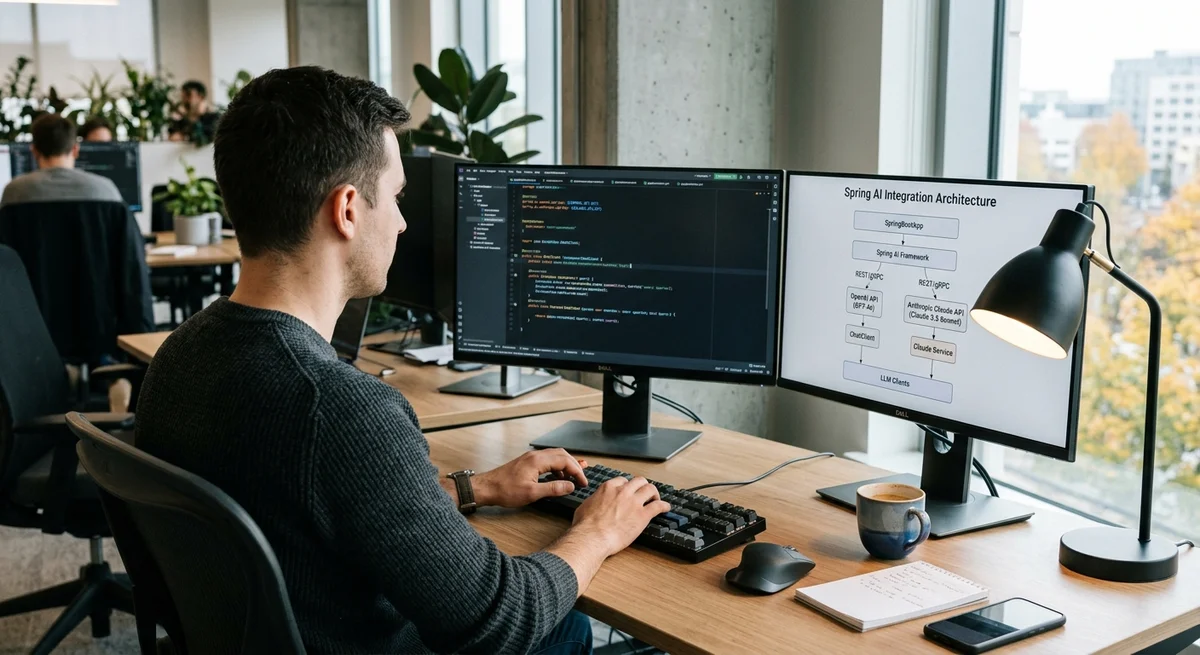
Spring AI made it easier to integrate Java applications with Claude and other LLM providers
AI agent in one day: a local prototype without the cloud or developers
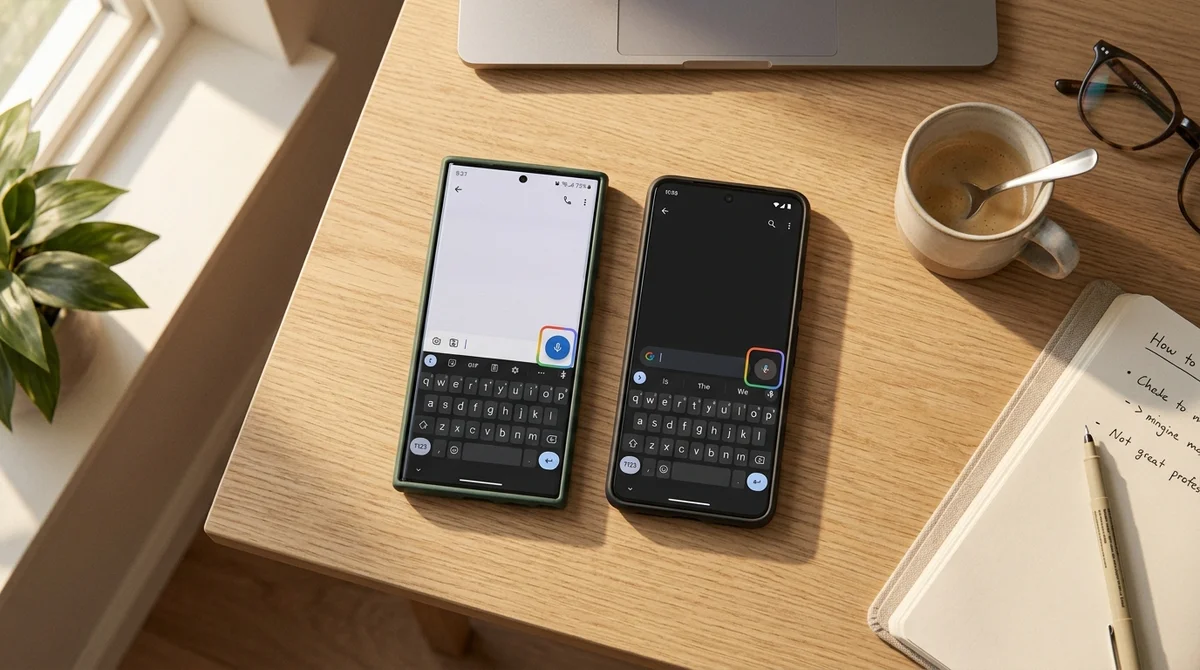
Google adds Gemini dictation to Gboard, posing a threat to startups
Google integrated Gemini into the Gboard keyboard, adding smart dictation. The feature is available on Samsung Galaxy and Pixel. This pushes out independent…
Osaurus released a Mac app where local and cloud AI models work together
Osaurus offers Mac users a single interface for local and cloud AI models: memory, files, and tools stay on the device, while the cloud is used when needed.