Local LLMs
Local LLMs are language models that run directly on your own hardware — a laptop, a PC with a GPU or a home server — with no cloud, no subscriptions and no data leaving your machine. Ollama, llama.cpp and LM Studio, plus quantized GGUF builds of Llama, Qwen and Gemma, make it possible even on a decade-old graphics card. Here is all our coverage of running AI locally: guides, hardware tests, quantization and privacy.
Reg.Oblako: generative AI has entered its 1997 internet phase, and the window for entry is narrowing
In a column, Reg.Oblako CIO Evgeny Martynov compared the stage of generative AI to the internet in 1997 and explained why 2026–2027 will determine who integrates AI…
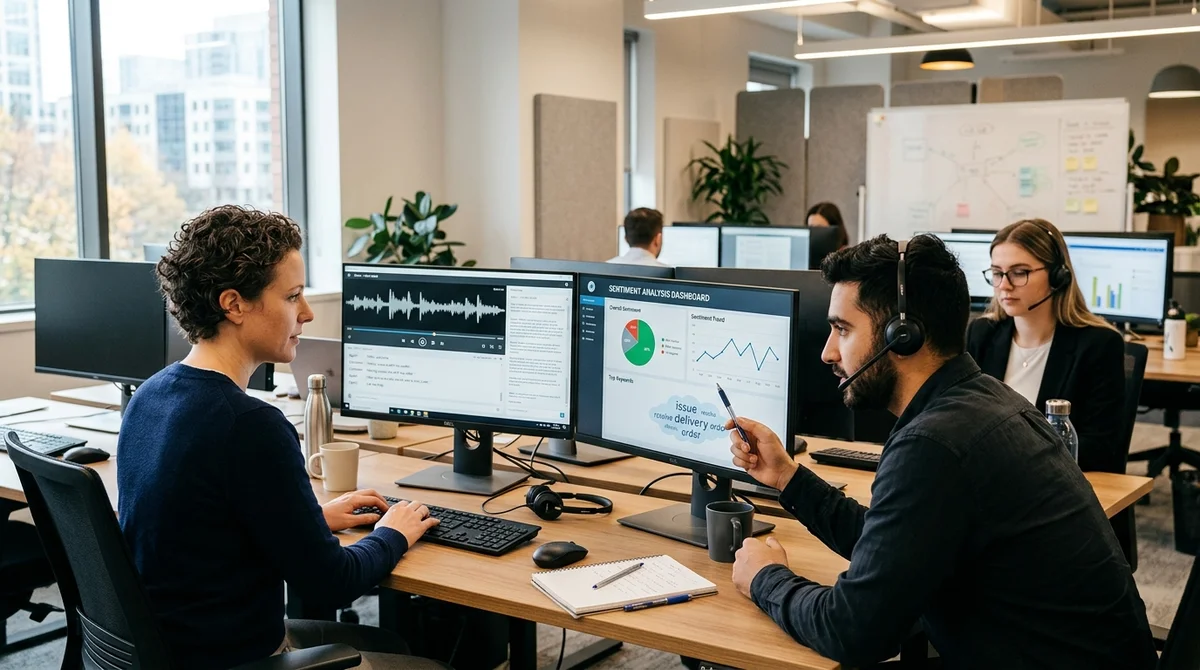
KDnuggets published a guide to local call analysis with Whisper, BERTopic, and Streamlit
KDnuggets reviewed an open-source project that transcribes customer call recordings with Whisper, detects sentiment and emotions, and then groups topics in a local…
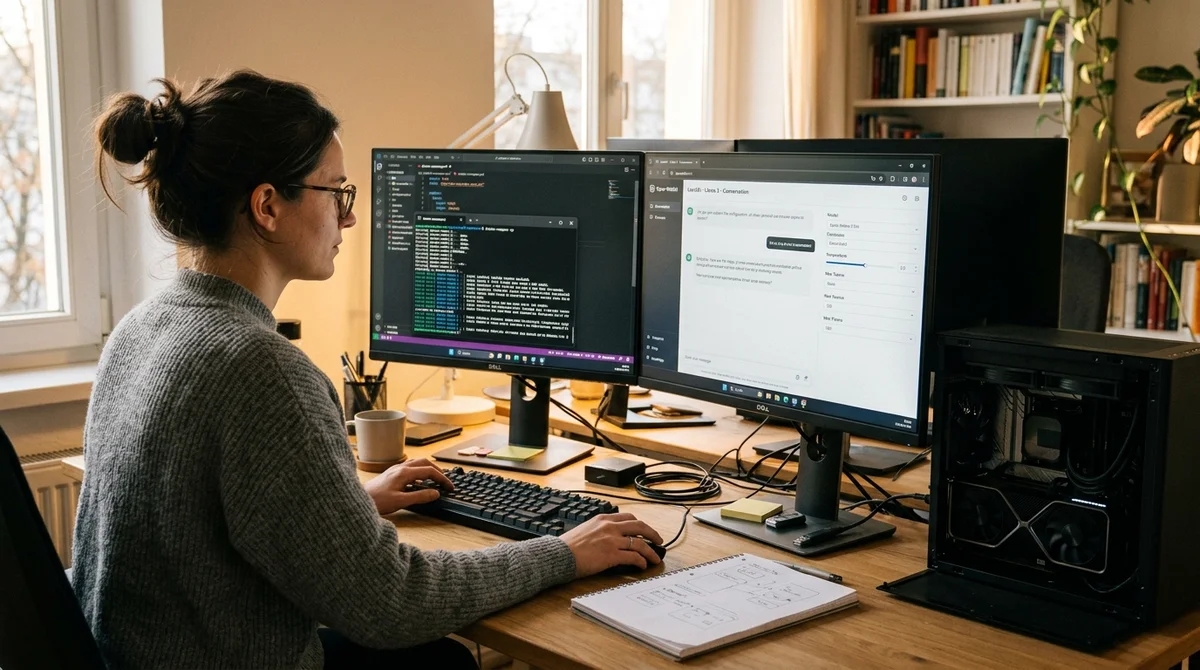
Open WebUI and llama.cpp: how to set up local web search with Qwen and Docker on Windows
The author of a practical guide showed how to turn the Open WebUI and llama.cpp pairing from weak web search into a working local stack with Qwen, Tika, Brave…
An open-source stack of 6 models and 9 agents showed how to build an AI team on a single server
GLiNER 2 showed how compact encoders are catching up with LLMs in NER and classification
Ollama Cloud compared in a code review: DeepSeek v3.1 proved stronger than Qwen and GPT-OSS
Zhipu AI releases GLM-OCR, a compact 0.9-billion-parameter OCR model for documents
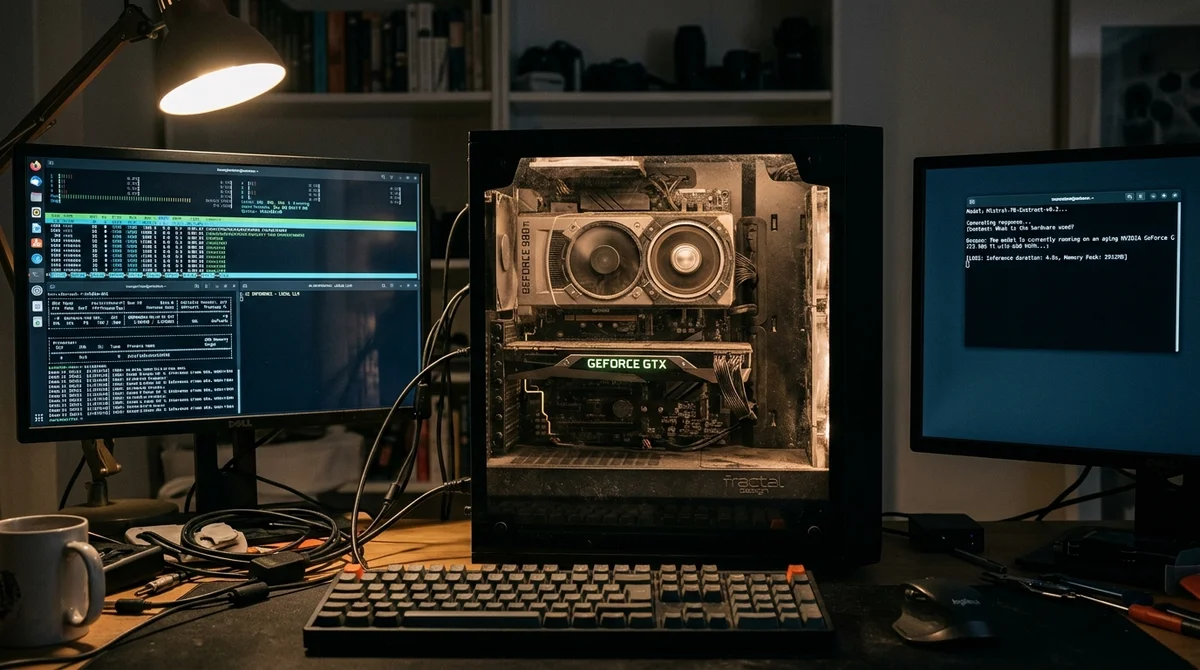
AMD RX580 ran an LLM locally: how to tame ROCm, Ollama, and get GPU inference
An engineer showed how to make an old AMD RX580 run an LLM reliably with ROCm and Ollama, breaking down false signs of GPU activity, hipMemGetInfo failures, and…
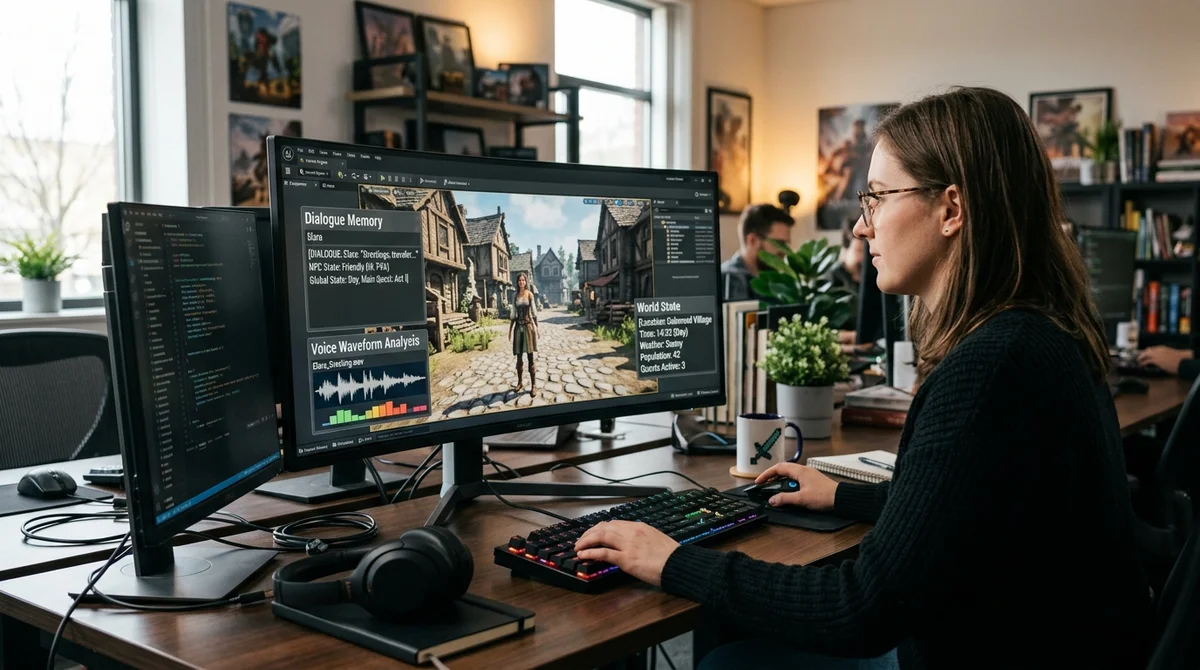
Unity showed how to build voice NPCs with memory and world context
A step-by-step guide shows how to build voice NPCs in Unity with a local model, dialog memory, knowledge of the game world, and spoken responses instead of standard…
Mistral released Small 4 — a 119-billion-parameter MoE model for reasoning, code, and multimodality
Nvidia turned OpenClaw into an enterprise platform with security and local AI models
NVIDIA released Nemotron 3 Nano 4B — a compact hybrid model for on-device deployment
Hugging Face: Chinese open-source models overtake the US in AI ecosystem downloads
Ollama and LiteLLM: how to turn a Python script into a complete console-based LLM chat
In the second part of the practical guide, the author shows how to turn a basic Python script with Ollama and LiteLLM into a console chat with a dialogue loop, a…
AI Independence Bench compared 49 models and measured their resilience to user pressure
The new benchmark, AI Independence Bench, tests whether 49 language models can maintain their own stance, avoid apologizing without reason, and not agree with the…