#LLM
Curated coverage on «LLM»: releases, research, benchmarks, open-source.
Large Language Models: Why Running Them Out of the Box Is Still an Illusion
There are now so many open LLMs that picking a workhorse is a quest in itself. But the real trouble starts after the download: no major model runs without hacks…
AI code review without the cloud: how Ollama changes local development
Developers have shown how to run a full AI code review on their own machine, with no cloud services, API keys or subscriptions. Ollama and local models make that…
Meta pays News Corp for the right to feed news to its AI
Meta has signed a licensing deal with Rupert Murdoch's media empire. Its Meta AI chatbot can now legally cite The Wall Street Journal and other titles. What does…

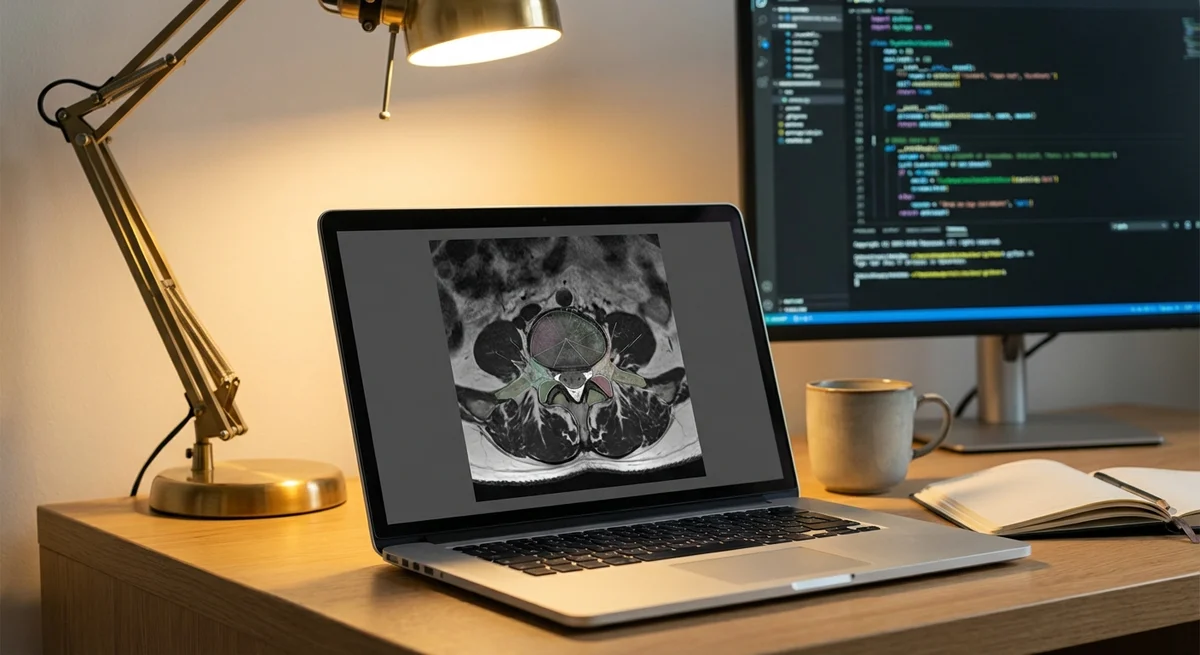
Developer builds spine MRI analyzer with Python and Gemini
Juniors vs. AI: How Entry-Level Developers Can Survive Today's Job Market
Telegram bot builds a VkusVill grocery cart from a single sentence
Nobody knows how AI companies should work with the government
Apple may store Siri data on Google servers
Apple has asked Google to set up server infrastructure for the new Gemini-based Siri. A company that spent years building an ecosystem around privacy is sinking…

Anthropic gives free Claude users a memory feature, challenging ChatGPT
Anthropic is opening cross-conversation memory to free Claude users amid what it calls unprecedented demand. The company is betting on retaining the new audience…
Meta tests an AI shopping assistant, taking on ChatGPT and Gemini
Deutsche Telekom to build an AI assistant directly into phone calls
AI helps formally verify the proofs of a Fields Medal winner for the first time
ChatGPT instead of a therapist: Brown University study finds serious ethical risks

Ads in ChatGPT: What They Mean for Advertisers
OpenAI is starting to test ads in ChatGPT but is silent on the key question: how brands will actually place them. Here is what is known and what businesses can…
How to Stop Guessing and Start Measuring AI Agent Quality
Bitrix24's team spent six months building a benchmark system for its AI agent Marta. Their experience shows why manual testing no longer works, and what replaces it.