Together AI Blog
AI news source. Articles are auto-selected and adapted by Hamidun News editors.
Latest publications

Together AI Launches Post-Training: RL and SFT on B200 at $9 per GPU-Hour
Together AI has opened Post-Training: RL and SFT on dedicated GPUs, LoRA and full weights, and a one-line migration from Tinker. B200 costs $9 per GPU-hour for the first 8 weeks.

Together AI and Y Combinator launch first dedicated GPU cluster for YC startups
Together AI and Y Combinator have launched the first dedicated GPU cluster for the YC community, with no mandatory two-year contracts for renting compute.

Kimi K2.7 Code versus Claude Fable 5: landing pages 94% cheaper
Together AI compared Kimi K2.7 Code and Claude Fable 5 on 12 landing pages: Kimi cost 94% less and barely lost in result quality.

Together AI brings nine research papers to ICML 2026 conference in Seoul
Together AI announced that nine of its research papers have been accepted to ICML 2026 in Seoul — presentations cover the entire AI infrastructure stack, from agents to GPU kernels.

Mamba-3: transformer alternative with linear complexity
Researchers from CMU and Together AI unveiled Mamba-3 — a new SSM-based architecture optimized for fast text generation.
Together AI launches guaranteed inference for open models with 99% SLA
Together AI introduced Provisioned Throughput — reserved inference capacity for MiniMax M3 and GLM-5.2 with 99% uptime SLA and savings of up to 90% compared with closed APIs.
Together AI raised $800M in Series C to develop open-source AI
Together AI closed its Series C round at $800M with participation from NVIDIA, Aramco Ventures, and Vista Equity — the platform is betting on open-source models that are 6–20x cheaper than closed alternatives.
Together AI: GPT-5.5, Gemini and Opus cannot write fast multi-GPU kernels
The new ParallelKernelBench benchmark showed that the best language models solve fewer than a third of the tasks involving CUDA kernel generation for multiprocessor systems.
Together AI received ISO 27001:2022 certification for enterprise AI workloads
Together AI passed an international ISO 27001:2022 audit — an independent review confirmed the maturity of its information security system for enterprise customers.
Together AI launches MiniMax M3 with 1 million-token context and multimodal support
Together AI partnered with MiniMax to launch M3, a flagship model with support for 1 million tokens of context, native image processing, and inference acceleration of up to 125%.
Together AI at NVIDIA GTC 2026: Dynamo, multi-agent models, and voice AI
At GTC 2026, Together AI unveiled an integration with NVIDIA Dynamo 1.0, launched the NemoClaw stack for agents, and opened access to the 120B Nemotron 3 Super model.
Together AI beat TensorRT-LLM by 31% in benchmarks for code agents
Together Inference Engine delivered 31% more tokens per second and halved TTFT under peak load — the first fair test for production agents.
Together AI Unveiled ATLAS: A Speculator That Accelerates LLM by 4x
Together AI's new ATLAS adaptive-learning speculator technology accelerates LLM inference by 4x without manual tuning—automatically adapting to user workloads.
Together AI Launched Self-Service Instant Clusters on NVIDIA H100 and B200
Together AI officially launched Instant Clusters — self-service GPU clusters based on NVIDIA H100 and B200 that deploy in minutes and are ready for production without lengthy approvals.
Together AI raised Batch Inference API limits 3,000x and cut prices by 50%
Batch Inference API now handles 30 billion tokens (up from 10 million) and costs half as much as the real-time API. It supports all 40+ models on the platform.
Together AI Expanded Its Platform: Fine-tuning Models with 100B+ Parameters
Together AI's fine-tuning platform now trains the most powerful open models — DeepSeek-R1, Qwen3-235B, and Llama 4 — with support for extended contexts and Hugging Face integration.
FlashAttention-3 Will Accelerate Transformers Twofold at 75% GPU Load
Together AI released FlashAttention-3 — an algorithm that accelerates transformers 1.5-2x and utilizes 75% of H100 GPU performance while maintaining low-precision FP8 computation.
Together AI achieves 90% faster training on NVIDIA Blackwell
Together AI announced access to NVIDIA Blackwell GPU clusters with its own optimizations, achieving 90% faster Llama 70B training and 15,264 tokens per second per GPU.
ThunderKittens by Together AI: A New Language for Efficient GPU Kernels
Together AI has unveiled ThunderKittens—a GPU kernel programming language that reads like PyTorch but runs like pure CUDA. On H100, the code runs even faster than classic FlashAttention2.
DSGym: A Framework for Training Data Science Agents with 90+ Scientific Tasks
Together AI released DSGym — a unified framework for evaluating and training LLM agents on data science tasks. It includes 90+ bioinformatics tasks and 92 Kaggle competitions, with a 4B model trained on synthetic data ac
Together AI Explains Why Cloud for AI Is a Completely Different Architecture
AI startups like Cursor iterate weekly and consume GPUs like web apps of 2012. Together AI figured out what cloud infrastructure should look like to keep pace with AI-native companies.
Together AI: How Kernel Optimizations Close the Gap Between Models and GPUs
Together AI's kernel optimization team created technology that accelerates GPU performance by 2-3x. In a week, they adapted kernels for new Blackwell GPUs—work that took NVIDIA a year.
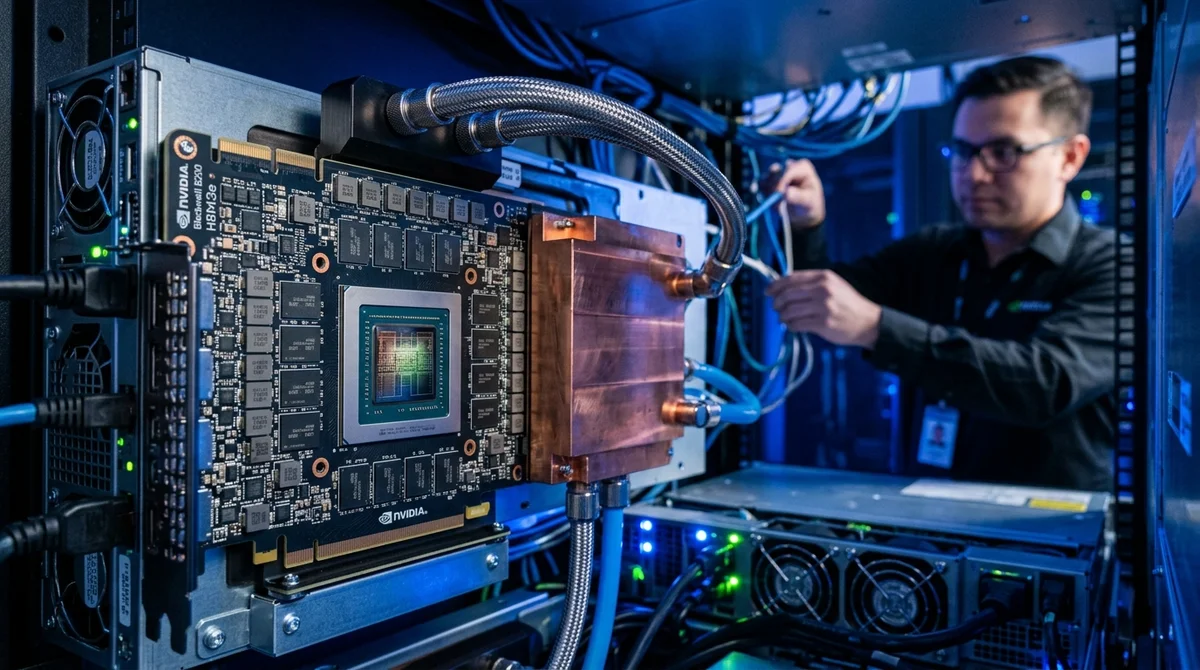
FlashAttention-4: How Together AI Accelerated Attention on Blackwell GPUs
Together AI unveiled FlashAttention-4, an attention algorithm optimization for Blackwell GPUs that achieves 1605 TFLOPs/s and runs 2.7× faster than Triton.