How to Choose AI for Work: Why Benchmarks Don't Help
High AI benchmark scores increasingly fail to translate into real-world value. Angela Aristidou of UCL and Stanford argues that models should be tested not in a vacuum but inside live workflows: how they affect team performance, approval speed, and people's ability to spot errors. Instead of one-off tests, she proposes a HAIC approach — a long-term evaluation of the human + AI pairing in a specific context.
AI-processed from Habr AI; edited by Hamidun News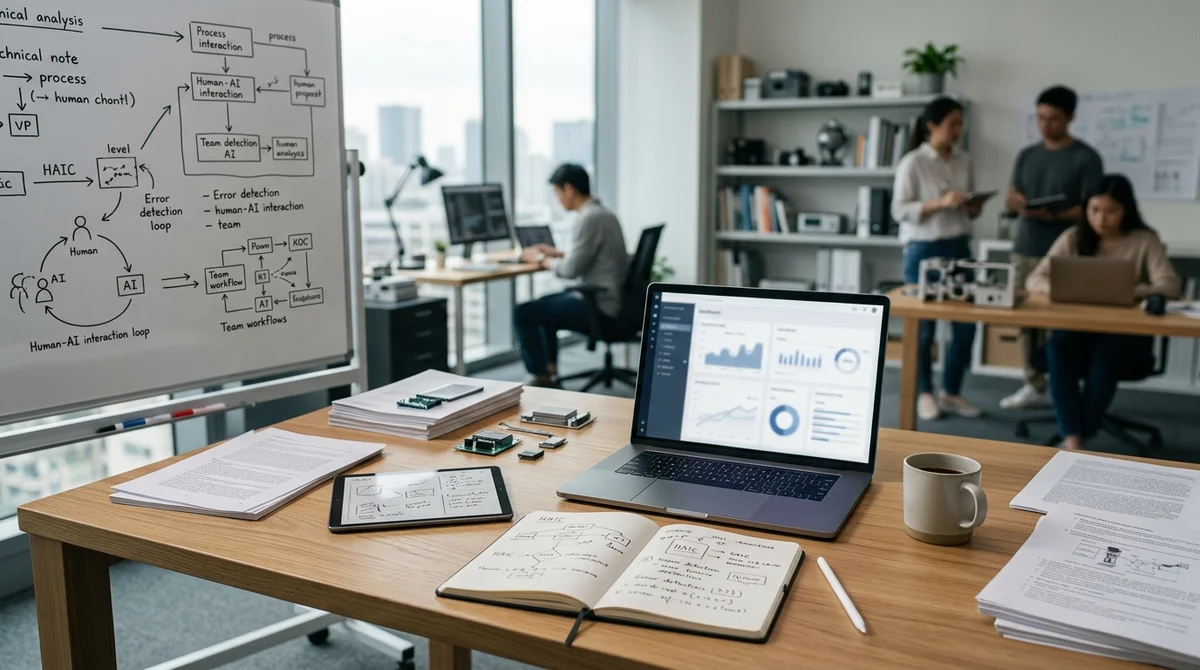
High benchmark scores don't guarantee that an AI model will be useful once it's deployed in real-world workflows.
Why does AI ace tests but fail to help at work?
Today's benchmarks test models on isolated tasks with a single correct answer, but real work requires a system to fit into teams, processes, and long work cycles.
How do I properly assess whether AI will help my company?
According to the researcher, you need to look not at results in a vacuum, but at how systems behave inside real teams, business processes, and full work cycles.
Why don't high test scores help in choosing AI for business?
Because tests evaluate a model on isolated tasks, not on how it performs inside teams, processes, and long work cycles.
Key Questions Answered
Why does AI ace tests but fail to help at work?
Today's benchmarks test models on isolated tasks with a single correct answer, but real work requires a system to fit into teams, processes, and long work cycles.
How do I properly assess whether AI will help my company?
According to the researcher, you need to look not at results in a vacuum, but at how systems behave inside real teams, business processes, and full work cycles.
Why don't high test scores help in choosing AI for business?
Because tests evaluate a model on isolated tasks, not on how it performs inside teams, processes, and long work cycles.
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.