Flag Soft: The "Dali Challenge" Benchmark Helped Pick an LLM on Quality, Speed and Price
While choosing an LLM for his first side project, the author built his own benchmark, the "Dali Challenge," and compared models on quality, speed and cost. The takeaway is practical: a product doesn't need an abstract "best" model, but one that delivers the required level of answers within an acceptable latency and budget. That approach helped find the optimal option to integrate into the company's products.
AI-processed from Habr AI; edited by Hamidun News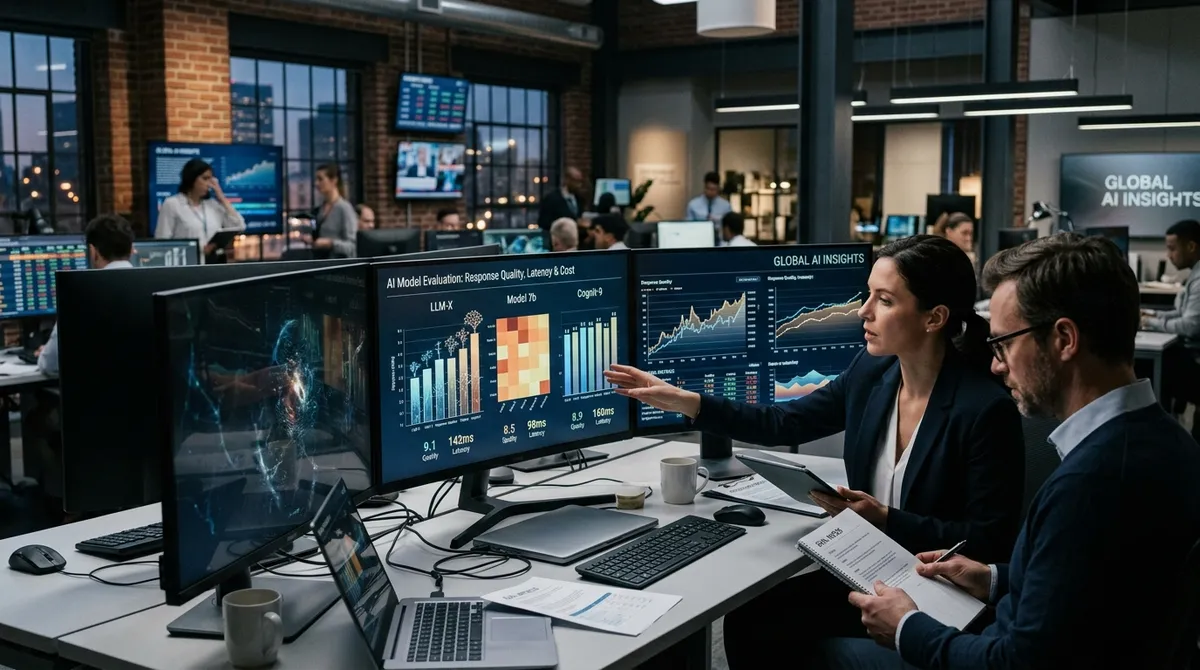
Choosing an LLM for a real product rarely comes down to comparing polished demos. The author of the piece approached the task from a practical angle: while looking for a model for his first side project, he built his own benchmark, the "Dali Challenge," and tested popular LLMs not on bold promises but on three things that actually affect deployment: answer quality, speed and cost.
The idea grew out of an ordinary engineering problem. When you need a model for your own project, the abstract question "which LLM is the best?" quickly turns into a set of practical constraints. One model writes convincingly but responds too slowly. Another fits the budget but loses the thread in long instructions. A third passes tests consistently, but its final price makes it unusable for a mass-market product. That is where the homemade test came from, and it later proved useful not only for a personal experiment but also for product decisions at Flag Soft.
The "Dali Challenge" rests on simple but sound logic. If a model is going to be built into a product, it should be compared not on a one-off impression from a chat, but on an identical set of tasks. In this approach, quality doesn't just mean "I like the answer or I don't."
It means the model's ability to preserve meaning, follow instructions, keep details and produce a result that can be used without lengthy manual editing. Speed matters just as much: for an internal tool you can tolerate a few extra seconds, but in a user-facing service every delay hurts retention and conversion. Cost is the third mandatory parameter, because even a strong model can turn out too expensive when scaled to thousands of requests.
That is the value of the benchmark: it doesn't look for an absolute champion, it shows the balance. In practice, the model that simply writes best almost never wins. The winner is the one that delivers acceptable quality at the right time and at a price compatible with the product's unit economics. For a company that wants to build an LLM into a real service, this is far more useful than flashy tables of abstract scores. This kind of evaluation shows in advance where the bottleneck will appear: in response latency, in the token budget, or in unstable model behavior on similar requests.
The author's applied conclusion is interesting in its own right: the benchmark helped choose not the "smartest" model overall, but the optimal LLM for integration into Flag Soft products. That distinction matters. Teams often start deployment with a top-tier model and then have to fall back to a cheaper or faster alternative. Here the logic is reversed: real requirements are defined first, and a model is selected to fit them. This order reduces the risk of costly rework when the architecture is already tied to a provider that can't sustain the economics, the response speed or the expected level of service.
The author's approach is also useful because it reflects the actual state of the LLM market. Different models can win in different scenarios: text generation, summarization, knowledge search, operator assistance, autocomplete in an interface, or handling customer requests. The same candidate can excel at creative tasks and fail where strict adherence to instructions is required. That is why custom benchmarks are becoming basic hygiene rather than a luxury for any team that plans to pay for a model out of its own budget and answer for the user experience.
The core point of the "Dali Challenge" is simple: choose an LLM the way you choose any infrastructure technology, through verifiable metrics rather than hype. A team with its own set of tasks, a response-time limit and a clear budget will almost certainly get a more accurate answer than from a general leaderboard. For the market, it is one more signal: the era of choosing a model by reputation is ending, and engineering pragmatism is moving to the foreground.
- Oct 30, 2026Inclusion AI speeds up LLM generation by up to 6.9x with a draft tree
- Oct 29, 2026Cloudflare releases open-source Clef models: 98.5% on BFCL and 38.8 ms
- Oct 28, 2026Cline Pushes an Open Model to 11,840 Tokens per Second on a Single GPU
- Oct 28, 2026Researchers release a dataset of 100,000 illustrated articles and a seven-metric benchmark
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.