Hugging Face releases Ecom-RLVE, a training gym for online-store AI agents
Hugging Face has released Ecom-RLVE, an environment for training AI agents that help people buy products in online stores. It contains eight scenarios, from search and cart building to returns and order tracking, plus verifiable rewards for accuracy, efficiency and the absence of hallucinations. Early tests suggest this approach exposes real failures better than ordinary chat benchmarks.
AI-processed from Hugging Face Blog; edited by Hamidun News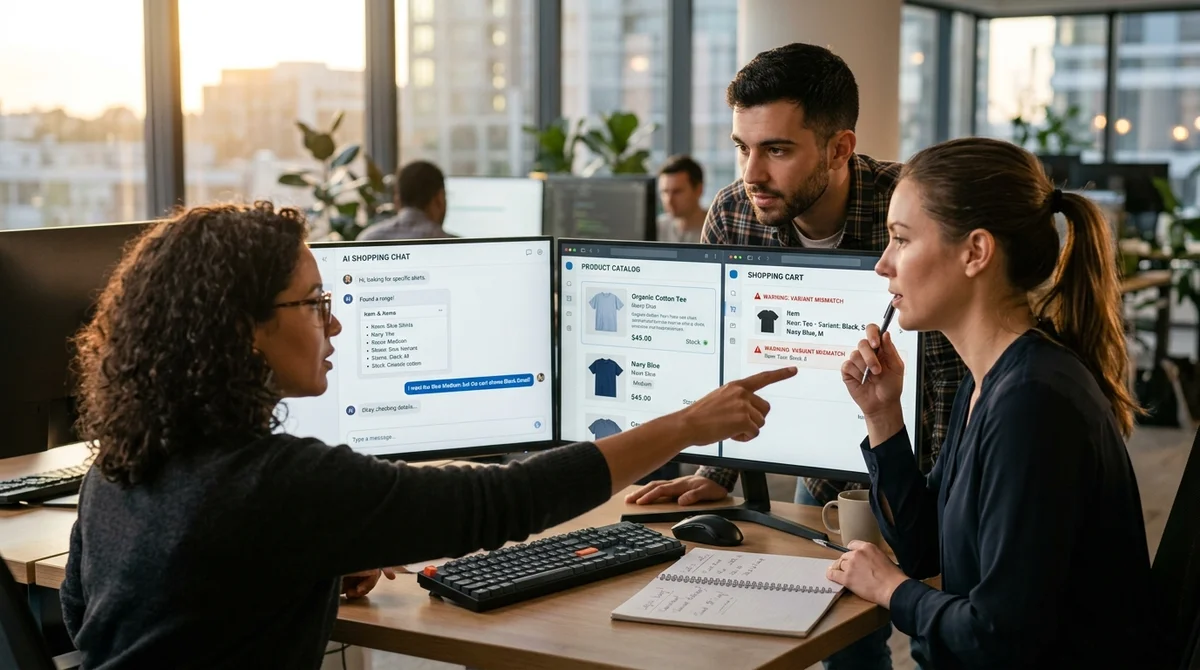
Hugging Face has released Ecom-RLVE, a set of verifiable environments for training conversational AI agents that help people buy products in online stores. The project takes reinforcement learning out of abstract tasks and applies it to real multi-step scenarios: finding a product, choosing a substitute, building a cart, handling returns and tracking an order.
Why older benchmarks fall short
Large language models learned to sound convincing long ago, but in e-commerce that is not enough. A user may ask not just to "find a charger" but to pick a model under $25, with USB-C, two-day delivery and compatibility with a specific device. For an agent this is no longer a chat reply but a chain of actions: find the product page, check the constraints, choose the right variant, avoid mixing up the quantity and avoid inventing something that is not in the catalog.
"Fluent speech is not the same as completing the task."
Ecom-RLVE is built on exactly this gap.
The authors extend the idea behind RLVE-Gym, where models trained on verifiable tasks with an exact reward, and carry it over to conversational commerce. Instead of subjective grading by a human or an LLM-as-a-judge, the environment checks the outcome with code: did the agent land on the right product, pick the correct size or variant, create a return for the right item, and stay within the step limit.
How the environment works
Each episode in Ecom-RLVE consists of a hidden task, a simulated user and a set of tools the agent works with. The agent does not just write text: it calls functions, searches the catalog, adds items to the cart, asks clarifying questions and ends the scenario only when the goal has actually been reached.
The environment covers eight types of situations, from product discovery and product substitution to bundle planning, policy QA, order tracking and multi-intent journey. The reward combines several components, so the model learns not just to "look helpful" but to finish the job:
- a reward for completing the task correctly
- a bonus for fewer steps and fewer tool calls
- a penalty for hallucinations, such as nonexistent SKUs or variants
- a hard failure for invalid actions and for breaking the call format
Adaptive difficulty matters separately. Instead of fixed easy/medium/hard levels, the environment uses a difficulty number d that controls 12 axes at once: the number of constraints, missing details, similar products, typos, out-of-stock items, a change of intent mid-dialogue and other disturbances. This allows curriculum learning without manual labeling and avoids keeping the model too long on tasks that have already become trivial.
Where the model breaks down
The paper examines the Cart Building scenario in detail, where the agent must assemble a cart of several products with exact variants and quantities. To rule out memorizing templates, the developers synthesize variants on the fly: connector type for electronics, size for clothing, material or color for kitchen goods. As a result, the model must do more than "recognize the product"; it has to link the user's request to the right variant in the catalog.
The team trained Qwen 3 8B on this environment with DAPO for 300 steps on the C1 collection, and the benchmark also defines C2, C4 and C8 modes for training on two, four and eight environments. The catalog was scaled to two million products using a FAISS index and gte-modernbert-base embeddings, and the user simulator was built on Qwen3.5-9.7B. According to the results, the agent was able to climb steadily to harder episodes, and its errors became easy to see: the model can pick the right product but miss the variant, forget one item in the order, or claim the needed version does not exist even though it saw it several steps earlier.
What this means
For the AI shopping market this is an important shift: competition can now focus not on how smoothly a bot talks but on how reliably it completes a purchase task. If such open environments catch on, the industry will have a more honest way to train and compare e-commerce agents, based on the real quality of their actions rather than the impression left by a conversation.
- Nov 1, 2026Local models lose to Opus and Codex: 0.21 on a MacBook versus 1.00 for Codex
- Nov 1, 2026Pika Labs releases open video model H3 Flex: 6 steps instead of 50
- Nov 1, 2026Hugging Face's BERT Tokenizer Gets a 50x Speedup by Skipping Needless Work on ASCII
- Nov 1, 2026Illinois compiled 12 151 open problems and tested whether AI can solve them
Key Questions Answered
Why older benchmarks fall short?
Large language models learned to sound convincing long ago, but in e-commerce that is not enough. A user may ask not just to "find a charger" but to pick a model under $25, with USB-C, two-day delivery and compatibility with a specific device. For an agent this is no longer a chat reply but a chain of actions: find the product page, check the constraints, choose the right variant, avoid mixing up the quantity and avoid inventing something that is not in the catalog. "Fluent speech is not the same as completing the task." Ecom-RLVE is built on exactly this gap. The authors e
How the environment works?
Each episode in Ecom-RLVE consists of a hidden task, a simulated user and a set of tools the agent works with. The agent does not just write text: it calls functions, searches the catalog, adds items to the cart, asks clarifying questions and ends the scenario only when the goal has actually been reached. The environment covers eight types of situations, from product discovery and product substitution to bundle planning, policy QA, order tracking and multi-intent journey. The reward combines several components, so the model learns not just to "look helpful" but to finish th
Where the model breaks down?
The paper examines the Cart Building scenario in detail, where the agent must assemble a cart of several products with exact variants and quantities. To rule out memorizing templates, the developers synthesize variants on the fly: connector type for electronics, size for clothing, material or color for kitchen goods. As a result, the model must do more than "recognize the product"; it has to link the user's request to the right variant in the catalog. The team trained Qwen 3 8B on this environment with DAPO for 300 steps on the C1 collection, and the benchmark also defines
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.