NVIDIA shows Gemma 4 running with voice and a webcam on Jetson Orin Nano Super
NVIDIA has built a local Gemma 4 demo for the Jetson Orin Nano Super: the model listens to speech, turns to a webcam on its own when it needs to, and answers through TTS. The stack uses Parakeet for speech recognition, Kokoro for speech synthesis, and llama.cpp with a vision projector. The main takeaway: a multimodal agent runs on a compact 8 GB board without requiring the cloud.
AI-processed from Hugging Face Blog; edited by Hamidun News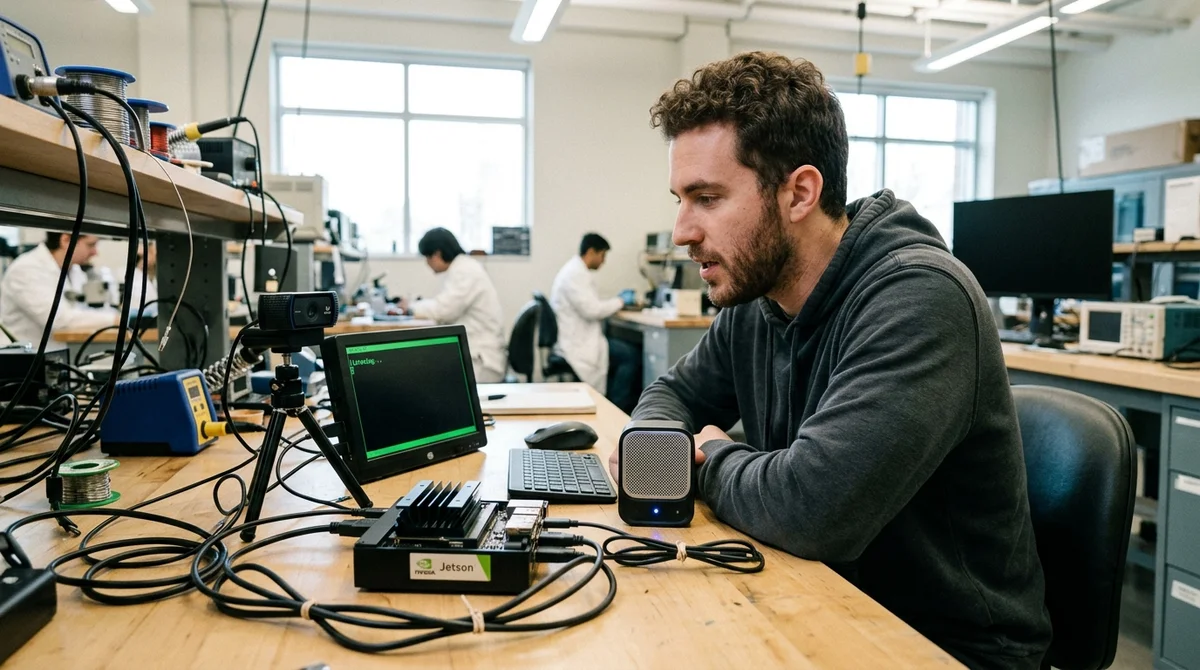
NVIDIA has published a practical edge demo: Gemma 4 listens to a question, turns to a webcam on its own when it needs to, and answers out loud — all locally on a Jetson Orin Nano Super with 8 GB of memory. The April 22, 2026 post is interesting not only as a tutorial, but because the multimodal agent runs on a compact board rather than in the cloud.
How the stack works
The setup is a simple voice agent with a single visual tool. The user presses the spacebar and asks a question out loud, and Parakeet transcribes the speech to text locally. Gemma 4 then receives the request and decides for itself whether it needs to look through the webcam. If it does, the script captures a frame and passes it to the model, and Kokoro TTS reads the answer aloud. The article specifically stresses that the model does not describe the image in general; it uses what it sees only to answer the specific question.
"Honestly, it's impressive that this runs on a
Jetson Orin Nano at all."
The key point is that there are no hard-coded triggers or manual logic along the lines of "if the question contains the word camera." The script exposes exactly one tool to Gemma 4 — `look_and_answer`, which takes a snapshot and analyzes the scene. The model decides on its own whether to call it. To make this work, NVIDIA uses `llama-server` from `llama.cpp` with the `--jinja` flag, which enables native tool calling support. In effect, this is a compact VLA setup where vision kicks in only when it's actually needed.
What you need to run it
The demo isn't out-of-the-box magic. It's better described as a well-assembled guide for enthusiasts and developers who want to reproduce a local multimodal pipeline on their own hardware. NVIDIA covers not just launching a Python script but the entire stack — from system packages and building `llama.cpp` to configuring audio and the camera and downloading the vision projector for Gemma 4.
- A Jetson Orin Nano Super with 8 GB of memory, a webcam, a USB microphone or a camera with a built-in mic, USB speakers, and a keyboard
- A Python environment with `opencv-python-headless`, `onnx_asr`, `kokoro-onnx`, `soundfile`, `huggingface-hub`, and `numpy`
- A locally built `llama.cpp` with CUDA, the `gemma-4-E2B-it` model in GGUF, and a separate `mmproj` file, without which Gemma 4 cannot see
- Setting `MIC_DEVICE`, `SPK_DEVICE`, `WEBCAM`, and `VOICE`, after which the demo launches with a single command: `python3 Gemma4_vla.py`
- A separate text-only mode via Docker if you want to quickly test the LLM part without the full vision setup
Memory gets particular attention. The 8 GB board can handle it, but the author explicitly advises freeing up RAM, shutting down unnecessary processes, and even adding swap to avoid an OOM when loading the model. The quantized `Q4_K_M` is named as the baseline option, and under very tight constraints you can drop down to `Q3`. That's an important detail: this isn't a polished consumer product but a working recipe where every gigabyte makes a real difference.
Why it matters
The news here isn't that Gemma 4 can run on a Jetson — that alone is expected for lightweight builds. What matters more is that NVIDIA shows a practical template for a local multimodal agent that combines STT, an LLM, tool calling, vision, and TTS without requiring a trip to the cloud. For edge devices, that's a strong signal. Until now, setups like this were more often associated either with a server or with heavily stripped-down demos where the model just answers text.
That said, the guide is upfront about the limitations. The first run is slow because models are downloaded and voice files are generated. The full VLA mode requires a native build and the vision projector, while the Docker option works only for text. If the server runs short on memory, you have to clean up the system by hand. NVIDIA also doesn't provide speed benchmarks in the article or show video with real-world latency, so a ready-made assistant for everyone is still a long way off. But as a demonstration of where things are heading, it's a very strong case.
What this means
Local AI agents are getting closer to practical use on inexpensive hardware. For developers, that means they can build private voice interfaces and multimodal prototypes without mandatory cloud infrastructure. For the edge AI market, it's another step away from slick presentations and toward systems you can actually set up on your desk, test, and build into a product.
- Nov 1, 2026Voice bots built on LLMs turn to Jev, a fast classifier, for decisions in 200–500 ms
- Nov 1, 2026Local AI models agreed to pay scammers, while simple rules blocked all 42 schemes
- Oct 31, 2026A 22B-Parameter Video Model Runs on an RTX 3080 with 10 GB of VRAM
- Oct 30, 2026Mistral opens Large 4 weights: strong at code, but Chinese models score 32 to its 26
Key Questions Answered
How the stack works?
The setup is a simple voice agent with a single visual tool. The user presses the spacebar and asks a question out loud, and Parakeet transcribes the speech to text locally. Gemma 4 then receives the request and decides for itself whether it needs to look through the webcam. If it does, the script captures a frame and passes it to the model, and Kokoro TTS reads the answer aloud. The article specifically stresses that the model does not describe the image in general; it uses what it sees only to answer the specific question. "Honestly, it's impressive that this runs on a Je
What you need to run it?
The demo isn't out-of-the-box magic. It's better described as a well-assembled guide for enthusiasts and developers who want to reproduce a local multimodal pipeline on their own hardware. NVIDIA covers not just launching a Python script but the entire stack — from system packages and building `llama.cpp` to configuring audio and the camera and downloading the vision projector for Gemma 4. A Jetson Orin Nano Super with 8 GB of memory, a webcam, a USB microphone or a camera with a built-in mic, USB speakers, and a keyboard A Python environment with `opencv-python-headless`,
Why it matters?
The news here isn't that Gemma 4 can run on a Jetson — that alone is expected for lightweight builds. What matters more is that NVIDIA shows a practical template for a local multimodal agent that combines STT, an LLM, tool calling, vision, and TTS without requiring a trip to the cloud. For edge devices, that's a strong signal. Until now, setups like this were more often associated either with a server or with heavily stripped-down demos where the model just answers text. That said, the guide is upfront about the limitations. The first run is slow because models are download
Delegate Deep Research, Coding & Multi-Step Workflows to Nomad Agent
Deploy autonomous task execution with Nomad Agent (agent.nomadnet.ai) — automated web research, data synthesis, code generation, and MCP tool orchestration.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.