Why Diffusion Models Leave Seams on 40-Megapixel Photos, and How to Give Tiles a Memory
Diffusion models handle ordinary images well, but on professional frames of 40–150 MP, tiling almost inevitably leaves seams, drifting color and broken textures. The piece examines why photo models cannot keep memory between neighboring tiles, and which ideas from video diffusion, from FramePack to AnimateDiff, could help fix that. The author argues the limit is not just hardware or image size, but the architecture of photo diffusion itself.
AI-processed from Habr AI; edited by Hamidun News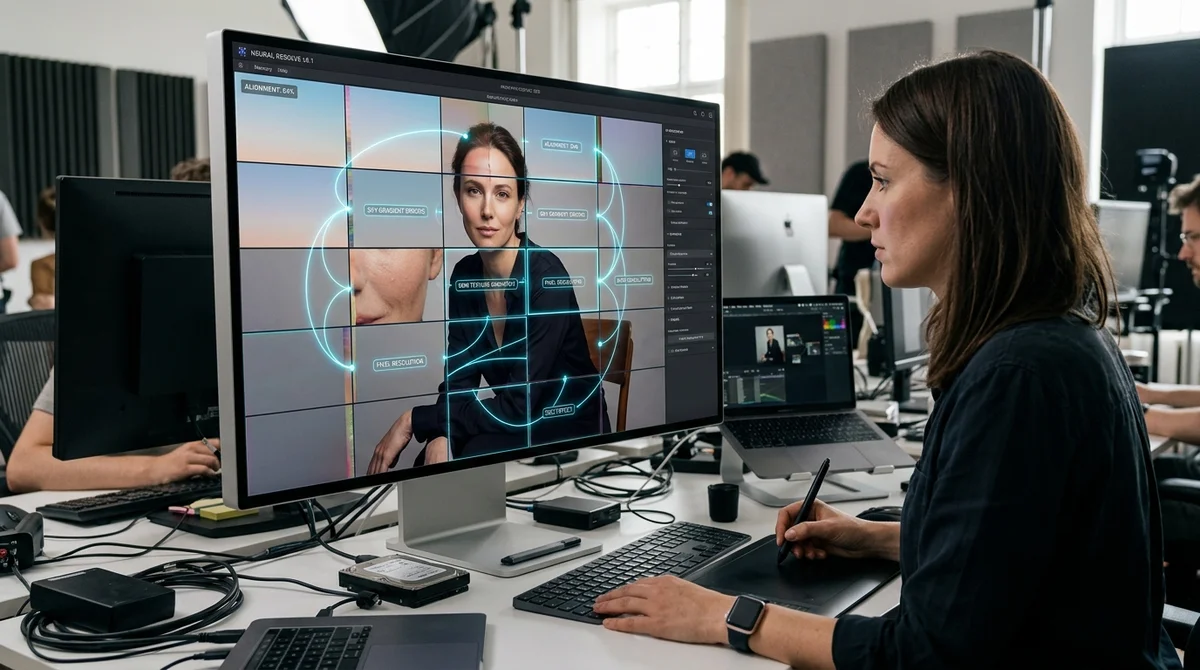
The main cause of seams on ultra-large images turns out not to be poor stitching, and not only a shortage of VRAM. The problem runs deeper: diffusion photo models do not keep memory between neighboring parts of an image. When a 40–150-megapixel frame is cut into dozens or hundreds of tiles, the model makes each decision from scratch. It does not know which shade of sky, skin tone or texture scale it has already chosen next door. That produces banding on gradients, drifting color and visible joins, which hurt most in professional retouching.
The author approaches the topic from practice, not theory: he has twenty years of retouching behind him and four years of trying to adapt diffusion models to production. In studio, advertising and magazine photography, high resolution is not a luxury but a working standard, and such frames rarely fit into a single generation or editing pass. So the industry keeps returning to the same trick: split the picture into 100 or more fragments, process them separately, then reassemble them. On small details this can work tolerably, but on skin, fabric, backgrounds and light transitions, artifacts are almost unavoidable.
The root of the problem is that ordinary tiling preserves local detail but breaks global consistency. Each tile sees only its own piece of the scene and has no idea what is happening to the left, right, above or below. Even when neighboring areas overlap, the model can still shift the color balance slightly, interpret grain differently, add mismatched pores or build a different rhythm of texture. Blending and masks hide some of the defects but do not remove the cause: a photo model has no mechanism that links decisions between neighbors. That is why a perfect stitch on very large frames remains more the exception than the norm.
The article proposes looking to video diffusion, where consistency has long been central to the architecture. A video model must remember how an object looked in the previous frame so it does not lose the face, light, texture and position of details as things move. The author reviews eight classes of such memory, from BCLA in SANA-Video and FramePack to SVD reshape, AnimateDiff and other approaches, and assesses what can be transferred to tiles and what cannot.
The key question is not the name of the method but the principle: can a photo model be made to pass compact context, a hidden state or a shared scene structure to the neighboring fragment, so that decisions are not made in a vacuum?
Three broad ideas for practice follow from this. The first is context exchange between neighboring tiles, where the model receives not only the current fragment but also compressed information about areas already processed. The second is shared memory at the level of latents or attention mechanisms, which holds color, lighting and surface character constant across the whole image. The third is a multi-step scheme in which a rough global representation of the entire scene is built first, and local tiles then only refine details without breaking the overall picture. For print, outdoor advertising, beauty retouching and commercial photography this is critical: any texture break or tonal jump is immediately visible there.
The main conclusion is simple: the limit is not only hardware and not only image size, but the architecture of photo diffusion itself. Until a model learns to remember what has already happened next door, processing 40-megapixel and larger frames will remain a compromise between detail and integrity. If video memory mechanisms can be adapted to tiles, diffusion models will take a noticeable step from flashy demos toward a full professional tool for retouching and post-production.
- Nov 12, 2026Google opens preorders for Gemini glasses starting at $395 and blocks covert recording
- Nov 12, 2026Samsung Is Preparing a Paid Galaxy AI Subscription: From $4.99 a Month and Credits Instead of Unlimited Use
- Nov 12, 2026Adobe showcases four AI prototypes at Max: 3D from photos, a sound square, and copy-and-paste edits
- Nov 12, 2026Instagram launches prompt-based filter creation for users aged 18+ in the US
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.