Local LLMs
Local LLMs are language models that run directly on your own hardware — a laptop, a PC with a GPU or a home server — with no cloud, no subscriptions and no data leaving your machine. Ollama, llama.cpp and LM Studio, plus quantized GGUF builds of Llama, Qwen and Gemma, make it possible even on a decade-old graphics card. Here is all our coverage of running AI locally: guides, hardware tests, quantization and privacy.
Zhipu GLM-OCR: How Chinese Tech Giant Taught Micro-Model to See Everything
The artificial intelligence industry has long resembled a bodybuilders' off-season competition: each new announcement was accompanied by bragging about the number…
Claude Code on a Diet: How to Run an AI Programmer for Free and Locally
The dream of an AI that writes code for you has finally taken tangible form, but, as usual, with a caveat in the form of a monthly subscription.
Nemotron-3-Nano-30B: NVIDIA Taught 4-Bit Models to Think Like Adults
Remember when running a decent language model required a server rack and a small nation's budget? Those days are rapidly becoming history.
The Distillation of Mind: Why Neural Networks Are Harmed by Teachers That Are Too Smart
Distillation of Mind: Why Neural Networks Suffer from Overly Clever Teachers Imagine you're trying to explain quantum electrodynamics to a first-grader.
AI Sovereignty: Myth or Reality in the Age of Globalization?
The aspiration for "sovereign AI" is becoming a global trend. Governments worldwide plan to invest approximately $1.3 trillion into artificial intelligence…
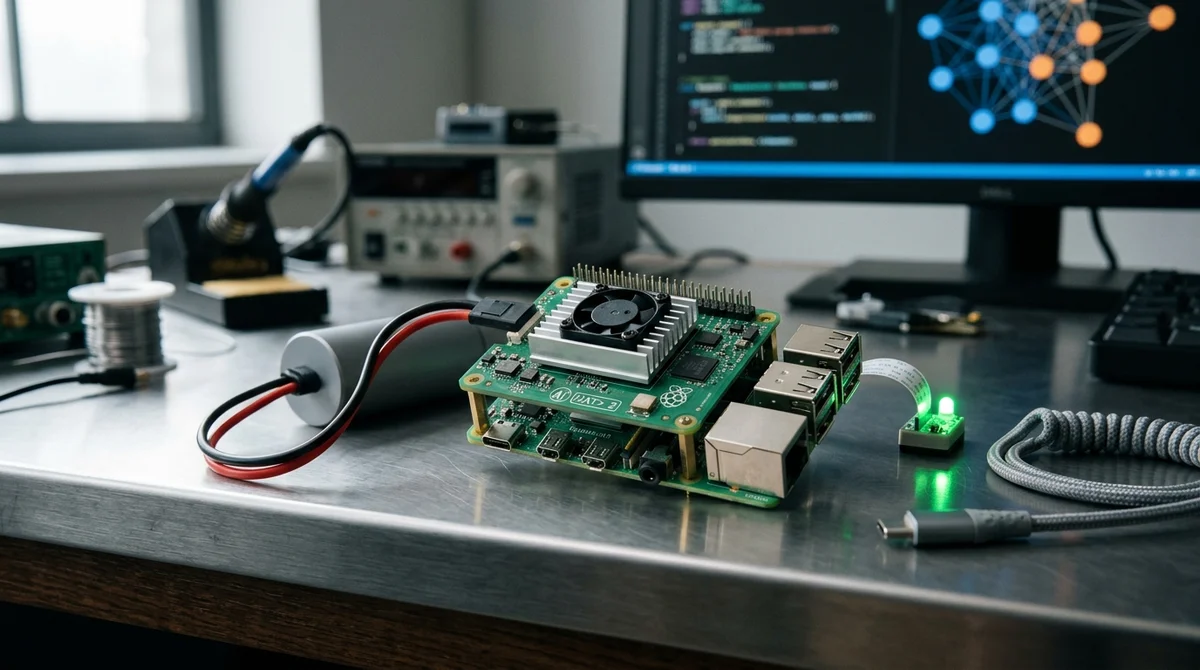
Raspberry Pi launches board for running generative AI locally
Raspberry Pi is betting on local artificial intelligence with the release of its new AI HAT+ 2 expansion board.