Habr AI breaks down a virtual camera for Shorts and Reels with face tracking
Habr AI has published a detailed breakdown of a virtual camera for Shorts and Reels. Instead of simple autocropping, the author built a production pipeline with a cascade of detectors, face tracking, anti-jerk filtering and a physical model of camera motion. The result is a vertical frame that behaves not like a jittery cropper but like an operator with inertia and a fallback mode. There is also a soft Ken Burns transition for when the face disappears from the frame.
AI-processed from Habr AI; edited by Hamidun News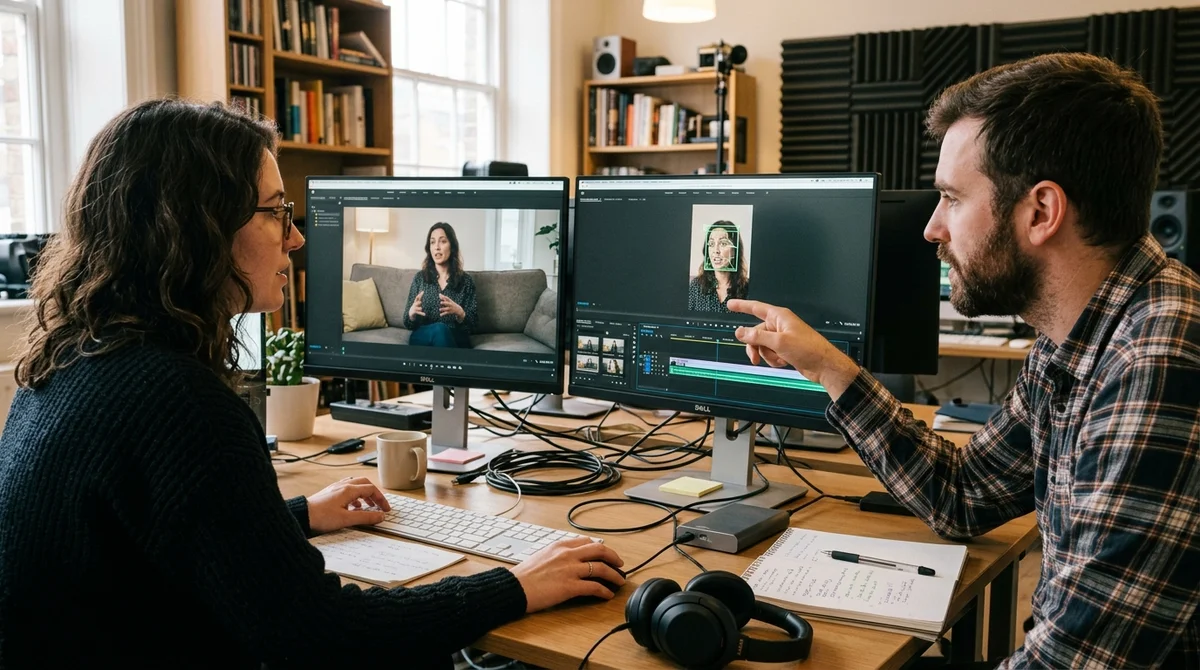
Habr AI has published a detailed breakdown of a virtual camera for vertical video that turns an ordinary horizontal clip into Shorts or Reels without jerky autocropping. The author describes a production pipeline in which the camera follows the face not by a single bounding box, but as a separate dynamic system.
Why autocrop breaks down
On paper the task looks simple: take a 16:9 source frame, cut a 9:16 window out of it and keep the person centered. In real footage this approach falls apart quickly. The face can drift left or right, a second person can enter the frame, and the detector itself will alternately produce noise or lose the target on a head turn, a glare or a gesture. As a result, the vertical clip starts to look like an old autofocus: the picture jumps nervously and keeps getting the composition wrong.
The author proposes treating the task not as autocropping but as a virtual camera with its own inertia, speed limit, reaction delay and fallback logic. That is why it is not enough for the system to simply "follow the center of the box." It has to work over time, tolerate imprecise data, not panic over brief face losses, and keep the motion meaningful even in scenes with no faces in the frame at all. This is critical for long segments.
«A camera is not a coordinate, but a dynamic system».
How the pipeline works
The core of the solution is a three-level face detection chain: MediaPipe → YuNet → Haar Cascade. The first detector is the main workhorse, the second serves as a backup ONNX backend via OpenCV, and the third remains the last line of defense when everything else is unavailable or has performed poorly. Externally, the chain returns a single data format: face center, size, confidence and bounding box. Because of this, the rest of the system does not depend on a specific detector and can run stably even in degraded mode.
On top of detection sits simple but practical tracking: the system compares the face center from the previous frame with the current candidates and picks the nearest object. If the face disappears briefly, a grace period kicks in: the camera trusts the last known position for a short time so it does not jerk on a single error. After that, the signal is cleaned in two additional steps and gets a separate fallback for scenes without faces in the clip.
- Anti-jerk clips overly large coordinate jumps between frames
- Low-pass filter smooths residual noise and micro-jitter
- Ken Burns fallback takes over the scene if the face is lost or absent altogether
- Path interpolation turns analysis at 8 FPS into smooth motion for the final 30 or 60 FPS
In the final stage the system does not merely store discrete camera states but builds a continuous path. Then, for each frame, it takes the center and zoom, computes the ROI, cuts out the required area and scales it to the final vertical format. This keeps the pipeline computationally reasonable: analysis can run on a downscaled copy of the video, while the final crop is made from the original, without losing motion smoothness in the final render.
How the camera becomes an operator
The most interesting part is the motion model. Instead of jumping instantly to the target point, the camera is described as a damped oscillator: it has "mass," stiffness, damping, and limits on acceleration and maximum speed. This scheme provides inertia and makes the movement believable. If the person starts moving faster, a predictive lead can be added so the camera looks slightly ahead rather than only catching up with the target. Paradoxically, a small artificial delay, or human lag, also improves the result: a perfectly precise reaction often looks less natural than a slightly slowed one.
On top of the physics, the author layers compositional rules. The camera can shift the face toward the rule-of-thirds lines, raise the focal point closer to eye level, ignore micro-movements inside a dead zone, and leave a safe face margin so it does not cut off ears, hair and gestures at the frame edges. For talking-head scenes there is a separate single-face mode with more conservative speed and stronger stabilization, and for clips without faces, a soft transition to Ken Burns with panning and zoom instead of a "frozen" center.
What this means
This breakdown shows well where AI video editing tools are heading. Quality here comes not from a single "magic" model but from engineering assembly: fallback detectors, tracking, filtering, motion physics and composition working together. For content creators and teams that mass-cut long videos into Shorts and Reels, this is no longer a toy autocrop but a practical template for a production camera that can be reproduced and adapted to different shooting styles.
- Nov 2, 2026The Verge reviewer builds a $50 Meta Muse Charm alternative with Claude Code
- Nov 2, 20268 Skills for video in Claude Code: from 244 pixel effects to rough-cut editing
- Nov 1, 2026Pika Labs releases open video model H3 Flex: 6 steps instead of 50
- Nov 1, 2026Google's StreamVibe video agent beats other models by 10.7% on response timing and quality
Key Questions Answered
Why autocrop breaks down?
On paper the task looks simple: take a 16:9 source frame, cut a 9:16 window out of it and keep the person centered. In real footage this approach falls apart quickly. The face can drift left or right, a second person can enter the frame, and the detector itself will alternately produce noise or lose the target on a head turn, a glare or a gesture. As a result, the vertical clip starts to look like an old autofocus: the picture jumps nervously and keeps getting the composition wrong. The author proposes treating the task not as autocropping but as a virtual camera with its o
How the pipeline works?
The core of the solution is a three-level face detection chain: MediaPipe → YuNet → Haar Cascade. The first detector is the main workhorse, the second serves as a backup ONNX backend via OpenCV, and the third remains the last line of defense when everything else is unavailable or has performed poorly. Externally, the chain returns a single data format: face center, size, confidence and bounding box. Because of this, the rest of the system does not depend on a specific detector and can run stably even in degraded mode. On top of detection sits simple but practical tracking:
How the camera becomes an operator?
The most interesting part is the motion model. Instead of jumping instantly to the target point, the camera is described as a damped oscillator: it has "mass," stiffness, damping, and limits on acceleration and maximum speed. This scheme provides inertia and makes the movement believable. If the person starts moving faster, a predictive lead can be added so the camera looks slightly ahead rather than only catching up with the target. Paradoxically, a small artificial delay, or human lag, also improves the result: a perfectly precise reaction often looks less natural than a
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.