SD Studio turns local Stable Diffusion into a "personal Midjourney" with an LLM assistant
SD Studio is an attempt to turn local Stable Diffusion into a practical working tool rather than a pile of manual settings. The author connected the generator to a local LLM that pulls context from lore files, builds the prompt and sends the job to SD with preset parameters. The result is noticeably less routine work, faster iteration and lower costs for pet projects.
AI-processed from Habr AI; edited by Hamidun News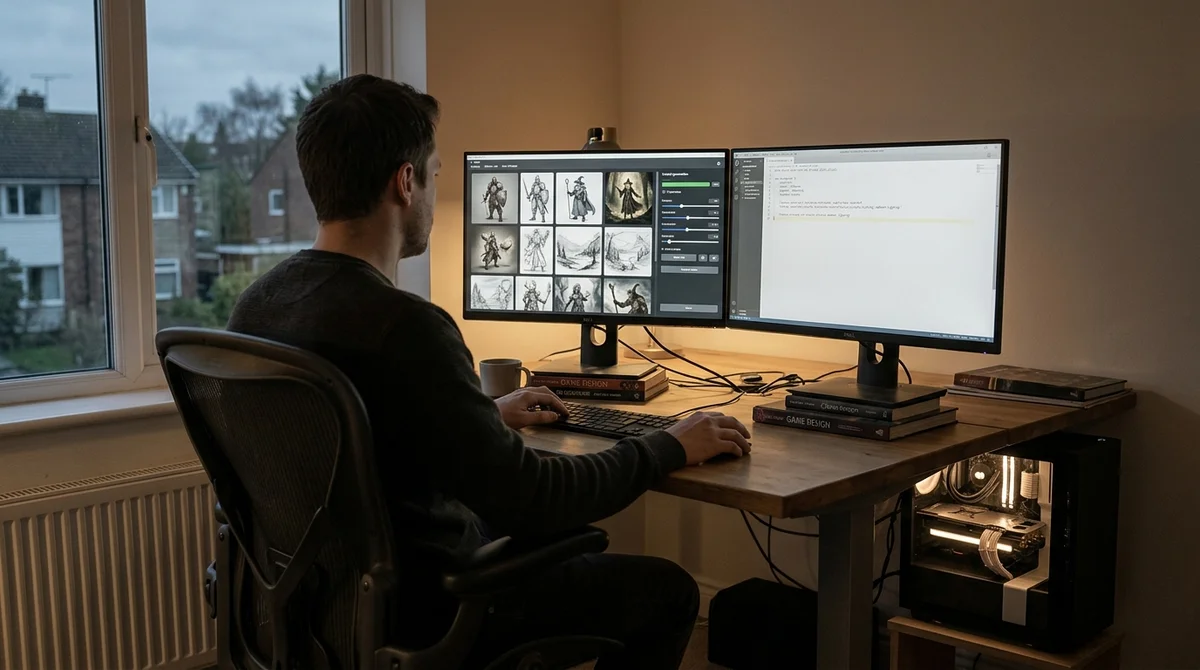
SD Studio offers a practical way to turn local Stable Diffusion into almost a "personal Midjourney" without recurring payments to outside services. At its core is a combination of SD Studio, a local LLM and a preconfigured pipeline that assembles the prompt itself and sends the generation job.
Why it was needed
The story began with a very mundane task: a text-based fantasy game needed illustrations, and nobody on the team can draw. Paid image generators solve the problem quickly, but for a pet project the costs start to bite already at the trial-and-error stage. So the choice fell on local Stable Diffusion: with your own GPU, you can generate as much as you like and not count every attempt as a separate purchase.
The first tool was Automatic1111, a popular interface for working with local SD. But the start was far from magical: the first results were weak and matched expectations poorly. After that, the author followed the typical path of any Stable Diffusion user: digging into ready-made models, plugging in LoRA and checking which combinations suit the specific task best. At this stage quality improved noticeably, but the complexity of the process grew along with it.
Why manual tuning falls short
In practice, the problem turned out to be not the generation itself but the preparation of inputs. To get an image, it is not enough to write a couple of words and wait for a miracle: you need to describe precisely the scene, style, character details and important constraints. Separately, you have to pick the sampler, the number of steps and other parameters. Each iteration produces a new result but takes time, and when the game has dozens of such scenes, the manual mode becomes a bottleneck.
"The model does not read the user's mind."
This is where the article's main thesis shows: a local generator is cheaper than SaaS services, but you pay with the user's time. If a single illustration requires rewriting the prompt several times, switching models, trying different LoRA and then picking a good frame, the cost savings are quickly eaten up by complexity. For a developer, this is no longer just a creative tool but a set of operations that you want to turn into a repeatable pipeline.
How SD Studio works
To remove the routine, the author built generation into an existing Symfony admin panel, which is already used to fill in the game's content. Next to it sits a folder with lore: descriptions of the world, characters and details of the universe. On this basis he built two providers: one works with a local LLM and prepares a correct prompt from the lore data, the other talks to Stable Diffusion and sends the job with the right settings.
- the local LLM extracts the needed context from the lore files
- from that context, a more precise generation prompt is built
- the SD provider fills in the model, LoRA and preset parameters
- the system runs several attempts to raise the chance of a good result
This approach does not make the process fully automatic, but it greatly reduces manual work at the most expensive point: the start of each generation. The user no longer has to work out from scratch how to describe the scene and which settings to choose, and instead gets a prepared pipeline with a clear input. The final stage still belongs to a human: a good image needs cleanup in Photoshop, removal of extra artifacts and preparation of the file for use in the game.
What this means
SD Studio shows a clear scenario for a local AI tool: the value lies not only in the model but in the tooling around it. If an LLM can take context from working materials and assemble prompts automatically, Stable Diffusion on a home GPU stops being an enthusiast's toy and becomes a working tool for small teams and pet projects.
- Oct 29, 2026Modal Passes $1B ARR and Hits a $16B Valuation on Demand for Sandboxes
- Oct 26, 2026Getty Images Says It Will File for Bankruptcy to Go Private; Shares Fall 68%
- Oct 26, 2026Getty Images files for bankruptcy to restructure as shares crash 68%
- Oct 26, 2026Getty Images prepares to file for bankruptcy: shares plunge 68% as owners put in $533 million
Key Questions Answered
Why it was needed?
The story began with a very mundane task: a text-based fantasy game needed illustrations, and nobody on the team can draw. Paid image generators solve the problem quickly, but for a pet project the costs start to bite already at the trial-and-error stage. So the choice fell on local Stable Diffusion: with your own GPU, you can generate as much as you like and not count every attempt as a separate purchase. The first tool was Automatic1111, a popular interface for working with local SD. But the start was far from magical: the first results were weak and matched expectations
Why manual tuning falls short?
In practice, the problem turned out to be not the generation itself but the preparation of inputs. To get an image, it is not enough to write a couple of words and wait for a miracle: you need to describe precisely the scene, style, character details and important constraints. Separately, you have to pick the sampler, the number of steps and other parameters. Each iteration produces a new result but takes time, and when the game has dozens of such scenes, the manual mode becomes a bottleneck. "The model does not read the user's mind." This is where the article's main thesis
How SD Studio works?
To remove the routine, the author built generation into an existing Symfony admin panel, which is already used to fill in the game's content. Next to it sits a folder with lore: descriptions of the world, characters and details of the universe. On this basis he built two providers: one works with a local LLM and prepares a correct prompt from the lore data, the other talks to Stable Diffusion and sends the job with the right settings. the local LLM extracts the needed context from the lore files from that context, a more precise generation prompt is built the SD provider fi
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.