AWS shows semantic video search on Amazon Bedrock with Nova Multimodal Embeddings
AWS has shown how to build semantic video search on Amazon Bedrock and released a reference implementation. Clips are cut at scene changes, each segment gets separate embeddings for image, audio and speech, and everything is then blended with metadata in a hybrid search. In AWS's tests, this setup clearly beats the baseline mode on retrieval accuracy.
AI-processed from AWS Machine Learning Blog; edited by Hamidun News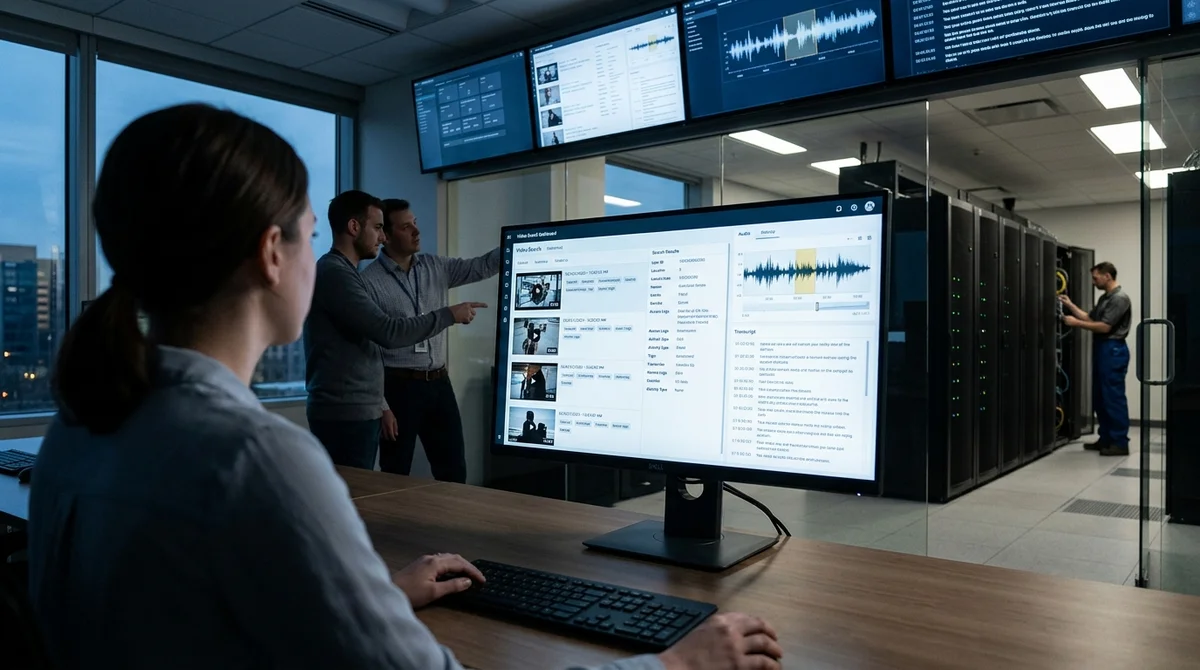
AWS has published a reference architecture for semantic video search on Amazon Bedrock using Amazon Nova Multimodal Embeddings, along with an implementation you can deploy on your own content. Instead of the classic approach, where everything is reduced to a transcript, the system weighs image, sound, speech and structural metadata at the same time.
Why text is not enough
Video search is usually built around text: speech transcripts, manual tags or automatically generated captions. AWS takes a different approach and says outright that converting an entire video to text loses important signals. If a user searches for "a tense car chase with sirens", the query mixes a visual event with an audio scene. If you need a specific athlete, he may be visible on screen while his name is never spoken. For such cases, a transcript alone is genuinely not enough.
The solution is therefore built on splitting a clip into meaningful segments rather than arbitrary timer-based chunks. Nova Multimodal Embeddings supports up to 30 seconds per embedding, but in its example AWS targets segments of roughly 10 seconds and shifts the boundaries to actual scene changes using FFmpeg. The algorithm keeps segments within a 5 to 15 second range: if a natural shot transition is nearby, the segment is cut there; if not, a hard boundary is set. This preserves context and avoids cutting a scene in the middle of an action or a sentence.
How the system is built
The architecture has two paths: ingestion and search. After a video is uploaded to Amazon S3, orchestration passes to Lambda and Step Functions, and the segments are then processed in parallel by several branches. For each segment, the system builds separate representations of the visual signal, audio and speech, then assembles them with metadata into an index. On the search side, a query does not go to a single shared vector: it is split across several channels and then re-ranked based on the user's intent.
- The video lands in S3 and triggers the pipeline via Lambda and Step Functions
- Fargate with FFmpeg detects scene changes and cuts the clip into semantic segments
- Nova Multimodal Embeddings creates vectors for image and audio, while Amazon Transcribe provides the basis for speech embeddings
- Amazon Nova 2 Lite and Rekognition add segment captions, genre and recognition of known people on screen
- OpenSearch and S3 Vectors store the index, combining vector search with exact text search
AWS puts particular emphasis on not collapsing visual, audio and speech embeddings into a single vector if you want controllable accuracy. In this design, the image covers objects, actions and frame composition, the audio covers music, noise and acoustic atmosphere, and the transcript covers the meaning of what is said. On top of this sits a lexical layer over metadata: titles, dates, genres, names and other entities that semantic search may catch less reliably.
How accuracy improves
The key element of the whole design is a query intent router. AWS uses Claude Haiku in Amazon Bedrock to return, for each query, JSON with weights for four channels: visual, audio, transcription and metadata. The weights must sum to 1.0, and channels with a share below 5% are not run at all, to avoid extra calls and added latency. Results from the different sources are then normalized to a 0–1 scale and merged with a weighted average, rather than by treating all signals equally.
In tests, the approach looks considerably better than the baseline AUDIO_VIDEO_COMBINED scheme. AWS ran a benchmark on 10 internal long videos lasting 5 to 20 minutes and 20 queries of various types. The hybrid scheme reached Recall@5 of 90% versus 51%, Recall@10 of 95% versus 64%, MRR of 90% versus 48%, and NDCG@10 of 88% versus 54%. The company also highlights storage economics: according to AWS, Amazon S3 Vectors can cut the cost of storing and querying vectors by up to 90% compared with specialized alternatives.
What this means
AWS is not just describing an embedding model here; it is offering a practical template for product teams working with media libraries, broadcast archives, sports, educational content or user-generated video. The main idea is simple: the less you try to force a video into a single text or a single vector, the better your chances of finding the right moment accurately and quickly.
- Oct 31, 2026Worldwide Express hands disputed invoices to AI agents and cuts unresolved disputes by 75%
- Oct 30, 2026AWS gives coding agents a live site preview straight from an isolated session
- Oct 30, 2026MoEngage Opens 400 Private APIs to AI Agents Through AgentCore Gateway, Without Building Its Own MCP Servers
- Oct 29, 2026NVIDIA Nemotron 3.5 Super VL: 120B Parameters, 12B Active, Running on AWS
Key Questions Answered
Why text is not enough?
Video search is usually built around text: speech transcripts, manual tags or automatically generated captions. AWS takes a different approach and says outright that converting an entire video to text loses important signals. If a user searches for "a tense car chase with sirens", the query mixes a visual event with an audio scene. If you need a specific athlete, he may be visible on screen while his name is never spoken. For such cases, a transcript alone is genuinely not enough. The solution is therefore built on splitting a clip into meaningful segments rather than arbit
How the system is built?
The architecture has two paths: ingestion and search. After a video is uploaded to Amazon S3, orchestration passes to Lambda and Step Functions, and the segments are then processed in parallel by several branches. For each segment, the system builds separate representations of the visual signal, audio and speech, then assembles them with metadata into an index. On the search side, a query does not go to a single shared vector: it is split across several channels and then re-ranked based on the user's intent. The video lands in S3 and triggers the pipeline via Lambda and Ste
How accuracy improves?
The key element of the whole design is a query intent router. AWS uses Claude Haiku in Amazon Bedrock to return, for each query, JSON with weights for four channels: visual, audio, transcription and metadata. The weights must sum to 1.0, and channels with a share below 5% are not run at all, to avoid extra calls and added latency. Results from the different sources are then normalized to a 0–1 scale and merged with a weighted average, rather than by treating all signals equally. In tests, the approach looks considerably better than the baseline AUDIO_VIDEO_COMBINED scheme.
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.