OTUS: Why Language Models Hallucinate and Which Measures Reduce the Risk of Errors
LLM hallucinations are not a rare bug but a systemic limitation of generative AI. OTUS explains why models confidently mix up facts, invent sources and make mistakes in code, support and analytics, and why fine-tuning does not solve the problem entirely. The practical takeaway is simple: for every critical scenario you need retrieval, validation, test cases, monitoring and a human in the loop.
AI-processed from Habr AI; edited by Hamidun News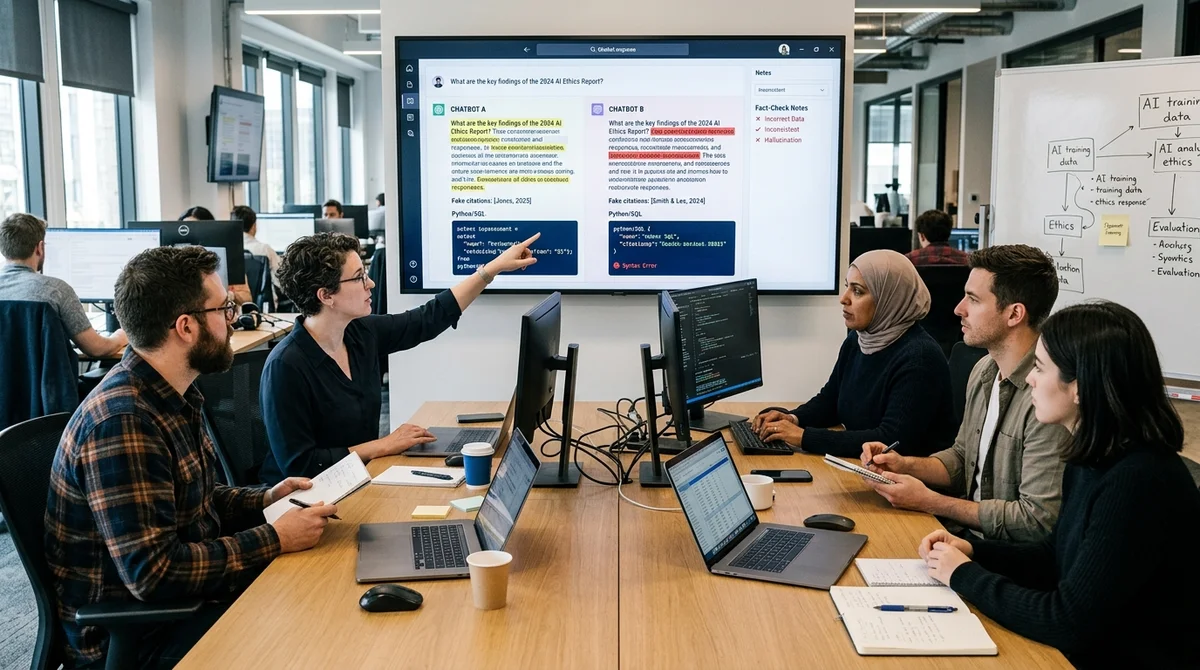
Language model hallucinations are not a rare glitch but a basic property of generative AI: a system can sound confident even where it has no facts. For teams that build LLMs into a product, support, analytics or internal processes, this means more than mere inaccuracy. It is a very concrete operational risk.
Where the error comes from
A language model does not verify truth the way a human or a search engine does. Its task is to predict the most likely continuation of a text, based on a huge body of data and statistical links between words. If the query lacks context, the wording is ambiguous or the training data has few reliable examples, the model still tries to produce a coherent answer.
This is what users perceive as lying: the text looks logical, the tone is confident, and the facts may be invented or blended together.
The problem gets worse in scenarios where the model is expected to supply exact references, figures, legal wording, medical recommendations or code. In such tasks an LLM can not only mix up a source but also fill in missing details from a template: invent a study, cite a non-existent law, name the wrong API version or suggest a program fragment that looks like it works but is unsafe. The more plausible an answer looks on the surface, the higher the risk that the error moves on through the process unchecked.
Why fine-tuning is not enough
The intuitive idea of "let's just fine-tune the model and remove hallucinations" works only partly. Fine-tuning does help a model behave better in a specific domain, follow the answer format and drift less often into obvious fantasy. But it does not turn the model into a system that knows only verified facts and is guaranteed to stop when data runs out. The model is still optimized for plausible text, not for the truth of each statement.
Even large, well-tuned models keep making mistakes on rare cases, recent events, narrow specialist topics and long chains of reasoning. The more steps between question and answer, the greater the chance that an inaccurate assumption appears in one of the links. That is why the problem is not solved by a temperature setting, a new dataset or a magic prompt. You need an architecture in which the model is not the sole source of truth and does not make critical decisions without external grounding.
How to reduce the risk
In practice, the working approach is not to wait for perfect behavior from the LLM but to build protective layers around it. The more an error costs the business, the more checks, restrictions and explicit rules for declining to answer the pipeline should have.
This changes how deployment is approached: instead of asking how to make the model never err, a different question appears: how to make sure an error does not become an incident. That is a matter of system design, not model magic.
- Connect retrieval and let the model answer only from the documents it finds
- Require references to specific data fragments, not to abstract sources
- Separate generation from validation: one step writes the answer, another checks facts and format
- Limit the scope of the task so the model does not improvise outside its domain
- Add a human in the loop for legal, financial, medical and production scenarios
Monitoring and testing matter separately. A team needs sets of test cases, metrics by error type and a log of situations where the model refused to answer or still gave a wrong result. It helps to compare LLM behavior with ordinary deterministic rules and see where automation really speeds up work and where it creates hidden risk. If a system writes code, talks to customers or draws conclusions from data, its errors should be analyzed as systematically as bugs in an ordinary product.
What this means
Hallucinations are not an annoying exception but a limitation of this class of technology. So the teams that win are not those who blindly trust a smart-sounding answer, but those who design the LLM as a probabilistic component with checks, boundaries of use and a clear cost of error.
- Oct 28, 2026Anthropic reveals how it builds Claude with Claude: the brain separate from the hands
- Oct 28, 2026Bayer Launches Multi-Agent Engine on AgentCore: 80% of Questions Handled Without Engineers
- Oct 28, 2026Liquid AI releases LFM2.5-24B-A2B: an agent model with 2B active parameters
- Oct 28, 2026AgentOrch: Pre-Planned AI Agents Now Trail Step-by-Step Execution by Just 8.5 Points
Key Questions Answered
Where the error comes from?
A language model does not verify truth the way a human or a search engine does. Its task is to predict the most likely continuation of a text, based on a huge body of data and statistical links between words. If the query lacks context, the wording is ambiguous or the training data has few reliable examples, the model still tries to produce a coherent answer. This is what users perceive as lying: the text looks logical, the tone is confident, and the facts may be invented or blended together. The problem gets worse in scenarios where the model is expected to supply exact re
Why fine-tuning is not enough?
The intuitive idea of "let's just fine-tune the model and remove hallucinations" works only partly. Fine-tuning does help a model behave better in a specific domain, follow the answer format and drift less often into obvious fantasy. But it does not turn the model into a system that knows only verified facts and is guaranteed to stop when data runs out. The model is still optimized for plausible text, not for the truth of each statement. Even large, well-tuned models keep making mistakes on rare cases, recent events, narrow specialist topics and long chains of reasoning. Th
How to reduce the risk?
In practice, the working approach is not to wait for perfect behavior from the LLM but to build protective layers around it. The more an error costs the business, the more checks, restrictions and explicit rules for declining to answer the pipeline should have. This changes how deployment is approached: instead of asking how to make the model never err, a different question appears: how to make sure an error does not become an incident. That is a matter of system design, not model magic. Connect retrieval and let the model answer only from the documents it finds Require ref
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.