MIT teaches generative AI to fill in hidden objects from wireless signals
MIT has sharpened wireless "vision" for robots: a generative model fills in the hidden parts of objects from reflections of mmWave signals, which are close to Wi-Fi. The Wave-Former system is almost 20% more accurate than earlier approaches, while RISE can reconstruct an entire room from a single stationary radar and the movement of a person. The technology could be useful in warehouses, smart homes and settings where cameras are undesirable for privacy reasons.
AI-processed from MIT News; edited by Hamidun News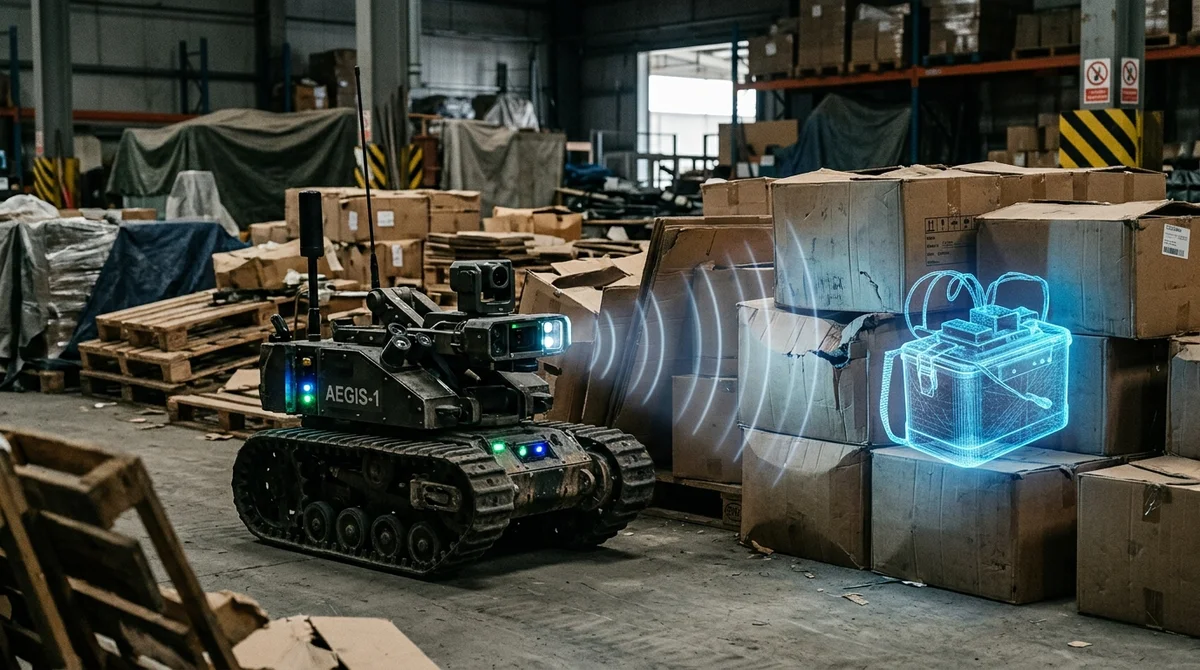
MIT researchers have improved a wireless "vision" system that recognizes objects hidden behind obstacles using reflections of millimeter-wave signals. A generative model now fills in the missing parts of an object's shape and helps robots better understand what sits behind cardboard, plastic, drywall or fabric.
How it works
Earlier versions of such systems could already use mmWave signals to build a rough 3D model of an object hidden behind a barrier. The problem was the physics of reflection: waves often bounce off in one direction instead of returning to the sensor. As a result, the system usually "saw" only the top of an item, while the side and bottom surfaces remained blank zones.
For a robot this is critical: if the shape is reconstructed inaccurately, the manipulator is worse at working out how to grasp the item safely and how it sits in space.
To get around this limitation, the MIT team added a generative model that takes an incomplete reconstruction and fills in a plausible full shape. But there were not enough real mmWave datasets for training, so the researchers took a workaround: they took large computer-generated image datasets and adapted them to the properties of wireless reflections, including specularity and noise. They trained the Wave-Former system on this synthetic base. It first proposes possible object surfaces from the reflections, then the model fills in the gaps, and after that it refines the geometry into a complete 3D reconstruction.
Accuracy and scenes
In tests, Wave-Former reconstructed the shapes of about 70 everyday objects, from cans and boxes to fruit and kitchen utensils. The objects were hidden behind, or placed under, cardboard, wood, drywall, plastic and fabric. According to MIT, the new scheme produced a reconstruction almost 20 percent more accurate than the best previous approaches. In practical terms this is an important step: the system does not merely detect that an item is present, but comes closer to understanding its real shape, volume and boundaries.
"We are using AI to finally unlock the potential of wireless vision," says
Fadel Adib, who leads the work.
The team did not stop there and built a second system, RISE, which reconstructs not a single object but an entire room. It needs only one stationary radar and a person moving inside the space. When a person walks, part of the signal reflects off them, then off walls and furniture, and then returns to the sensor. Such secondary reflections are usually treated as noise and discarded, but MIT taught the model to extract the layout of the scene from them. In experiments on more than 100 human movement trajectories, RISE was on average about twice as accurate as existing methods.
Where it could be useful
The practical value lies not only in accuracy but also in how the method is used. Scene analysis does not need a mobile robot carrying a sensor that has to travel around the room and scan it from different points. A single motionless radar is enough. The method also does not rely on ordinary cameras, so it suits scenarios where the privacy of people in the frame matters.
- Checking the contents of boxes and packages before shipping
- Finding items covered by other things in a warehouse or at home
- Reconstructing a room layout with one stationary sensor
- Determining a person's position so a robot can move more safely
- Scenarios where cameras are undesirable for privacy reasons
If the technology becomes more detailed and robust, it could have a chance to leave the lab. The MIT team says directly that the next step is larger foundation models for wireless signals, by analogy with how GPT, Claude and Gemini work with text and images. Such an approach could turn wireless sensing from a narrow research tool into a universal perception layer for robots and smart spaces.
What this means
MIT shows an interesting shift: instead of manually squeezing the maximum out of every reflection, researchers hand a generative model the task of guessing the missing geometry from partial data. If this approach scales, robots will be able to "see" behind obstacles with more confidence where an ordinary camera is useless or undesirable.
- Nov 1, 2026Local models lose to Opus and Codex: 0.21 on a MacBook versus 1.00 for Codex
- Nov 1, 2026Kimi scores 96.2% on a 1C database analytics test and emerges as a fallback if Claude access is blocked
- Nov 1, 2026OpenAI Rewrites GPT Behavior Rules: Five Values and a Chain of Command
- Nov 1, 2026Google admits AI Mode cuts search revenue, shares fall 15%
Key Questions Answered
How it works?
Earlier versions of such systems could already use mmWave signals to build a rough 3D model of an object hidden behind a barrier. The problem was the physics of reflection: waves often bounce off in one direction instead of returning to the sensor. As a result, the system usually "saw" only the top of an item, while the side and bottom surfaces remained blank zones. For a robot this is critical: if the shape is reconstructed inaccurately, the manipulator is worse at working out how to grasp the item safely and how it sits in space. To get around this limitation, the MIT tea
What are the key details on Accuracy and scenes?
In tests, Wave-Former reconstructed the shapes of about 70 everyday objects, from cans and boxes to fruit and kitchen utensils. The objects were hidden behind, or placed under, cardboard, wood, drywall, plastic and fabric. According to MIT, the new scheme produced a reconstruction almost 20 percent more accurate than the best previous approaches. In practical terms this is an important step: the system does not merely detect that an item is present, but comes closer to understanding its real shape, volume and boundaries. "We are using AI to finally unlock the potential of w
Where it could be useful?
The practical value lies not only in accuracy but also in how the method is used. Scene analysis does not need a mobile robot carrying a sensor that has to travel around the room and scan it from different points. A single motionless radar is enough. The method also does not rely on ordinary cameras, so it suits scenarios where the privacy of people in the frame matters. Checking the contents of boxes and packages before shipping Finding items covered by other things in a warehouse or at home Reconstructing a room layout with one stationary sensor Determining a person's pos
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.