Sber shows how RAG and an in-IDE LLM turn manual test scripts into automated tests
Sber has shown a prototype for JetBrains IDEs that generates automated tests from manual scenarios by combining an LLM with RAG. The system searches the project itself for relevant steps and tests, preserves code style, and checks the result through PSI. Inside the company, 68% of generated tests needed only minimal edits, and user satisfaction came in at around 80%.
AI-processed from Habr AI; edited by Hamidun News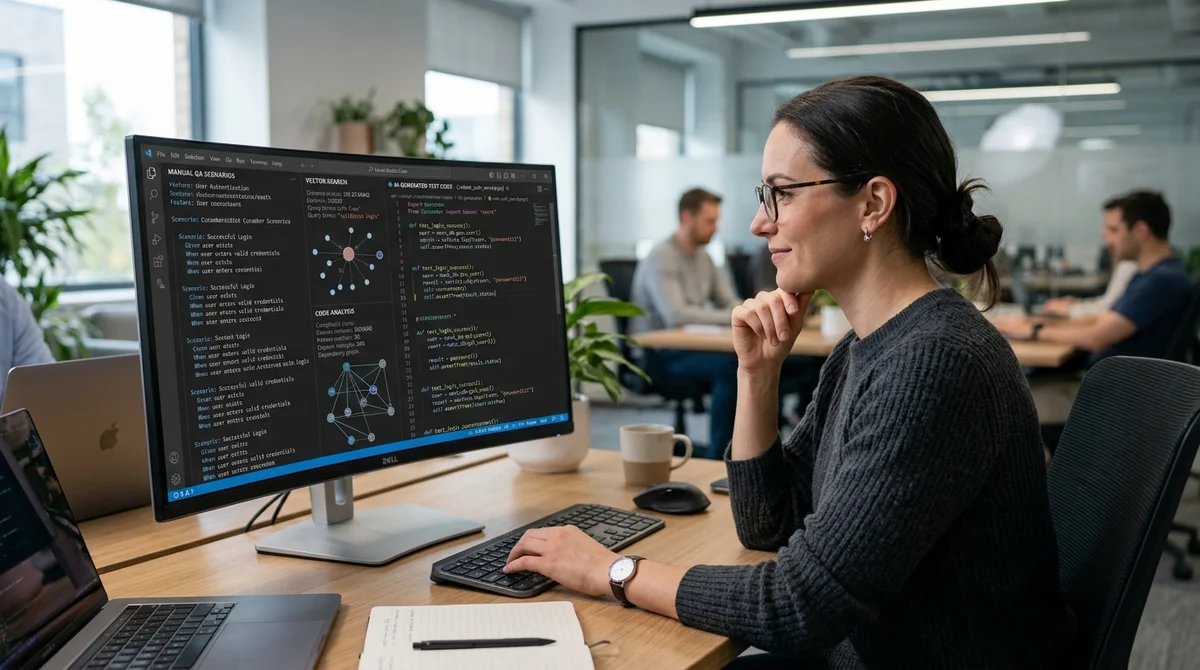
Sber has shown how to cut down one of the most routine tasks in QA: turning manual scenarios into automated tests directly in the IDE. The approach pairs an LLM with RAG. Rather than simply writing code, it first searches the project for relevant examples so that the output keeps the project's style, conventions and architecture.
Why a direct prompt doesn't work
The idea of "just send a manual test to the model and get finished code back" breaks down on details. An LLM can indeed assemble a working Java test, but it will almost certainly not do it the way a particular team does: it will forget Allure, break the naming scheme, put the URL and request body in the wrong place, add unnecessary assertions, or skip internal utilities such as a shared status-check method. In test automation this is not cosmetic; it means a real loss of compatibility with the project.
The problem runs deeper than prompt quality. Automated tests live in their own framework and are tied to the architecture, CI, Page Object, TMS keys and annotation conventions. Trying to hand the model the entire project quickly runs into context-window limits, growing latency and request costs. Even then, hallucinations, skipped steps and unstable output remain, and someone has to bring the result up to standard by hand.
How RAG works
Instead of static few-shot prompting with hand-picked examples, the Sber team built a plugin for JetBrains IDEs. It scans the project through the PSI structure rather than as raw text, so it sees classes, methods, annotations and calls. From this, the system collects Allure steps, existing automated tests, their TMS keys, code and short text descriptions. These descriptions are then turned into embeddings and stored with metadata in a local knowledge base or vector store.
When a new manual scenario arrives, the system goes through several stages:
- extracts the action and expected result for each step;
- builds several semantic variants of the query to search for similar steps;
- asks the LLM to briefly describe the whole test, so it can find a semantically close automated test;
- automatically inserts the examples it finds into the prompt in place of manual few-shot;
- verifies the result with a repeat request to the model and through PSI inside the IDE.
This approach yields code that looks as if someone from that team wrote it, rather than an external model with no context. The article stresses that semantic search is there not for the sake of fashionable RAG but for a practical goal: pulling into generation the steps, utilities and patterns that have already proven themselves inside the project.
RAG is few-shot that finds the right examples on its own.
Prototype results
According to the team, the internal prototype has already produced a measurable effect. About 68% of generated tests were at an acceptable level and needed only minimal edits, and overall user satisfaction was around 80%. The tool performed best on simple, similar API scenarios, where it matters most to quickly reproduce an established code template without manually copying from neighboring tests. Automation engineers also noted lower cognitive load: less time goes to routine work, more to complex scenarios and architectural decisions.
But there is no universal "autopilot" here. The model still tends to oversimplify complex tests with many steps, and for UI scenarios it needs more context, such as information about page objects. Hallucinations have not gone away either, so a final review remains mandatory. The authors add that they saw no serious language limitations: similar results came not only with Java but also with Python and Gherkin. By their estimate, such a tool can save an automation engineer more than half the time spent writing new routine tests.
What this means
AI development tools are entering a more interesting phase: the value is shifting from "generate any code" to "generate code that fits straight into a living project." The Sber case suggests that in QA the winners will not be the teams that simply plug an LLM into the IDE, but those that wrap the model in their own knowledge base, checks and engineering rules.
Key Questions Answered
Why a direct prompt doesn't work?
The idea of "just send a manual test to the model and get finished code back" breaks down on details. An LLM can indeed assemble a working Java test, but it will almost certainly not do it the way a particular team does: it will forget Allure, break the naming scheme, put the URL and request body in the wrong place, add unnecessary assertions, or skip internal utilities such as a shared status-check method. In test automation this is not cosmetic; it means a real loss of compatibility with the project. The problem runs deeper than prompt quality. Automated tests live in the
How RAG works?
Instead of static few-shot prompting with hand-picked examples, the Sber team built a plugin for JetBrains IDEs. It scans the project through the PSI structure rather than as raw text, so it sees classes, methods, annotations and calls. From this, the system collects Allure steps, existing automated tests, their TMS keys, code and short text descriptions. These descriptions are then turned into embeddings and stored with metadata in a local knowledge base or vector store. When a new manual scenario arrives, the system goes through several stages: extracts the action and exp
What are the key details on Prototype results?
According to the team, the internal prototype has already produced a measurable effect. About 68% of generated tests were at an acceptable level and needed only minimal edits, and overall user satisfaction was around 80%. The tool performed best on simple, similar API scenarios, where it matters most to quickly reproduce an established code template without manually copying from neighboring tests. Automation engineers also noted lower cognitive load: less time goes to routine work, more to complex scenarios and architectural decisions. But there is no universal "autopilot"
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.