How to Build the Netflix Void Pipeline for Removing Objects from Video with CogVideoX
A new walkthrough shows how to build a Void pipeline for removing objects from video on top of CogVideoX. It covers environment setup, downloading the base model and checkpoint, preparing sample inputs and running the full inference chain with custom prompts. For video post-production teams, the value is that this is not a demo but a workflow that can be reproduced locally.
AI-processed from MarkTechPost; edited by Hamidun News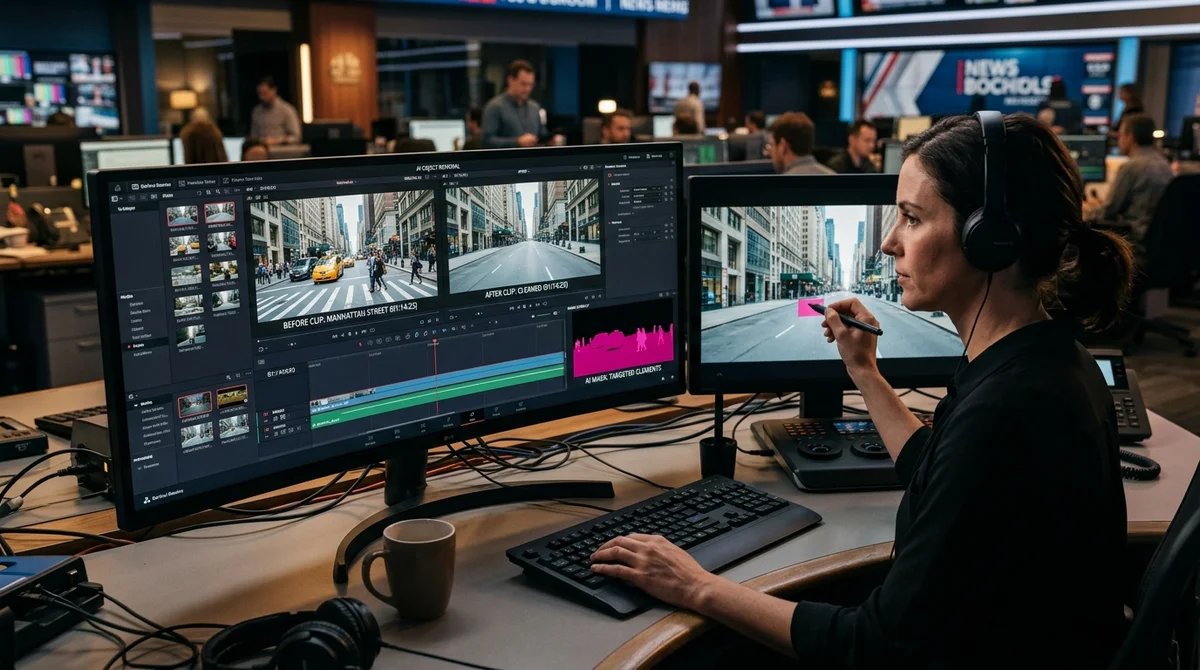
A new walkthrough shows in detail how to build a working pipeline for removing objects from video using Netflix's Void model: from installing dependencies and downloading weights to running the full inference chain with custom prompts and ready-made examples. For teams working in post-production, generative editing and video editing, the point is not the quality demo itself but a reproducible process that can be set up locally, tested on sample data and adapted to their own production.
The focus is the Void model, designed for video object removal and inpainting: removing unwanted objects from a frame, then filling in the background and motion so the result looks natural from frame to frame. In such scenarios, restoring a single frame is not enough: if the background jitters, textures drift and lighting changes in jumps, viewers notice the intervention immediately. That is why the walkthrough pairs CogVideoX with a separate checkpoint. The base video model handles the overall dynamics of the scene, while the specialized tuning helps solve the local-edit task more precisely without breaking the rest of the video.
In practical terms, this is a full engineering guide. First, you prepare the environment, install all required dependencies and clone the repository. Then you download the official base model and the Void checkpoint, and prepare sample inputs for a test run: the source clip, a mask or other input artifacts that show which object should be removed.
The order matters in substance, not just in form. In video inference, most failures occur not in the model architecture itself but at the junction of library versions, directory structures, file formats, VRAM limits and incorrectly specified weight paths.
The walkthrough puts particular emphasis on custom prompts and a full end-to-end sample inference. This is critical because the quality of the final clip depends not only on the mask but also on how the model interprets the scene after editing: what background should appear where the object was removed, how the camera motion continues, which elements must stay unchanged and how carefully small details are restored.
The material also highlights a more practical way to interact with the pipeline, through safe terminal-style entry of parameters. For an engineering team, this means more predictable runs, less manual routine and easier automation of repetitive video editing tasks.
Interest in such systems is no accident. Video has become a key format for marketing, education, media and product demonstrations, and demand has grown for tools that quickly remove extra objects, reflections, logos, random passersby or technical artifacts from a frame without frame-by-frame manual retouching. More importantly, generative models are gradually moving from impressive demos to production tools. In that context, output quality is not the only thing that matters: so do repeatability, clear installation, transparent configuration and the ability to embed the solution in an existing content-processing pipeline. Guides like this speed up adoption more than loud announcements do.
The main takeaway is that this walkthrough shows not an abstract research idea but a nearly production-ready scheme for AI video editing. When installation steps, dependencies, weights, launch logic and test examples are described together, the technology moves noticeably closer to real use. If the ecosystem around Void and CogVideoX keeps developing, the barrier to high-quality object removal from video will drop for studios, product teams and automated editing services. For the market, it is a clear signal: video inpainting is rapidly turning from an experimental feature into a working tool.
- Nov 2, 2026Cosmos generated training video for drones: detector mAP@50–95 up 10.3%
- Nov 2, 2026Karpathy builds a YouTube clone with 6454 videos from Hacker News recommendations in two hours
- Nov 2, 2026Karpathy used Claude to build HackerTube from 6,454 videos recommended on Hacker News
- Nov 2, 2026The Verge reviewer builds a $50 Meta Muse Charm alternative with Claude Code
Delegate Deep Research, Coding & Multi-Step Workflows to Nomad Agent
Deploy autonomous task execution with Nomad Agent (agent.nomadnet.ai) — automated web research, data synthesis, code generation, and MCP tool orchestration.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.