Google and OpenAI Are Hitting a Ceiling: What Happens When the Web Runs Out of Human Text
Generative AI has fallen into an odd dependency: models need human-written text, yet they shrink the incentive to create it. AI summaries in search cut clickthroughs to websites, while the internet fills up faster with machine-generated content. If this loop takes hold, developers will end up with less high-quality training data, and the answers of new models may start to degrade noticeably.
AI-processed from Habr AI; edited by Hamidun News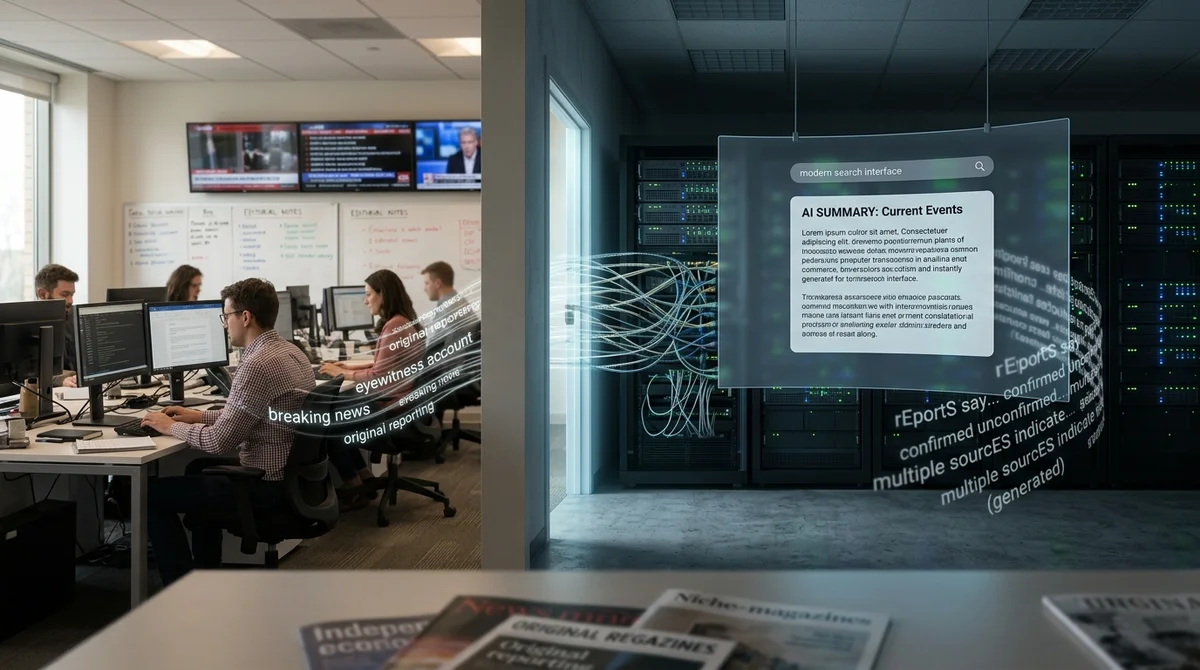
The main weakness of generative AI is that it lives off human-written text while destroying the conditions in which that text gets produced. Search engines, chatbots and AI summaries promise users a quick answer without a click through to a website, and in doing so they cut the revenue of the people who produce the original material. In the short term, models win on convenience. In the long term, they risk losing a quality training base and starting to learn from their own reflections.
The first problem is the economics of publishing. Since Google launched AI Overviews in May 2024, search has increasingly answered directly in the results page without sending readers to the original source. According to Chartbeat data published by Axios on March 17, 2026, small sites with 1 to 10 thousand page views a day lost about 60% of their search referrals over two years.
Mid-sized sites dropped 47%, and large ones 22%. A Pew Research Center study from July 22, 2025 showed a similar effect at the level of user behavior: when search results include an AI summary, people click regular links noticeably less often. For media outlets, forums, niche blogs and independent authors, this is not an abstract metric.
It is a direct hit to advertising, subscriptions and the motivation to keep writing.
The second problem is the data itself. Large language models originally grew on huge troves of internet text. For early systems such as GPT-3, most of the training corpus came from the web and related sources. But the supply of high-quality human content is finite. In June 2024, Epoch AI researchers estimated that, at the previous pace of scaling, the industry could hit the limit of publicly available text suitable for training somewhere between 2026 and 2032. That is why the biggest players began signing deals with Reddit, publishers and other owners of large archives: access to data has gone from a technical detail to a strategic asset.
Against this backdrop, the temptation to switch to synthetic data looks almost unavoidable. If there isn't enough real text, it seems logical to ask one model to generate material for the next. The catch is that this approach gradually degrades quality.
A paper published in Nature on July 25, 2024 describes the model collapse effect: when models are trained recursively on machine-generated data, they begin to lose rare facts, flatten complex patterns and amplify existing errors and biases. It is like photocopying the same page over and over: the general meaning is still visible, but the details fade with each iteration. Even OpenAI has publicly acknowledged that synthetic data can help in targeted cases but does not look like a full replacement for a diverse human corpus.
There is another trap: separating human text from machine text is much harder in practice than it seems. AI-content detectors still make mistakes, especially on short, edited or stylistically neutral texts. Some studies have shown a high rate of false positives on texts by people for whom English is not a native language.
This means it will be hard for the industry to simply "clean up the internet" and select only reliable human data. Moreover, recent academic assessments already find that the share of AI assistance in new publications is growing fast, and online content itself is becoming more uniform in meaning and more sterile in tone. In other words, the problem is not only the quantity of text but also its diversity.
If this cycle isn't broken, the internet will start working worse for everyone involved. Authors will publish in-depth pieces less often because they are harder to monetize. Platforms will keep filling results with short AI summaries, saving the user a click but impoverishing the ecosystem of sources. And model developers will get more and more secondary content that sounds confident but carries less new knowledge.
The way out seems to lie not in even more generation but in preserving incentives for human writing: paying for licenses, transparent attribution, more careful use of AI summaries, and putting data quality ahead of sheer scale. Otherwise, AI really will end up in a trap of its own making.
- Nov 2, 2026TJ Digital: 23% of AI-cited pages open with a direct answer, versus 14% of uncited ones
- Nov 2, 2026Arca gives AI agents finance tasks lasting up to 10 days, but leaves the trades to humans
- Nov 2, 2026Meta's Muse assistant keeps dossiers on loved ones and gets root on Ubuntu by default
- Nov 1, 2026Local models lose to Opus and Codex: 0.21 on a MacBook versus 1.00 for Codex
Ship AI Faster with Founders, Engineers & Weekly Architecture Reviews
Inside Vibe Club (hamidun.com/club) — weekly live masterminds with Zhemal Khamidun, Tech Radar, full LMS access, and 370+ production Claude Code skills.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.