Eltex engineer explains how to run federated learning on edge devices with 256 MB of memory
Eltex engineer Alexander Loshkarev has published a write-up on federated learning on edge devices with less than 256 MB of RAM. It is not about FL theory but about the practical side: how to fit the model, local training and update exchange into a tightly limited resource profile. The first part sets out a clear frame for the problem, aimed at embedded and ML teams.
AI-processed from Habr AI; edited by Hamidun News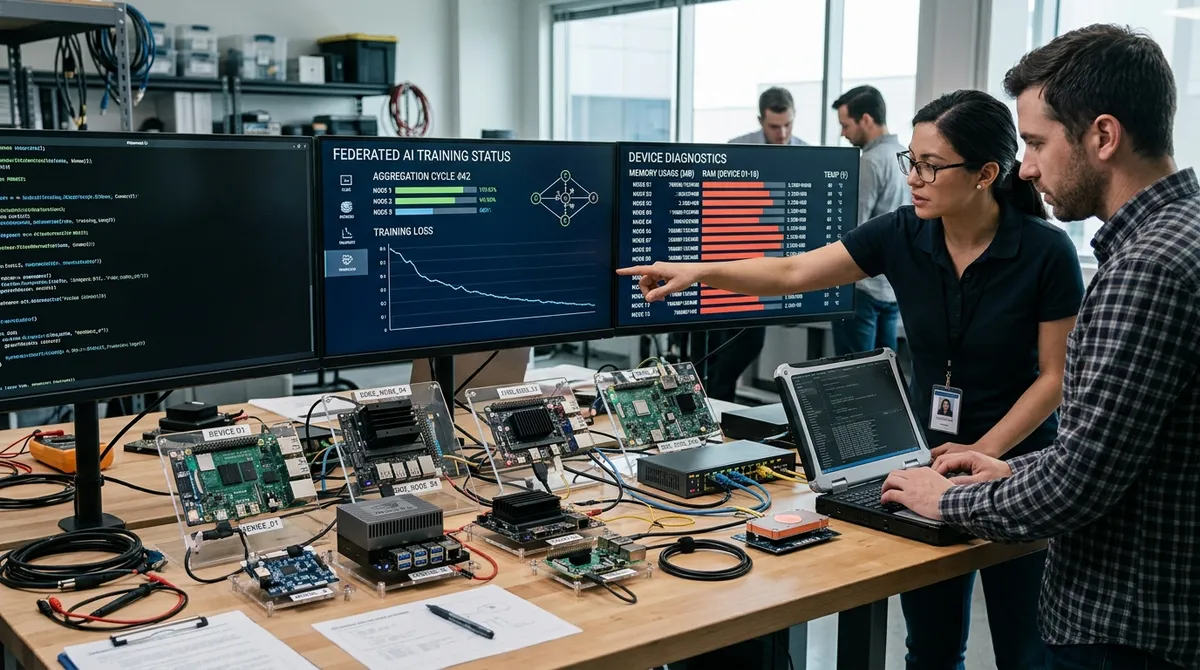
Federated learning is usually discussed in the context of smartphones, cars and large IoT networks, but in practice the main barrier is often far more mundane: the device simply does not have enough memory. That is the focus of a piece by Eltex engineer Alexander Loshkarev, based on his talk for AiConf.
The topic sounds narrow, but it touches almost any project that needs to move ML from the cloud to the network edge and make it run on hardware with very modest resources. The scenarios in question involve edge devices with less than 256 MB of RAM. For server teams this looks like an almost extreme limit, but for industrial electronics, gateways, telecom equipment, embedded systems and specialized controllers, such a configuration is entirely realistic.
Under these conditions the task is no longer just a matter of taking a ready-made model and loading it into memory. You have to fit the model itself, the data, buffers, system processes and the update-exchange logic at the same time, without compromising the device's stability.
What makes federated learning interesting here is that it allows models to be trained or fine-tuned without centrally transferring raw data. Computation happens locally, and only parameters or their changes are sent out. This approach gives better control over privacy, reduces dependence on a constant network link and makes edge scenarios more viable. But it has a downside: the local FL client itself needs memory, compute and a carefully organized pipeline. The weaker the device, the harder you have to economize on every megabyte.
judging by the description of the first part, the material deals with the engineering side of this problem rather than abstract theory. For teams deploying ML at the edge, this is the most painful area: a model can be accurate in the lab yet useless in production if it does not fit in memory or degrades the device's other services. On such devices, what matters is not only the size of the weights but also temporary memory peaks during inference, batch preparation, update serialization and network exchange. Even if a model looks compact in static terms, its runtime behavior can make deployment impossible.
In this sense, the framing around a device for which 1 GB sounds like a luxury describes the gap between the typical ML stack and the real embedded world quite accurately. Many tools and practices familiar from server development stop working here without adaptation. You cannot keep increasing batch size, hold redundant copies of tensors or rely on a generous system memory reserve. Any error in estimating the resource profile quickly turns into restarts, freezes or the loss of the very feature the model was deployed for.
It is also important that this is not just about running inference on a small device, but specifically about federated learning. That is a more complex mode: the system must periodically receive the global model, run training steps locally, store intermediate states and send the result back. When memory is scarce, literally everything has to be reconsidered: model size, data representation format, synchronization frequency, the length of local sessions and sometimes the client architecture itself.
The announcement shows the author is asking the right question: before discussing model quality, you need to determine whether the model can be served on real edge hardware without crashes and constant compromises on reliability.
This is an important signal for the market. Interest in AI at the network edge is growing, but real deployment runs into limits on memory, power and resilience, not into polished demos. That is why such materials are useful not only to ML engineers but also to backend, embedded and product teams: they bring the conversation back from promises to systems engineering.
If the first part sets the frame for the problem, the main conclusion is already clear: in edge ML, the winner is not the trendiest model but the one the device can actually survive.
Ship AI Faster with Founders, Engineers & Weekly Architecture Reviews
Inside Vibe Club (hamidun.com/club) — weekly live masterminds with Zhemal Khamidun, Tech Radar, full LMS access, and 370+ production Claude Code skills.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.