OpenAI Embeddings and RL: How to Build an Agent With Long-Term Memory for Accurate Answers
A new tutorial walks through building an RL agent with long-term memory that learns to pull exactly the entries from a knowledge bank that help an LLM answer more accurately. The pipeline starts with a synthetic dataset and fact-recall queries. It then uses OpenAI embeddings to turn memories and questions into vectors and trains a policy specifically to select relevant memories.
AI-processed from MarkTechPost; edited by Hamidun News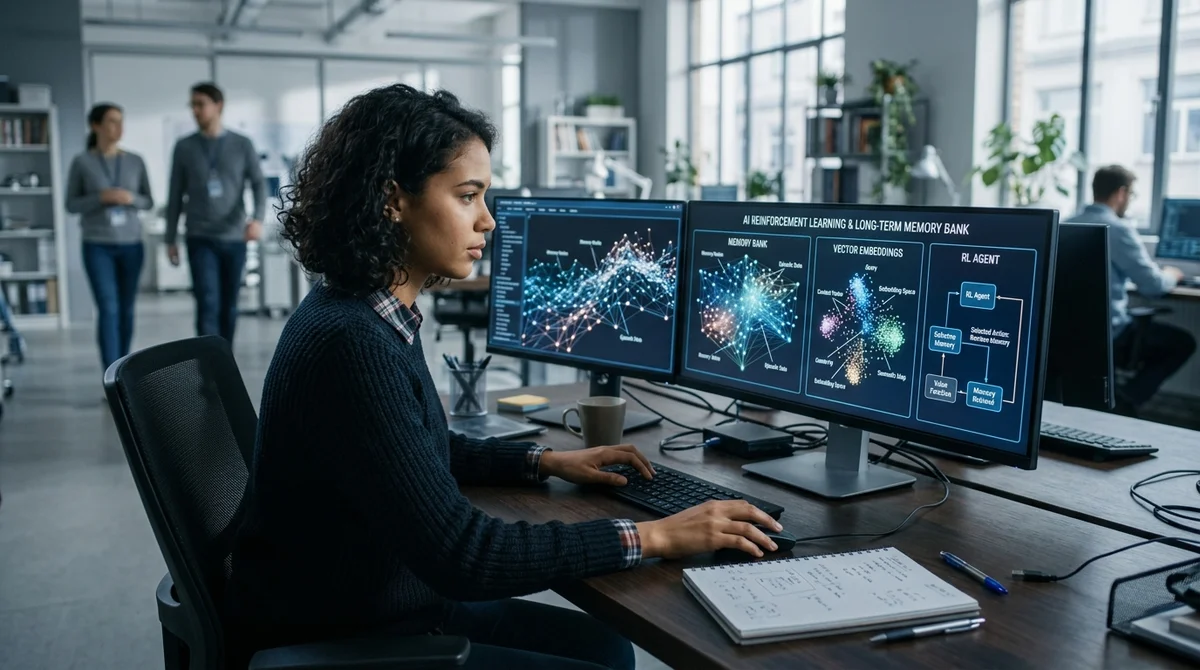
Long-term memory for AI is turning into a practical engineering problem. A new tutorial shows how to build a reinforcement learning agent that doesn't just search for similar entries but learns to retrieve exactly the facts an LLM needs to answer accurately. The approach matters for systems that hold too much knowledge for a single context window, where picking the wrong memory immediately hurts answer quality.
The authors start with a synthetic memory set: they create a collection of entries and then generate queries that require recalling specific details. This setup is convenient because it lets them control which entry is actually relevant and evaluate not only the model's final answer but the memory retrieval step itself. Instead of hand-crafted rules, a trainable agent gradually receives a signal about which actions lead it to the right fact.
This also reduces the risk of overfitting to one particular search scenario and makes it easier to check experiments automatically. Next, OpenAI embeddings map memories and queries into a vector space. That gives the system a baseline similarity signal: which entries look semantically close to the question.
But systems that rely on vector proximity alone often stumble. A similar entry may be too general, overlap with the topic only partially, or contain a neighboring fact rather than the right one. This is where RL becomes a layer on top of ordinary search: the agent has to learn to pick not simply the most similar entry, but the most useful one for the answer.
In practice, memory retrieval shifts from a static nearest-neighbor lookup to a sequence of decisions. The agent can rank candidates, refine its choice, combine signals, and earn rewards for retrieving snippets that make the LLM answer more accurately. For developers, this is an important shift: memory stops being passive storage and becomes part of an optimizable loop.
The design is especially useful for personal assistants, enterprise knowledge bases, agent systems with conversation history, and any product where the model must remember old facts without constantly loading the entire archive into the prompt. This kind of architecture helps separate the short-term context of the current request from accumulated memory that grows along with the product. The synthetic nature of the dataset and the way results are evaluated deserve separate attention.
Early on, such a set helps run training quickly and see whether the reward signal mechanics work at all, but eventually the scheme will have to move to messier real-world data: user notes, CRM events, document fragments, correspondence, and meeting minutes. In real environments, relevance is almost never binary, and important facts may be scattered across several entries. So for these systems it isn't enough to check whether the model found something similar: you need to measure whether retrieval helped produce the right answer, whether hallucinations went down, and how consistently the agent behaves across different query types.
In that sense, RL is valuable because it optimizes the usefulness of retrieved memory for the end task rather than an abstract similarity metric. The main takeaway is that the next wave of improvements in LLM agents will come not only from model size but also from the quality of memory management. If an agent can learn from a usefulness signal and pick the right memory at the right moment, then even without expanding the context window it can noticeably improve answer accuracy, reduce noise, and make the system behave more reliably over the long run.
For teams building AI products on top of RAG and agentic workflows, this is a useful guideline: optimize not only generation but also the knowledge retrieval policy.
- Nov 2, 2026NC State's AICG Framework Cuts MAE by 50.3% on Math Answer Grading
- Nov 2, 2026We Audited 929 Automations at Alpina: What Corporate AI Training Should Look Like in 2026
- Nov 2, 2026I Interrogated 6 AI Models About Myself Through a Procurement Manager's Eyes: Amazon, Esoterica, 'Telo Hudelo' and 5 Holes We Closed in a Day
- Nov 2, 2026TJ Digital: 23% of AI-cited pages open with a direct answer, versus 14% of uncited ones
Build & Ship Production AI Agents Without Boilerplate Code
Start your free 72-hour trial at Hamidun Academy (academy.hamidun.com) — interactive lessons on Claude Code & Cursor, live Tech Radar, and production agent templates.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.