AWS shows how to automatically sync Amazon Bedrock knowledge bases from S3
AWS has described a serverless solution that automatically syncs documents from S3 to Amazon Bedrock Knowledge Bases. The design catches storage events, queues tasks through SQS, and launches ingestion jobs only within service quotas. The result: the knowledge base stays updated in near real time, with no manual oversight and no unnecessary load on the API.
AI-processed from AWS Machine Learning Blog; edited by Hamidun News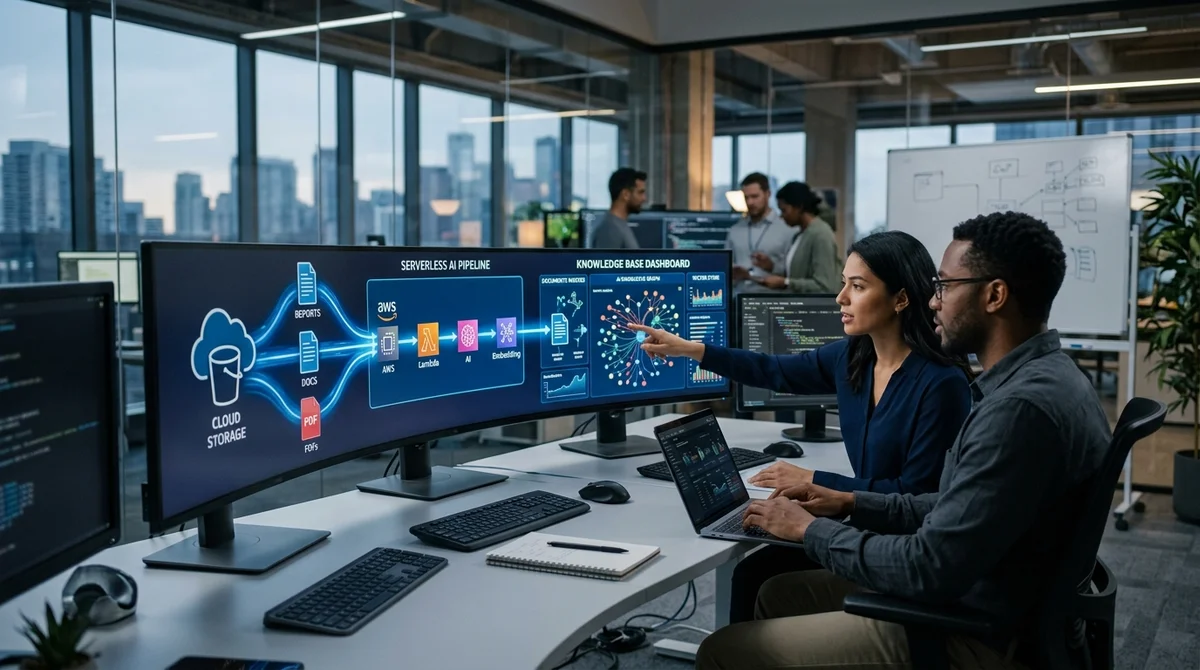
AWS has proposed a practical way to keep Amazon Bedrock knowledge bases up to date without manually kicking off an ingestion job after every change in storage. The idea is to wire Amazon S3 events into a serverless pipeline that detects new or modified files on its own, triggers synchronization, and stays within Bedrock's limits. For teams building RAG services on top of corporate documents, this removes one of the most common operational headaches: the knowledge base no longer lags behind the source data and updates predictably, rather than on a schedule or by manual command.
Knowledge Bases in Amazon Bedrock connect generative models to a company's internal data — manuals, articles, PDFs, spreadsheets, and other documentation. But the model doesn't learn about new files automatically: once data lands in S3, it still has to be reindexed through an ingestion job. Done by hand, this process quickly breaks down at scale. Documents arrive at different times, updates come in unevenly, and the team ends up juggling the AWS console, scripts, and sync queues.
The solution AWS describes is built on an event-driven architecture. When a new file appears in S3, an existing object changes, or another relevant event occurs, the system records it and starts an ingestion job for the corresponding knowledge base. The serverless approach matters here for two reasons. First, there's no need to run a dedicated always-on service just to check for changes. Second, the logic scales easily with an unpredictable stream of updates: when there are few events, the infrastructure consumes almost no resources, and when volume grows, the pipeline keeps running automatically.
The key emphasis isn't just on automatic triggering but on respecting Amazon Bedrock service quotas. That's an important detail, because a naive design in which every event immediately launches its own job can quickly run into API limits — especially if hundreds of files are uploaded to a bucket at once or an archive of documents is updated in bulk. Synchronization therefore has to throttle the load, avoid creating redundant ingestion jobs, and keep useful automation from turning into a source of errors and retries. Another advantage is full monitoring: the team can more easily see which jobs were launched, where delays occurred, and whether any data changes are being missed.
For product and engineering teams, this is not a minor infrastructure detail. In RAG-based systems, answer quality depends directly on how fresh the context fed to the model is. If the knowledge base updates late, users may see outdated prices, old policies, obsolete process descriptions, or missing documents. Automatic synchronization narrows this gap between the data source and the model's response. It also simplifies operations: instead of manually triggering updates after every data export, the team gets a reproducible process with clear logic, load control, and observability.
It's also telling that AWS is betting on a serverless, event-driven design rather than a heavyweight integration with constant background processing. For many companies, this is the most convenient way to roll out generative search on top of existing S3 storage: the data stays in a familiar environment, and index updates become a response to events. The approach is especially useful where documents change frequently — in support, internal knowledge bases, analytics, compliance, and product documentation.
The main takeaway is simple: as Bedrock increasingly serves as the foundation for corporate assistants and document search, manual data synchronization becomes the weak link. AWS is effectively offering a template for automating this process without losing control over quotas or pipeline state. For businesses, that means more current model answers, less manual busywork, and a more predictable knowledge base in production.
- Nov 2, 2026Steering vectors in LLM fine-tuning improved SFT and distillation across three seeds
- Nov 2, 2026Anthropic needs to grow revenue 32% a year to cover $850 billion in contracts
- Nov 2, 2026The Verge reviewer builds a $50 Meta Muse Charm alternative with Claude Code
- Oct 31, 2026Worldwide Express hands disputed invoices to AI agents and cuts unresolved disputes by 75%
Ship AI Faster with Founders, Engineers & Weekly Architecture Reviews
Inside Vibe Club (hamidun.com/club) — weekly live masterminds with Zhemal Khamidun, Tech Radar, full LMS access, and 370+ production Claude Code skills.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.