The End of Expensive AI: Google and NVIDIA Slash the Cost of Inference
The main obstacle for AI has never been just the cost of training models. It has been the cost of running them every day. At Google Cloud Next, Google and NVIDIA presented a joint platform that could radically change the economics of cloud computing. The new A5X instances, built on NVIDIA Vera Rubin NVL72 monolithic rack systems, promise to cut AI inference costs tenfold. The companies say the gain comes from unusually deep integration at the hardware and software levels. A drop in compute costs of this scale will inevitably put advanced multimodal AI within reach of mass-market consumer services.
AI-processed from AI News; edited by Hamidun News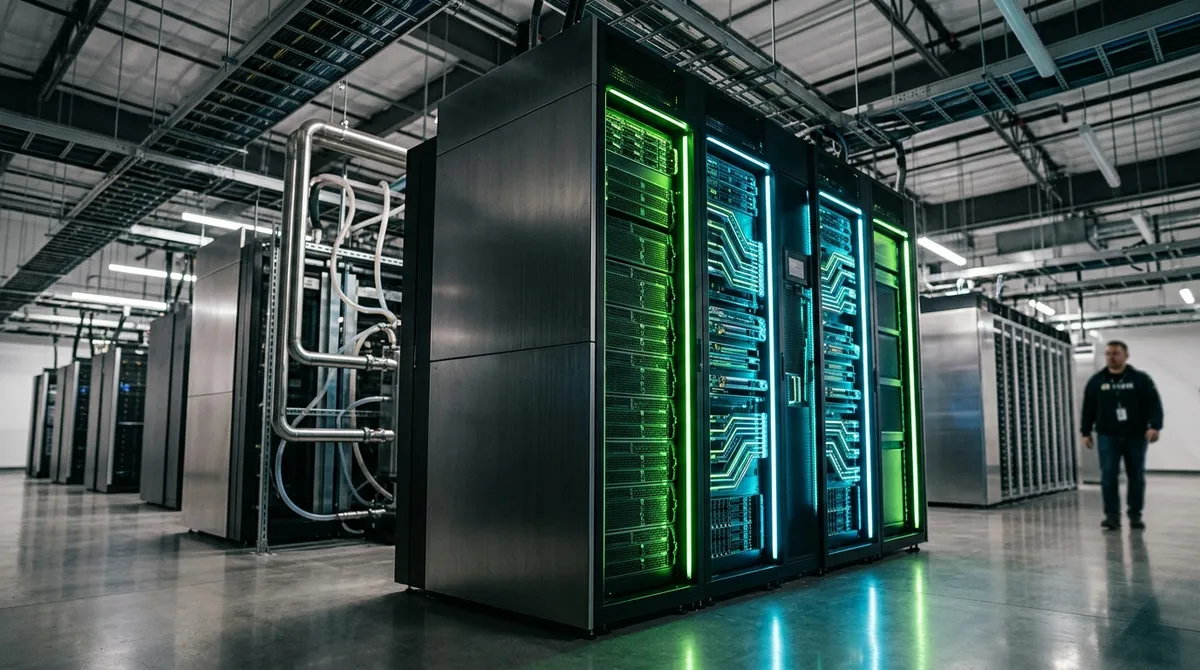
The AI industry has long been held hostage by its own ambition, masking fundamental economic problems behind loud product launches. Public attention traditionally fixes on the enormous cost of initially training new language models, but the real financial black hole lies in running them day to day. Generating answers to millions of user requests every day, known in the industry as inference, demands the continuous operation of huge, extremely power-hungry compute clusters.
That factor has so far made large-scale deployment of truly cutting-edge, multimodal AI economically impractical for the vast majority of companies. At the recent Google Cloud Next conference, tech giants Google and NVIDIA announced the end of this era of infrastructure scarcity, presenting a new joint architecture that promises to cut the cost of inference tenfold.
The foundation of this breakthrough is the new A5X compute instances, delivered on bare metal. Dropping classic virtualization eliminates the performance lost to intermediate software layers and hands the full compute power directly to the algorithms. The instances are built on the NVIDIA Vera Rubin architecture, the long-awaited generation change that succeeds Blackwell. The key element of the new infrastructure is the NVL72 rack system. In the traditional modular approach, individual GPUs are grouped into standard servers, with unavoidable bottlenecks in data transfer. NVL72, by contrast, is a monolithic compute system the size of an entire cabinet. Inside this rack, seventy-two next-generation GPUs operate as a single giant supercomputer, linked by ultra-fast optical interconnects.
This radical approach to server layout tackles the main problem of modern inference: memory bandwidth. Even the largest language models, with hundreds of billions of parameters, can now be loaded entirely into the system's shared memory. That spares the cluster the constant, slow and energy-hungry shuffling of data blocks between individual nodes. The claimed tenfold reduction in the cost of generating tokens comes not only from the raw silicon power of the Rubin chips, but also from an unprecedented level of hardware and software co-design. Notably, Google, which has its own powerful TPU tensor processors, went for such deep integration with NVIDIA, acknowledging that a hybrid approach is needed to meet developers' enormous demand.
Engineers at both companies effectively rewrote the base compute management stack, optimizing it for the specific needs of large-scale content generation. The new software-level load-distribution algorithms now account for the physical topology of the Vera Rubin rack, minimizing signal latency at the microsecond level. At the same time, advanced liquid cooling and new intelligent power controllers have sharply reduced electricity consumption per generated megabyte of data. For modern data centers, where the electricity bill often exceeds the cost of the servers themselves, this is a critical profitability factor.
The consequences of this infrastructure announcement for the tech market are hard to overstate, because it breaks a fundamental unit-economics barrier for AI-based services. Until now, independent developers and large corporations have had to make constant compromises. They had to artificially limit their products' functionality by using less capable but cheaper models, or impose strict request limits to avoid being ruined by cloud bills. A tenfold cut in costs means that business models that seemed like pure science fiction yesterday because of the staggering cost of compute are becoming fully profitable today.
In the near future, cheaper inference will bring a quiet but sweeping revolution in user experience. Complex real-time video analysis, personalized on-the-fly generation of 3D worlds in video games, and smart AI agents that work in the background around the clock, analyzing the entire stream of incoming information: all of this could become a mass-market standard rather than an expensive premium service. For cloud providers, the Google-NVIDIA alliance sets a daunting efficiency bar.
Traditional approaches to building data centers are rapidly becoming obsolete, giving way to hyper-optimized rack-level solutions. The partnership marks a major shift: the industry is finally moving from a race to build the smartest AI to a pragmatic race to deliver it to every user on the planet as cheaply, quickly and efficiently as possible.
- Nov 2, 2026Bun creator uses Claude Code to port 750K lines from Zig to Rust in 11 days
- Nov 2, 2026The Verge reviewer builds a $50 Meta Muse Charm alternative with Claude Code
- Nov 1, 202616 models tested on 7 search tools: Exa averaged 10.5 out of 14, SearXNG about 3
- Nov 1, 2026Google's StreamVibe video agent beats other models by 10.7% on response timing and quality
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.