Robots Trapped by Data: Why Backflip Videos Are Only the Beginning
Viral videos create an illusion of technological breakthrough, but real progress is held back by a "data crisis." Unlike text-based AI, robots need multidimensional data from the physical world: vision, touch and force. China is building data collection centers en masse, where operators train machines on basic tasks by hand. The main problems are the high cost of "live" data and the incompatibility of hardware from different manufacturers. Experts compare this stage to the early days of autopilot development, stressing that the road to general-purpose household robots will be far harder and more expensive than it first appeared.
AI-processed from 36Kr (36氪); edited by Hamidun News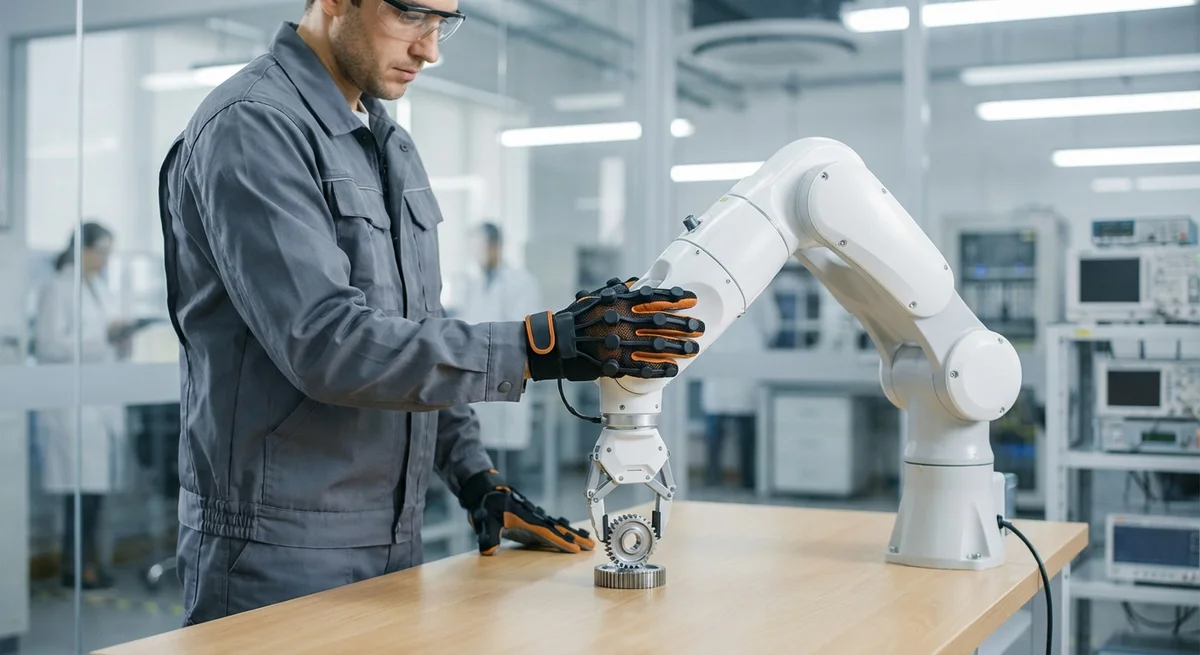
# Robots Trapped by Data: Why Backflip Videos Are Only the Beginning
Over the past year, the internet has been flooded with videos of impressive stunts: robots jump, dance, throw punches and smash watermelons with a kick. Investment is growing, the media are full of optimistic headlines, and the public is sure that the era of household robot helpers is about to begin. But look behind the curtain of this technological theater and the picture turns out to be far more complicated, and sadder.
Right now, in quiet data training centers across China, human operators in gloves are slowly, almost painfully, steering manipulators, teaching machines to pick up parts, put away tools and close box lids. It has none of the cinematic appeal of the viral videos, but it is what determines real progress in robotics. One fundamental problem stands between an impressive stunt and a useful household helper: a catastrophic shortage of quality data.
Language models such as ChatGPT and DeepSeek are built on the triumph of a simple idea: thousands of billions of text examples from the internet let AI grasp language and begin generating meaningful content. Robotics faces a very different reality. Text data lives in a two-dimensional digital space and is easy to copy and distribute, but the physical world is a multidimensional, continuous stream of information.
A robot has to perceive the world through many channels at once: video from several cameras, force sensors, touch sensors, joint position data. Every operation a manipulator performs generates structured data, with 57 dimensions in some systems. And all of these streams must be perfectly synchronized down to the millisecond, or the model will learn pure hallucination instead of cause and effect.
China already has more than fifty centers for collecting and processing robotics data. In Beijing alone, a single such center produces about six thousand training example records per day. A rough extrapolation suggests annual output could reach tens of billions of examples.
That sounds impressive, but it is a drop in the ocean of what is needed. Experts at PowerTech ran a conservative calculation: for a robot to learn one movement, it needs roughly one to five thousand examples. A simple task made up of several movements takes ten to twenty thousand.
But a universal robot able to handle eighty percent of human jobs in a single industry would require a dataset of one hundred million. And if the ambition extends to thousands of industries, we are talking about trillions of examples. The shortfall is four to five orders of magnitude.
But that is not even the most serious problem. Hardware incompatibility has proved far more insidious. Different manufacturers build robots with different sensor configurations, different control protocols and different physical parameters. Data collected on one manipulator model often simply does not work on another: the language of one machine remains completely foreign to the other. That means knowledge does not add up or accumulate into a single industry asset. Each manufacturer has to build its own dataset from scratch, repeating the same expensive work over and over.
Some centers cope with this dilemma by focusing on popular models, effectively ignoring diversity. Others take a more ambitious path: they collect data from robots by different manufacturers in a single space, trying to teach a model to generalize knowledge across heterogeneous hardware. Neither approach has yet proved universal.
All of this recalls the early days of autopilot, an era when the problem seemed to lie in the algorithms rather than the data. Almost twenty years and billions of dollars in investment later, the truth turned out to be somewhere close, but not quite where people were looking. Before robots truly enter our homes, a great deal of long, dull work remains in data centers, where people in gloves will patiently teach machines to understand the physical world. Viral videos are marketing. Real progress is a different story entirely.
- Nov 2, 2026NC State's AICG Framework Cuts MAE by 50.3% on Math Answer Grading
- Nov 2, 2026We Audited 929 Automations at Alpina: What Corporate AI Training Should Look Like in 2026
- Nov 2, 2026I Interrogated 6 AI Models About Myself Through a Procurement Manager's Eyes: Amazon, Esoterica, 'Telo Hudelo' and 5 Holes We Closed in a Day
- Nov 2, 2026TJ Digital: 23% of AI-cited pages open with a direct answer, versus 14% of uncited ones
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.