VL-LN Bench: Robots Learn to Ask for Directions and Might Finally Stop Getting Stuck
Researchers have introduced VL-LN Bench, a new standard for testing the navigation skills of AI. Older tests had a robot walk from point A to point B on a perfect map. Here, it must find specific objects using visual cues and dialogue. That brings us closer to a home assistant that can find your keys even if you dropped them in the most unexpected place. The system combines vision, language and spatial understanding, forcing algorithms to literally "think with their feet" and clarify their route on the go.
AI-processed from Jiqizhixin (机器之心); edited by Hamidun News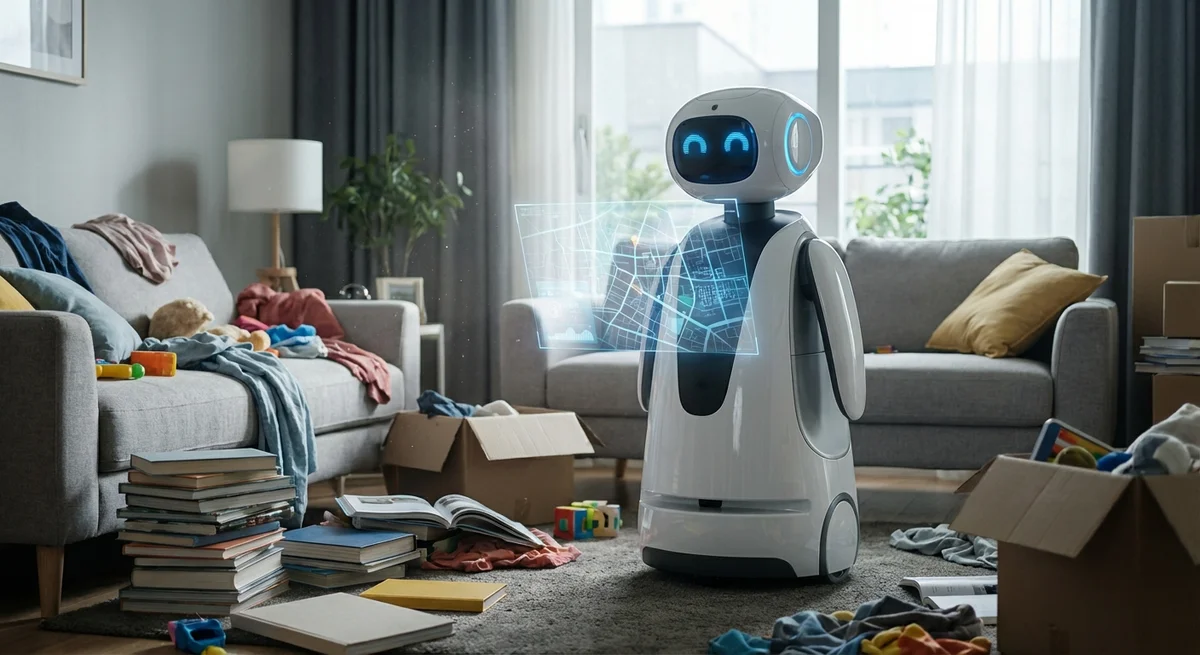
Imagine walking into a huge, unfamiliar shopping mall. You have no map, but you have a goal: to buy that exact blue vase from the ad. You don't just march ahead. You turn your head, read the signs and, most importantly, ask passersby: "Where's the decor department?" Researchers have packed exactly this natural process into a new benchmark called VL-LN Bench (Vision-Language-Location Navigation). It is not just another dataset but an attempt to teach machines to survive the chaos of the real world, where instructions are rarely complete and maps are rarely up to date.
For a long time, robot navigation resembled riding on rails. Developers fed algorithms perfect digital twins of buildings and clear commands. In classic Vision-Language Navigation (VLN) tests, a model typically received an instruction like "go straight five meters, turn left at the ficus." But life is dynamic. The ficus might be moved to another corner, and a door might be closed for repairs. Older methods folded in the face of reality because they could not actively explore or clarify context. They were too passive: the robot either carried out the command or broke down.
VL-LN Bench changes the rules. Now the AI agent has to imitate a "lost but determined" person. The point is that the robot must do more than move: it must constantly match what it sees (Vision) against language cues (Language) and its own position in space (Location). The researchers call this "active goal search through dialogue with the environment." The robot doesn't just walk; it keeps asking itself: "Is what I see now bringing me closer to the goal, or did I take a wrong turn?" If it is not confident, the system sends a clarification request.
What does this deliver in practice? First, robots become more autonomous in decision-making. They no longer need a detailed script for every step. Second, the benchmark pushes models to better understand spatial relationships and object semantics. If you say "find the mug, it's somewhere near the microwave," the robot first identifies the kitchen, then finds the microwave, and only then starts scanning the surfaces nearby. That seems simple to us, but for neural networks this kind of multi-level deduction long remained an unreachable peak.
The authors' approach to interaction is interesting. VL-LN Bench builds in the ability to clarify information. The robot can "ask" the system or analyze the text metadata of objects to narrow the search. This is effectively a transfer of large language model (LLM) mechanics into the physical world. Pure intelligence is finally getting a "body" that can navigate space as well as a human, and potentially better. The researchers stress that the key difficulty here is multimodality: the ability to process a video stream, text commands and coordinates at the same time.
Why do we need this right now? The home and warehouse robot industry has hit a ceiling. We have taught robots not to fall down stairs and to steer around cats, but not to understand that "bring me a beer from the fridge" is a very complex chain: finding the right room, identifying the appliance and manipulating objects under uncertainty. VL-LN Bench creates a sandbox where these skills can be honed to a shine. Without such tests, we would be stuck with vacuums that panic at black stripes on a carpet.
Of course, mass adoption is still far off. One of the main problems remains computing power. Processing a heavy video stream, matching it against a huge body of text data and planning an optimal route in real time requires serious resources. Still, the direction is right: from blindly following instructions to purposeful exploration. In the future, the phrase "I'm lost" should vanish from the machine vocabulary for good.
The bottom line: VL-LN Bench moves robot navigation from "following a GPS" to "purposeful search." Will your future robot butler be able to find your keys in a mountain of unironed laundry? Now, at least, we know how to test it.
- Nov 2, 2026DeepSeek Open-Sources Super-agent Prototype: p95 Task Time Drops from 29.5 to 15.7 Minutes
- Nov 2, 2026LLM Agent Built a Gearbox in KOMPAS-3D, but Scored Only 50 out of 100 on the Specification
- Nov 2, 2026Agents ignored the prompt to read memory in 7 of 7 sessions: an analysis of 13 thousand logs
- Nov 2, 2026Karpathy Built HackerTube, a Catalog of 6,454 Videos, in Two Hours with Claude Code
Build & Ship Production AI Agents Without Boilerplate Code
Start your free 72-hour trial at Hamidun Academy (academy.hamidun.com) — interactive lessons on Claude Code & Cursor, live Tech Radar, and production agent templates.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.