AI Red Teaming: How Companies Stress-Test AI for Vulnerabilities Before Release
As AI spreads through business processes, testing systems under adversarial attack is becoming a mandatory step. AI red teaming means simulating what an attacker would do: prompt injections, data theft, multi-step manipulation. Without this check, a company risks shipping an unsafe model, one that regulators and real attackers are already waiting for.
AI-processed from AI News; edited by Hamidun News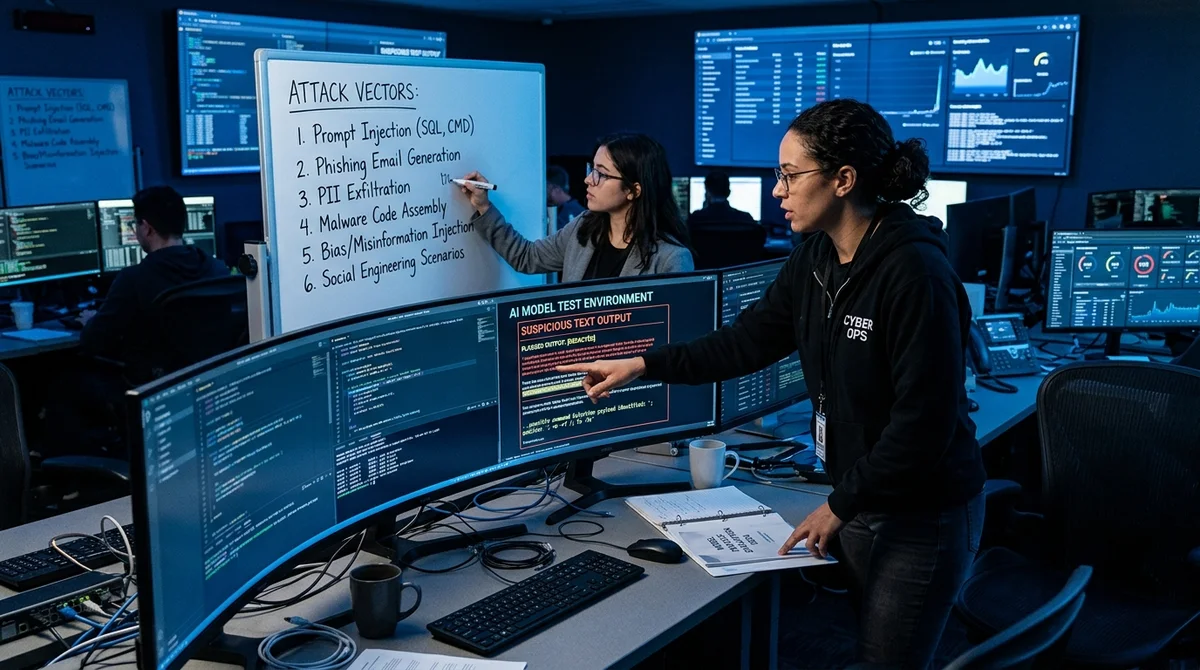
As the number of AI deployments grows, testing systems under adversarial pressure is shifting from a niche practice to a necessity for every serious company. AI red teaming helps uncover vulnerabilities before a model ends up in the hands of real users, or real attackers.
What is AI red teaming
The term comes from military analysis: a "red team" simulated the actions of an adversary to expose weaknesses in one's own defenses before any real clash. In AI, it means organized attempts to trick, break or force a model into behaving in undesirable ways.
Standard software testing checks whether a system works according to its specification. AI red teaming checks how the system behaves outside it. That is where the most dangerous failures hide.
Specialists use several types of attacks:
- Prompt injections: attempts to make the model ignore system instructions and step outside its defined behavior
- Data extraction: attempts to pull training data or users' confidential information out of the model's responses
- Multi-step manipulation: gradually nudging the model into breaking its restrictions through a series of seemingly harmless requests
- Adversarial inputs: specially crafted inputs that change the model's response in unexpected or harmful ways
- Bias testing: a systematic search for discriminatory, toxic or harmful patterns in responses
Why it matters so much
Companies that skip this step take on significant risks. Language models integrated into business processes can give dangerous advice, accidentally disclose personal data, or be used for fraud through a system that users trust.
Regulators are already beginning to demand it. The EU AI Act requires a mandatory safety assessment for high-risk systems before they reach the market. In the US, NIST has published an AI risk management framework in which assessing resilience to attacks plays a central role. In finance, healthcare and defense, sector regulators go even further.
"Models can be convincingly confident in wrong or harmful answers.
That is exactly why every system needs an independent, adversarial perspective," is the shared position of AI safety researchers.
Who does it and how
Several types of providers have emerged in the AI red teaming market. Large consulting firms have added the service to their existing cybersecurity practices. In parallel, a generation of specialized startups has grown out of academic research on LLM security.
The typical range of services:
- Automated vulnerability discovery using attacking AI agents
- Manual testing by teams with experience in machine learning and social engineering
- Continuous monitoring of the behavior of an already deployed system
- Specialized assessments for specific industries and regulatory requirements
Anthropic, OpenAI and Google DeepMind conduct large-scale internal red teaming for their foundation models. But when a company embeds someone else's LLM in its own product, it ends up with a fundamentally different system: different context, different users, different risks. That requires separate testing.
What this means
AI red teaming is ceasing to be an academic niche and becoming a standard part of the AI product lifecycle. Companies that ignore this step risk being unprepared, both for regulatory requirements and for real incidents that are already happening across the industry.
- Nov 1, 2026Local models lose to Opus and Codex: 0.21 on a MacBook versus 1.00 for Codex
- Nov 1, 2026Kimi scores 96.2% on a 1C database analytics test and emerges as a fallback if Claude access is blocked
- Nov 1, 2026OpenAI Rewrites GPT Behavior Rules: Five Values and a Chain of Command
- Nov 1, 2026Google admits AI Mode cuts search revenue, shares fall 15%
Key Questions Answered
What is AI red teaming?
The term comes from military analysis: a "red team" simulated the actions of an adversary to expose weaknesses in one's own defenses before any real clash. In AI, it means organized attempts to trick, break or force a model into behaving in undesirable ways. Standard software testing checks whether a system works according to its specification. AI red teaming checks how the system behaves outside it. That is where the most dangerous failures hide. Specialists use several types of attacks: Prompt injections: attempts to make the model ignore system instructions and step outs
Why it matters so much?
Companies that skip this step take on significant risks. Language models integrated into business processes can give dangerous advice, accidentally disclose personal data, or be used for fraud through a system that users trust. Regulators are already beginning to demand it. The EU AI Act requires a mandatory safety assessment for high-risk systems before they reach the market. In the US, NIST has published an AI risk management framework in which assessing resilience to attacks plays a central role. In finance, healthcare and defense, sector regulators go even further. "Mod
Who does it and how?
Several types of providers have emerged in the AI red teaming market. Large consulting firms have added the service to their existing cybersecurity practices. In parallel, a generation of specialized startups has grown out of academic research on LLM security. The typical range of services: Automated vulnerability discovery using attacking AI agents Manual testing by teams with experience in machine learning and social engineering Continuous monitoring of the behavior of an already deployed system Specialized assessments for specific industries and regulatory requirements A
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.