NVIDIA speeds up LLM pretraining with NVFP4 on Blackwell, JAX and MaxText
NVIDIA has published a technical guide to pretraining LLMs on Blackwell chips: the NVFP4 format, combined with JAX and MaxText, reduces training time and compute costs. Across thousands of accelerators, every percentage point of speedup saves days of wall-clock time. NVFP4 uses 4-bit weights instead of FP8 while keeping precision in critical operations, and it now works with the open-source MaxText without rewriting code.
AI-processed from NVIDIA Developer Blog; edited by Hamidun News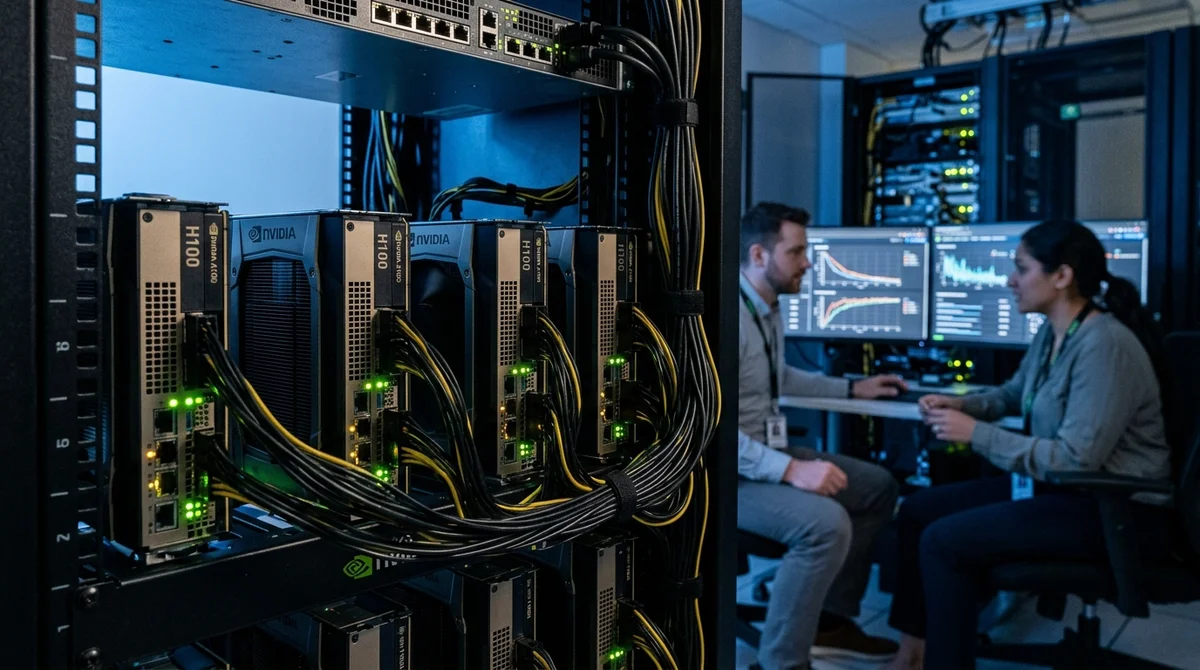
Pretraining frontier LLMs is bottlenecked by the throughput of the compute systems. NVIDIA has shown how combining JAX, MaxText and the new NVFP4 format on Blackwell chips can speed up the process significantly without losing quality.
Why every percentage point matters
When training runs on trillions of tokens across thousands of accelerators, saving even one percent of time per step adds up to several days of real calendar time. At frontier scale, that translates directly into millions of dollars in compute costs.
NVFP4, a four-bit floating-point format that debuted in the Blackwell architecture, has become one of the key tools for accelerating matrix operations. Compared with FP8, it packs numbers twice as densely, which reduces memory load and raises the effective throughput of the tensor cores.
The main difficulty is that the four-bit numerical grid is sparse. If misconfigured, gradients easily fall outside its range, which causes training to diverge. NVIDIA and the MaxText team addressed this with custom scaling schemes and dynamic loss scaling.
How mixed precision works with NVFP4
Mixed-precision training is not a new approach: FP8 and BF16 are already industry standards. NVFP4 goes a step further, allowing 4-bit weights in the most heavily loaded matrix multiplications while keeping higher precision where it really matters.
- NVFP4 is applied to weights and activations in GEMM operations
- BF16 or FP32 remain in use for accumulators and normalization
- MaxText automatically routes operations to the appropriate format
- JAX compiles the computation graph through XLA, optimizing kernels for Blackwell
- The result is higher throughput at comparable or lower power consumption
The stack and what to change in code
MaxText is an open-source, high-performance training framework built on JAX and developed by Google. It was originally created for TPUs but is being actively adapted for GPU clusters, so the partnership with NVIDIA is a natural fit.
NVIDIA has included low-level NVFP4 kernels in cuBLAS and cuDNN, and JAX/XLA has gained support for these operations through dedicated adapters. Developers do not need to rewrite training code by hand: it is enough to enable the right flags in the MaxText configuration and make sure the cluster has Blackwell chips (B100, B200, GB200).
"Numerical precision is one of the highest-leverage parameters, but low-bit mixed-precision pretraining is hard to get right," the NVIDIA
Developer Blog team notes.
What this means
For teams pretraining frontier models, NVFP4 on Blackwell is a nearly free speedup: an existing JAX and MaxText stack needs only minimal configuration changes. At the scale of hundreds or thousands of GPUs, even a 10-15% gain in throughput directly shortens time-to-checkpoint and the overall compute budget.
The race for pretraining efficiency is entering a phase that is a battle over numerical precision.
- Nov 1, 2026Google taught its StreamVibe video agent to decide when to step in on its own: +10.7%
- Nov 1, 2026OpenAI Rewrites GPT Behavior Rules: Five Values and a Chain of Command
- Nov 1, 2026Voice bots built on LLMs turn to Jev, a fast classifier, for decisions in 200–500 ms
- Nov 1, 2026Google admits AI Mode cuts search revenue, shares fall 15%
Key Questions Answered
Why every percentage point matters?
When training runs on trillions of tokens across thousands of accelerators, saving even one percent of time per step adds up to several days of real calendar time. At frontier scale, that translates directly into millions of dollars in compute costs. NVFP4, a four-bit floating-point format that debuted in the Blackwell architecture, has become one of the key tools for accelerating matrix operations. Compared with FP8, it packs numbers twice as densely, which reduces memory load and raises the effective throughput of the tensor cores. The main difficulty is that the four-bit
How mixed precision works with NVFP4?
Mixed-precision training is not a new approach: FP8 and BF16 are already industry standards. NVFP4 goes a step further, allowing 4-bit weights in the most heavily loaded matrix multiplications while keeping higher precision where it really matters. NVFP4 is applied to weights and activations in GEMM operations BF16 or FP32 remain in use for accumulators and normalization MaxText automatically routes operations to the appropriate format JAX compiles the computation graph through XLA, optimizing kernels for Blackwell The result is higher throughput at comparable or lower powe
What are the key details on The stack and what to change in code?
MaxText is an open-source, high-performance training framework built on JAX and developed by Google. It was originally created for TPUs but is being actively adapted for GPU clusters, so the partnership with NVIDIA is a natural fit. NVIDIA has included low-level NVFP4 kernels in cuBLAS and cuDNN, and JAX/XLA has gained support for these operations through dedicated adapters. Developers do not need to rewrite training code by hand: it is enough to enable the right flags in the MaxText configuration and make sure the cluster has Blackwell chips (B100, B200, GB200). "Numerical
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.