Home AI Lab for 200,000 Rubles
Five years ago, a Tesla V100 cost $8,000. Now it sells for $1,500. That has broken the economics of cloud GPUs: buying your own hardware is now cheaper than paying a provider for a month. We look at which models run on the V100, where the card struggles, and whether a 200,000-ruble investment pays off.
AI-processed from Habr AI; edited by Hamidun News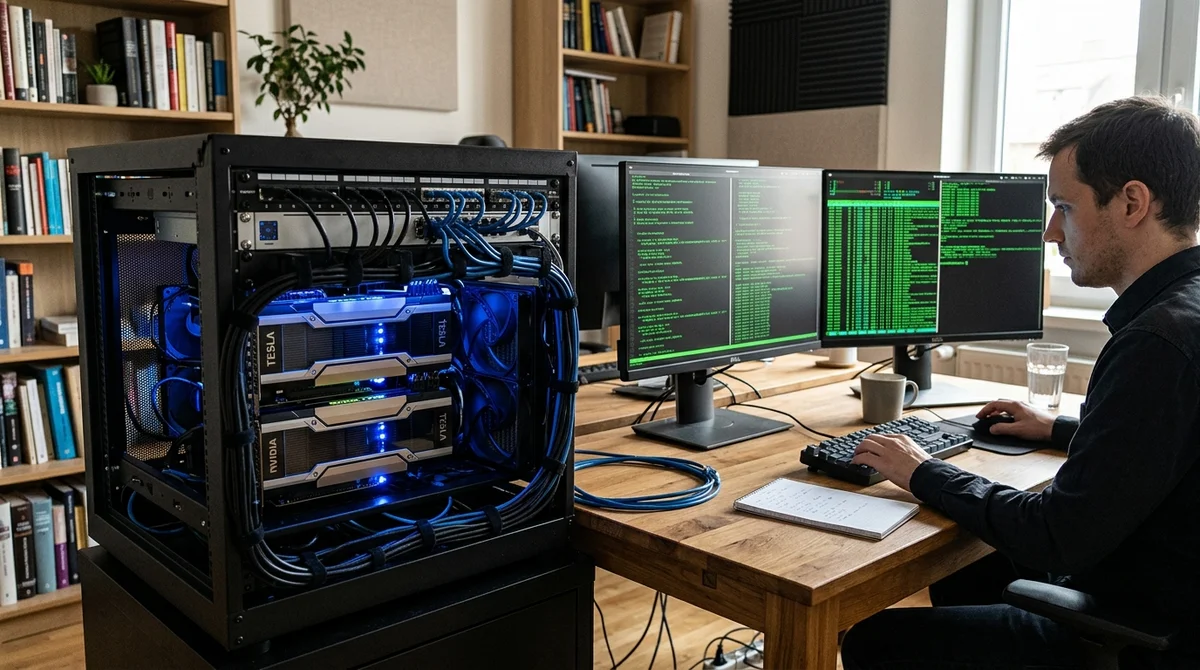
The Tesla V100 graphics card cost eight thousand dollars in 2017. Now it sells on the secondary market for around fifteen hundred. This number broke the economics of cloud GPUs. On Amazon or Vast.ai, renting a V100 will cost you 0.40–0.80 dollars per hour, or 300–600 per month. Buy two V100s, assemble a server for 200 thousand rubles — it will pay for itself in six months. The author of the test bought exactly this and tested 128 different neural networks: from small LLMs to video generators. Here's what happened.
Why is V100 so cheap?
Tesla V100 is a professional card for data centers, released in 2017. 32 gigabytes of memory, 235 TFLOPS in half-precision, 125 watts TDP. Released in huge quantities, then A100 came out. Cloud farms sold off old V100s for pennies. Individual miners and startups bought up the remainder. Now the secondary market is flooded with cards, and the price has fallen even further. The chip is outdated in terms of its craft, but for inference — it's ideal.
Where does V100 stumble?
The table is honest: V100 breaks on TensorFlow (CPU-bound computation optimization is weak). Video generation takes five minutes on Flux.1 — you'd freeze waiting. Text generation is decent, but not fast: Llama 2 70B outputs 80 tokens per second on int4. For comparison, cloud A100 gives 300+. There are nuances with memory: 32 gigs is enough for most models, but running two 70-billion models simultaneously — won't work.
Real benchmarks
- Mistral 7B: 200 tokens/sec (int4)
- Llama 2 70B: 80 tokens/sec (int4)
- Stable Diffusion 1.5: 0.8 seconds per image
- Stable Diffusion XL: 2.5 seconds
- Whisper Large: 0.3 real-time (60-minute audio in 18 minutes)
- Flux.1: 300 seconds per 1024×1024
Economics: cloud or metal?
Cloud GPUs (Lambda, Vast.ai) cost 0.40–0.80 $/hour on V100. Monthly rental: 300–600 dollars. Our server pays for itself in 4–6 months of operation. Advantages of local: electricity is cheaper than cloud traffic, full control, no latency. Disadvantages: responsibility for hardware, cooling, upgrades — all on you.
What does this mean
A local AI server is not a replacement for the cloud, but a complement. If you're running models every day, you've tested the idea, you know which neural networks you need — a 200 thousand ruble server saves tens of thousands per year and gives you final control over infrastructure.
- Oct 23, 2026Zhejiang University Publishes First Survey of Egocentric AI for Smart Glasses
- Oct 23, 2026Meta to Use Muse Spark 1.3 in Medical Research, Promises a 10x Speedup
- Oct 23, 2026Groq Launches Meta Muse Spark Open: 816B Parameters and 350+ Tokens/s
- Oct 23, 2026Meta's Muse Agent Hits 5M US Downloads in 22 Days, Faster Than ChatGPT
Key Questions Answered
Why is V100 so cheap?
Tesla V100 is a professional card for data centers, released in 2017. 32 gigabytes of memory, 235 TFLOPS in half-precision, 125 watts TDP. Released in huge quantities, then A100 came out. Cloud farms sold off old V100s for pennies. Individual miners and startups bought up the remainder. Now the secondary market is flooded with cards, and the price has fallen even further. The chip is outdated in terms of its craft, but for inference — it's ideal.
Where does V100 stumble?
The table is honest: V100 breaks on TensorFlow (CPU-bound computation optimization is weak). Video generation takes five minutes on Flux.1 — you'd freeze waiting. Text generation is decent, but not fast: Llama 2 70B outputs 80 tokens per second on int4. For comparison, cloud A100 gives 300+. There are nuances with memory: 32 gigs is enough for most models, but running two 70-billion models simultaneously — won't work.
Economics: cloud or metal?
Cloud GPUs (Lambda, Vast.ai) cost 0.40–0.80 $/hour on V100. Monthly rental: 300–600 dollars. Our server pays for itself in 4–6 months of operation. Advantages of local: electricity is cheaper than cloud traffic, full control, no latency. Disadvantages: responsibility for hardware, cooling, upgrades — all on you.
Access Frontier LLMs & Multimodal AI in One Workspace
Discover NomadNet AI (nomadnet.ai) — unified access to frontier language models, research synthesis, and multimodal workflows.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.