AWS SageMaker adds full production monitoring for LLMs
AWS has built full LLM monitoring into SageMaker AI. New Grafana dashboards track GPU utilization, token throughput and response quality. The feature is aimed at production use with popular models such as Llama, Mistral and Claude.
AI-processed from AWS Machine Learning Blog; edited by Hamidun News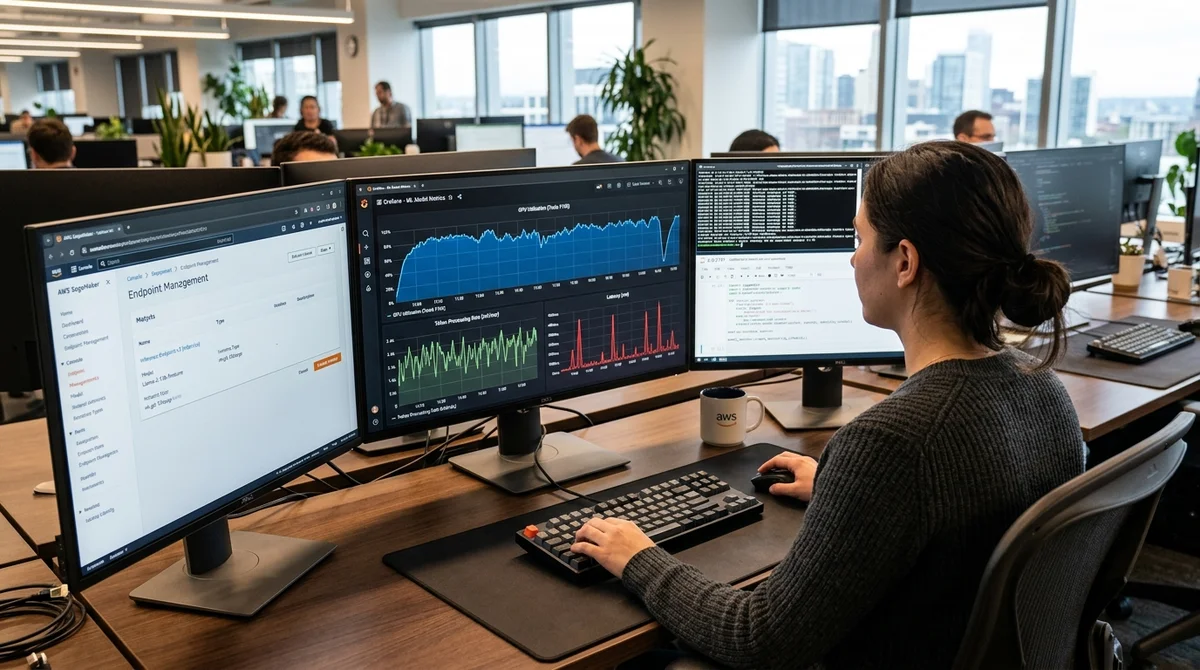
AWS has added comprehensive monitoring for LLMs running on the SageMaker AI platform. With Amazon Managed Grafana, teams can now watch both technical metrics (GPU usage, latency) and quality indicators (response accuracy, hallucinations).
What gets monitored
AWS defines two categories of metrics. The first is resource metrics: GPU utilization, memory usage and the number of tokens processed per second. The second is model quality: response latency, generation accuracy, the presence of hallucinations and adherence to the original instructions.
The new dashboards automatically collect data from SageMaker endpoints and display it in real time. This matters: in production, it is not enough to see that "the server is running"; you also need to know that "the model is answering correctly."
The built-in metrics include:
- GPU utilization and memory usage
- Processing speed for incoming and outgoing tokens
- Latency (the delay between a request and the model's response)
- Toxicity and hallucinations in the output
- Instruction adherence and compliance metrics
Why it matters
An LLM in production is not just hardware that has been switched on and is running. The model may load and the processor may be active, yet the quality of the answers may be poor. The model may give wrong answers, run slowly or learn undesirable behavior.
Previously, engineers had to integrate logging by hand into Prometheus, ELK or other monitoring systems. That took time and a deep understanding of the metrics. Now the tooling is built directly into SageMaker.
AWS offers ready-made dashboard templates for popular models, including Llama, Mistral and Claude. An engineer can deploy monitoring in a few clicks without writing custom code.
When it helps
Full monitoring is critical when an LLM serves real users or supports important business processes. Examples include a customer support chatbot, an AI assistant for document analysis, an automatic content generator and a knowledge-base search assistant.
If a model starts producing longer, stranger or less useful answers, the metrics show it before user complaints arrive. A sudden drop in GPU utilization can point to problems in the request queue or to memory exhaustion.
AWS stresses that observability is not a temporary fix but a
foundation for reliable production deployment of LLMs.
What this means
Monitoring LLMs is gradually becoming standard, just as it is for ordinary web applications. AWS is making it more accessible by building ready-made observability tools directly into the SageMaker platform.
For engineering teams, this means less time spent writing custom integration scripts and more focus on the quality of the LLMs themselves. That should speed up the deployment of AI solutions in production.
- Oct 31, 2026Worldwide Express hands disputed invoices to AI agents and cuts unresolved disputes by 75%
- Oct 30, 2026AWS gives coding agents a live site preview straight from an isolated session
- Oct 30, 2026MoEngage Opens 400 Private APIs to AI Agents Through AgentCore Gateway, Without Building Its Own MCP Servers
- Oct 29, 2026NVIDIA Nemotron 3.5 Super VL: 120B Parameters, 12B Active, Running on AWS
Key Questions Answered
What gets monitored?
AWS defines two categories of metrics. The first is resource metrics: GPU utilization, memory usage and the number of tokens processed per second. The second is model quality: response latency, generation accuracy, the presence of hallucinations and adherence to the original instructions. The new dashboards automatically collect data from SageMaker endpoints and display it in real time. This matters: in production, it is not enough to see that "the server is running"; you also need to know that "the model is answering correctly." The built-in metrics include: GPU utilizatio
Why it matters?
An LLM in production is not just hardware that has been switched on and is running. The model may load and the processor may be active, yet the quality of the answers may be poor. The model may give wrong answers, run slowly or learn undesirable behavior. Previously, engineers had to integrate logging by hand into Prometheus, ELK or other monitoring systems. That took time and a deep understanding of the metrics. Now the tooling is built directly into SageMaker. AWS offers ready-made dashboard templates for popular models, including Llama, Mistral and Claude. An engineer ca
When it helps?
Full monitoring is critical when an LLM serves real users or supports important business processes. Examples include a customer support chatbot, an AI assistant for document analysis, an automatic content generator and a knowledge-base search assistant. If a model starts producing longer, stranger or less useful answers, the metrics show it before user complaints arrive. A sudden drop in GPU utilization can point to problems in the request queue or to memory exhaustion. AWS stresses that observability is not a temporary fix but a foundation for reliable production deploymen
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.