AWS shows how to fine-tune Amazon Nova with the Nova Forge SDK and SageMaker Jobs
AWS has walked through how to customize Amazon Nova with the Nova Forge SDK and SageMaker AI. In the example, the team trains a model to classify Stack Overflow questions: the baseline reaches only 13% exact match, SFT lifts it to 77.2%, and RFT to 78.8%, with quasi-EM at 80.6%. The guide also covers deploying the finished model to an inference endpoint.
AI-processed from AWS Machine Learning Blog; edited by Hamidun News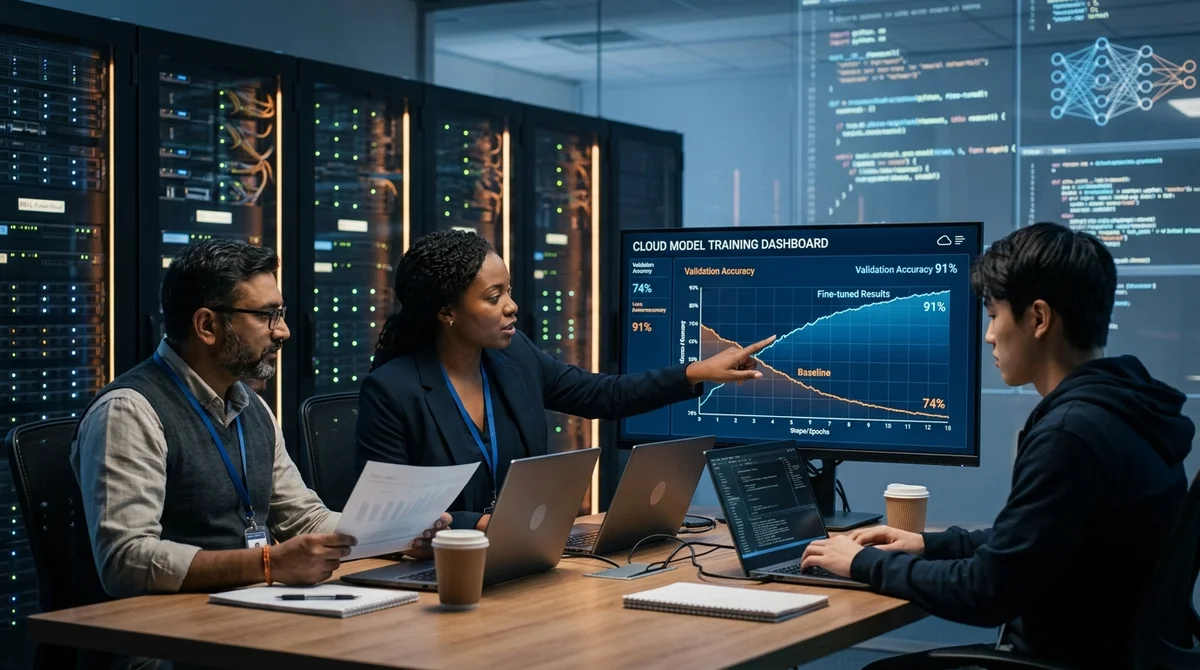
AWS has shown a practical scenario for customizing Amazon Nova models with the Nova Forge SDK and Amazon SageMaker AI. In the guide, the team goes through the whole cycle: from baseline model evaluation to SFT, RFT and rolling out its own inference endpoint.
Scenario and data
AWS positions the Nova Forge SDK as a layer that removes the most tedious part of LLM customization: preparing infrastructure, choosing images, validating configs and launching training recipes. Instead of assembling a pipeline by hand, the developer gets a set of ready-made components for loading a dataset, converting its format, starting a job in SageMaker and then evaluating the result.
The article demonstrates this not on a toy example but on a clear applied task: automatically classifying Stack Overflow questions by quality.
For the experiment, AWS took the Stack Overflow Question Quality dataset of 60 thousand questions from 2016–2020 and randomly selected 4700 records. The model had to assign each question to one of three categories: HQ, LQ_EDIT or LQ_CLOSE. 3500 examples went to SFT and 500 to evaluation. For RFT, AWS used another 700 specialized examples, supplemented with all 3500 SFT records so the model would not lose the answer format it had already learned.
How the training went
The experiment has four steps: a baseline evaluation of the pretrained Nova 2.0, then supervised fine-tuning, then reinforcement fine-tuning, and finally deployment on Amazon SageMaker AI Inference.
AWS uses the `CSVDatasetLoader` class to load CSV files, check the schema and transform data, and `SMTJRuntimeManager` to launch compute. SFT in the example runs on four ml.p5.48xlarge instances, and the SDK can validate environment and parameter compatibility up front, so errors do not surface only after the job has started.
- Baseline shows how the model behaves without fine-tuning
- SFT teaches the correct format and the domain-specific answer pattern
- RFT refines the solution through a reward function
- Deployment can go either to Bedrock or to SageMaker
For RFT, AWS added a simple reward function via Lambda: +1 for the correct class and -1 for a wrong one. Fine-tuning ran on top of the SFT checkpoint on two ml.p5.48xlarge instances, and the run was kept short: just 40 steps. The team also capped output length and added a KL penalty so the model would not drift too far from the behavior fixed during SFT.
In other words, the SDK acts here not merely as a wrapper for launching jobs but as a single point for data preparation, training, logs and rollout.
What the metrics showed
The most useful part of the article is the numbers. Base Nova 2.0 reached only 13% exact match on the three-class task, where random guessing would give about 33.3%. Even when ignoring answer verbosity and extracting just the class label from the text, accuracy was 52.2%. AWS attributes this to two problems: the model was too eager to write long explanations instead of a single label, and it was biased toward answering HQ regardless of the question's real quality.
After a short SFT run, exact match rose to 77.2%, and classification accuracy on extracted labels to 79.0%. The next layer, RFT, added a bit more: exact match climbed to 78.8%, quasi-EM to 80.6%, and F1 to 78.8%. The gain from the reinforcement stage is not huge, but it is steady across almost all key metrics.
AWS also notes that BLEU is nearly useless for this task: when the model answers with a single token such as HQ or LQ_CLOSE, exact match and F1 matter more than n-gram overlap.
What this means
AWS is trying to sell not just another model but a shorter path to tuning it for real applications. If the Nova Forge SDK really handles validation, launch, monitoring and deployment in one interface, teams will find it easier to test hypotheses on niche datasets without a separate MLOps quest for every iteration.
- Oct 31, 2026Worldwide Express hands disputed invoices to AI agents and cuts unresolved disputes by 75%
- Oct 30, 2026AWS gives coding agents a live site preview straight from an isolated session
- Oct 30, 2026MoEngage Opens 400 Private APIs to AI Agents Through AgentCore Gateway, Without Building Its Own MCP Servers
- Oct 29, 2026NVIDIA Nemotron 3.5 Super VL: 120B Parameters, 12B Active, Running on AWS
Key Questions Answered
What are the key details on Scenario and data?
AWS positions the Nova Forge SDK as a layer that removes the most tedious part of LLM customization: preparing infrastructure, choosing images, validating configs and launching training recipes. Instead of assembling a pipeline by hand, the developer gets a set of ready-made components for loading a dataset, converting its format, starting a job in SageMaker and then evaluating the result. The article demonstrates this not on a toy example but on a clear applied task: automatically classifying Stack Overflow questions by quality. For the experiment, AWS took the Stack Overf
How the training went?
The experiment has four steps: a baseline evaluation of the pretrained Nova 2.0, then supervised fine-tuning, then reinforcement fine-tuning, and finally deployment on Amazon SageMaker AI Inference. AWS uses the `CSVDatasetLoader` class to load CSV files, check the schema and transform data, and `SMTJRuntimeManager` to launch compute. SFT in the example runs on four ml.p5.48xlarge instances, and the SDK can validate environment and parameter compatibility up front, so errors do not surface only after the job has started. Baseline shows how the model behaves without fine-tun
What the metrics showed?
The most useful part of the article is the numbers. Base Nova 2.0 reached only 13% exact match on the three-class task, where random guessing would give about 33.3%. Even when ignoring answer verbosity and extracting just the class label from the text, accuracy was 52.2%. AWS attributes this to two problems: the model was too eager to write long explanations instead of a single label, and it was biased toward answering HQ regardless of the question's real quality. After a short SFT run, exact match rose to 77.2%, and classification accuracy on extracted labels to 79.0%. The
Ship AI Faster with Founders, Engineers & Weekly Architecture Reviews
Inside Vibe Club (hamidun.com/club) — weekly live masterminds with Zhemal Khamidun, Tech Radar, full LMS access, and 370+ production Claude Code skills.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.