#LLM
Curated coverage on «LLM»: releases, research, benchmarks, open-source.
Japanese megabanks to gain access to Claude Mythos for finding vulnerabilities
Japan’s three largest banks — MUFG, Mizuho, and SMFG — will become the first Japanese institutions to gain access to Claude Mythos, Anthropic’s secure AI model for…
DeepMind built a Gemini-powered AI mouse so users don't switch to chats
Google DeepMind unveiled a Gemini-based AI mouse that analyzes the context around the cursor and lets users issue voice commands without opening a separate window.
Graphon AI raises $8.3M for a data-processing layer for LLMs
Startup Graphon AI has emerged from stealth with $8.3 million in funding to develop graph data preprocessing — something modern language models lack.
How to save 70% of Claude tokens with targeted code access
How 15 AI models approach finding the optimal XML parser for iOS: benchmark results
Nous Research introduced Lighthouse Attention to accelerate LLM training
AI agent security in production: a practical guide to Red Teaming
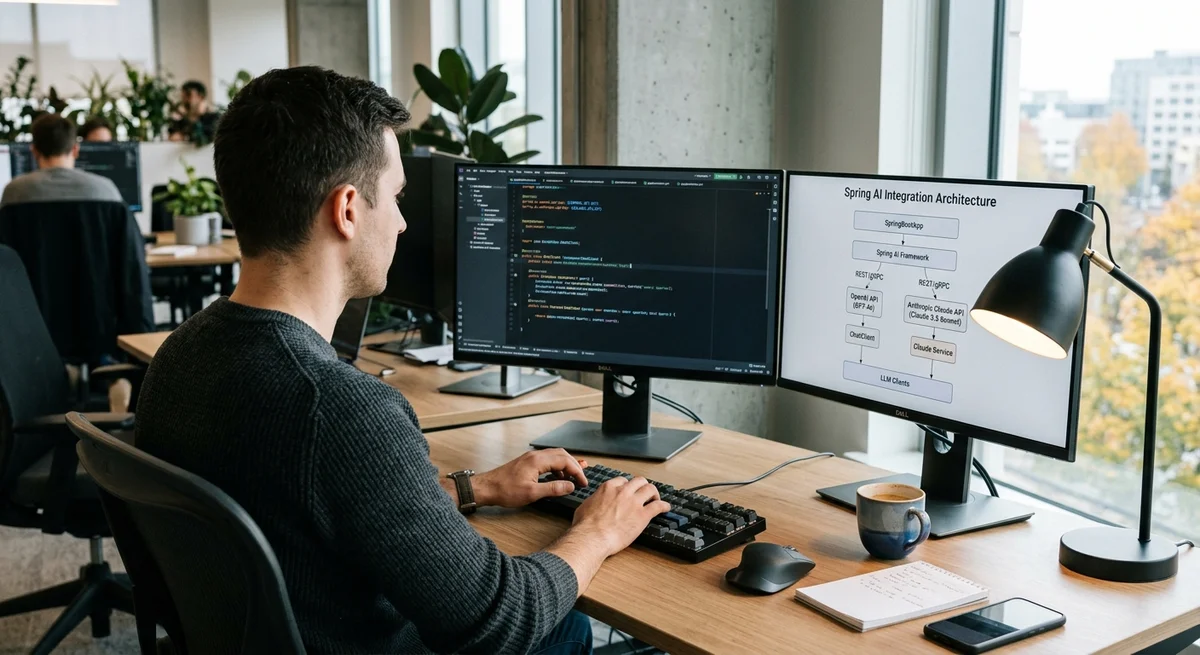
Spring AI made it easier to integrate Java applications with Claude and other LLM providers
Spring AI provides ready-made techniques for integrating LLM providers into Java, including working with Claude from Anthropic. The article covers practical…
Claude AI resolves arbitration disputes in 12 minutes instead of weeks
An author created a Telegram bot on Claude Sonnet that analyzes court cases in 12 minutes. In three out of four tests, its decision matched the verdicts of human…
AI agent in one day: a local prototype without the cloud or developers
Samsung Galaxy Z Fold8 to Be First to Get Gemini Intelligence
Shadow AI in 63% of companies: how tools outpaced corporate policies
Nous Research sped up LLM pretraining 2.5x without changing the architecture
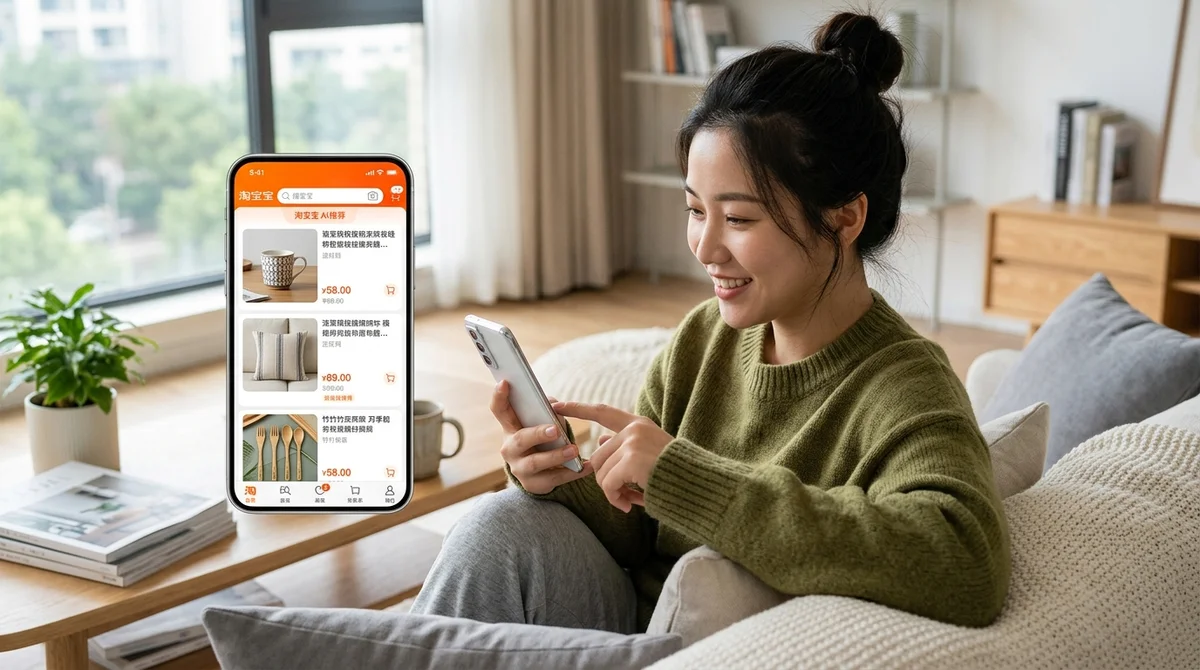
Alibaba integrated AI assistant into Taobao marketplace: the end of search queries
Alibaba integrated Qwen AI assistant into Taobao marketplace: instead of searching by keywords, shoppers now describe the product they need, and the agent finds the…
Can LLMs find flaky tests from code? Study says no
A study found that LLMs are poor at identifying unreliable tests, even when dataset metrics suggest otherwise.