#LLM
Curated coverage on «LLM»: releases, research, benchmarks, open-source.
Local Qwen3.6-27B vs. cloud models: why privacy is not the main point
Local Qwen3.6-27B shows it can compete with cloud-based Claude and GPT. The advantage of local models extends far beyond privacy — it is control, speed, and…
One-Third of Vercel Deployments Are Now Done by AI Agents Instead of People
On the Vercel platform, AI agents now initiate 30% of all deployments instead of people—a 1000% increase over six months. The company is launching new…
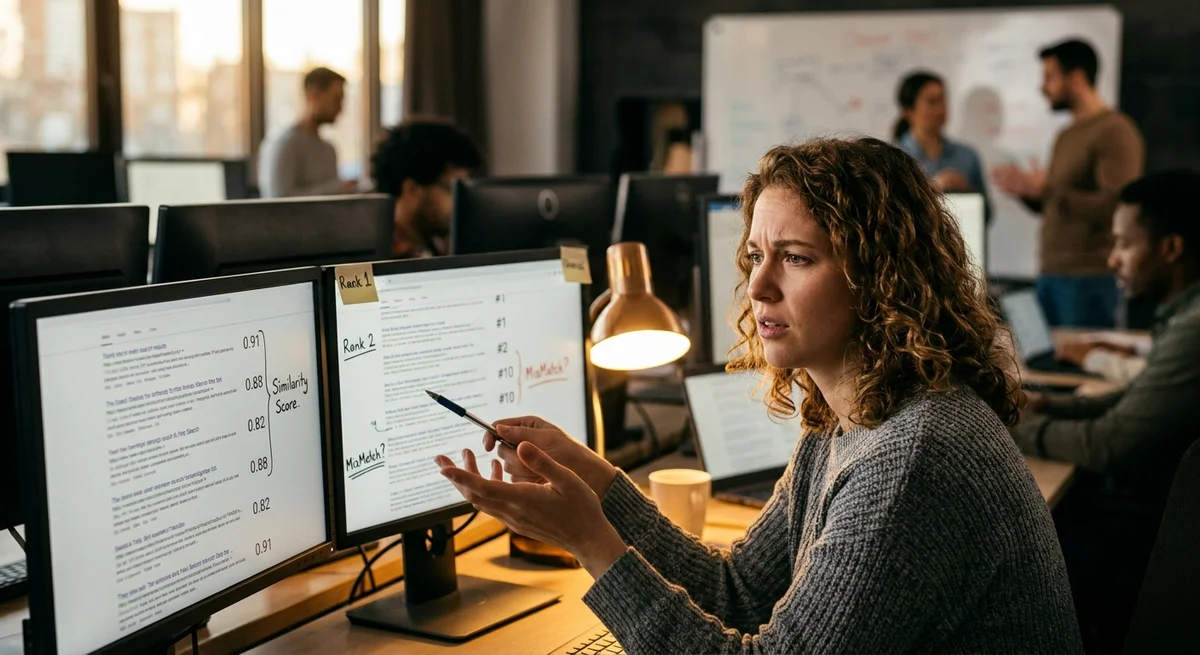
RAG systems break on real data: the culprit is retrieval, not the model
A RAG system looks perfect in a demo, but once testing starts on real questions, half of its answers turn out to be wrong. The problem is not GPT-4 or Claude — it…
Apple will present iOS 27 with a private AI assistant at WWDC
Amazon Nova 2 for content moderation: a structured prompting approach
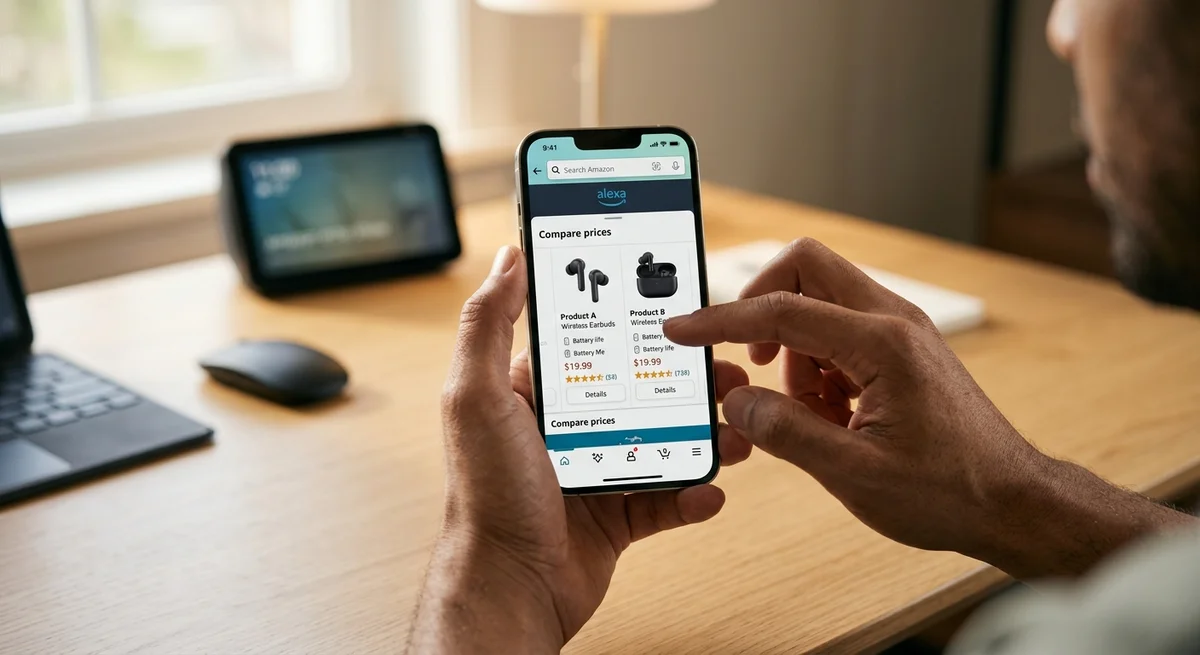
Amazon launched Alexa for Shopping, combining Rufus with the Alexa+ platform
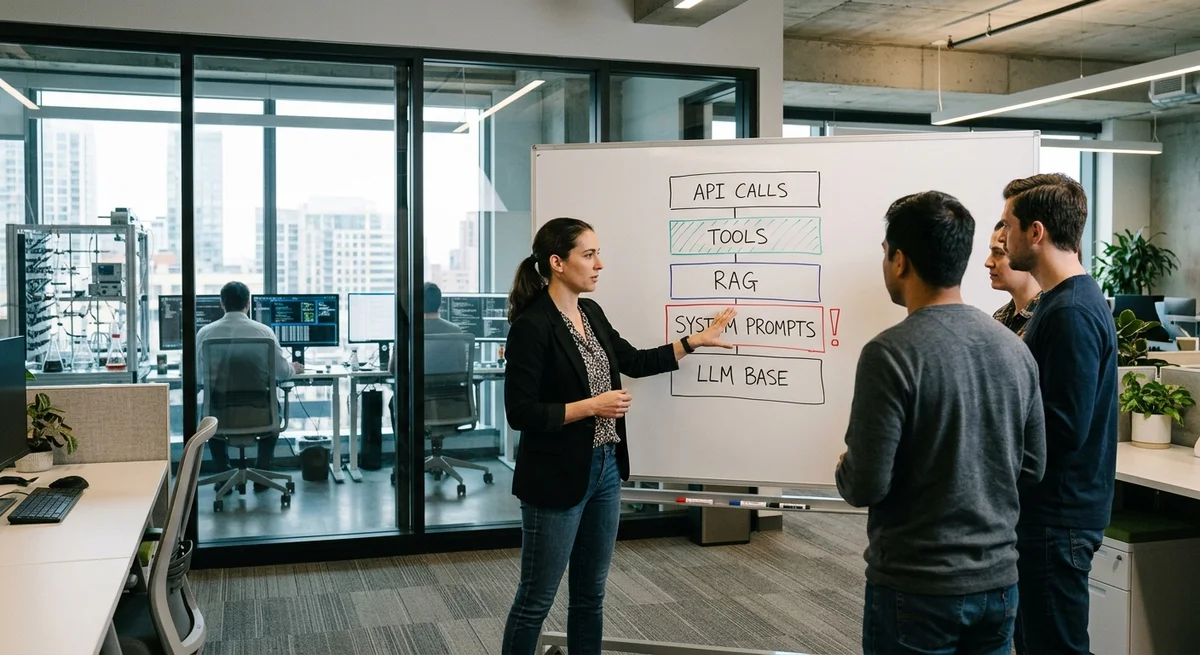
Why bots based on protected LLMs are frequently hacked: analysis of 14,000 GPTs
RAG in enterprise: why 80% of problems are in data, not in the model
A RAG prototype is built in a week and demonstrated. It looks magical: the model answers questions about your documents without hallucinating from general knowledge.
Why AGI benchmarks will never be objective
Researchers are trying to develop tests for strong AI, but they face a fundamental problem: even human intelligence has 70+ definitions, and scientists do not agree…
Google Third in AI-Model Race: I/O 2026 Strategy
At Google's I/O 2026 conference, which kicks off this week, the company will be in an unusual position for itself — not as a leader, but as the third player in the…
Coding by feel: how an ordinary person built a database with Claude
A Wired journalist tried to write a program with no development experience, using only Claude. The result was a working database for tracking minor complaints.