#LLM
Curated coverage on «LLM»: releases, research, benchmarks, open-source.
Anthropic Raised $65 Billion at $965 Billion Valuation Following Explosive Claude Growth
Anthropic secured record-breaking $65 billion funding and reached a $965 billion valuation. The company will invest in expanding computational capacity, safety…
Scientists Created MEMO — A Framework for Expanding LLM Memory Without Retraining
Scientists proposed MEMO — a framework that allows LLMs to learn from new data without retraining the base model, using a separate memory module.
EAGLE 3.1: How to Fix Speculative Decoding Instability in LLMs
A joint release by the EAGLE team, vLLM, and TorchSpec fixes a critical speculative decoding issue — attention drift — that was slowing down large language model…
Anthropic Released Opus 4.8: Model Showed Equal Alignment with Claude Mythos
Mistral Released Voxtral TTS — Lightweight Text-to-Speech Model for Voice Agents
Mistral AI Renamed Le Chat to Vibe — a Universal AI Agent for Work and Code
Azerbaijani LLM on SageMaker: How Azercell Solved the Rare Language Problem
OpenAI to Integrate Brazilian Media Content from Folha and UOL into ChatGPT
OpenAI has reached an agreement with major Brazilian publishers Grupo Folha and Grupo UOL to feature their content in ChatGPT with proper attribution.
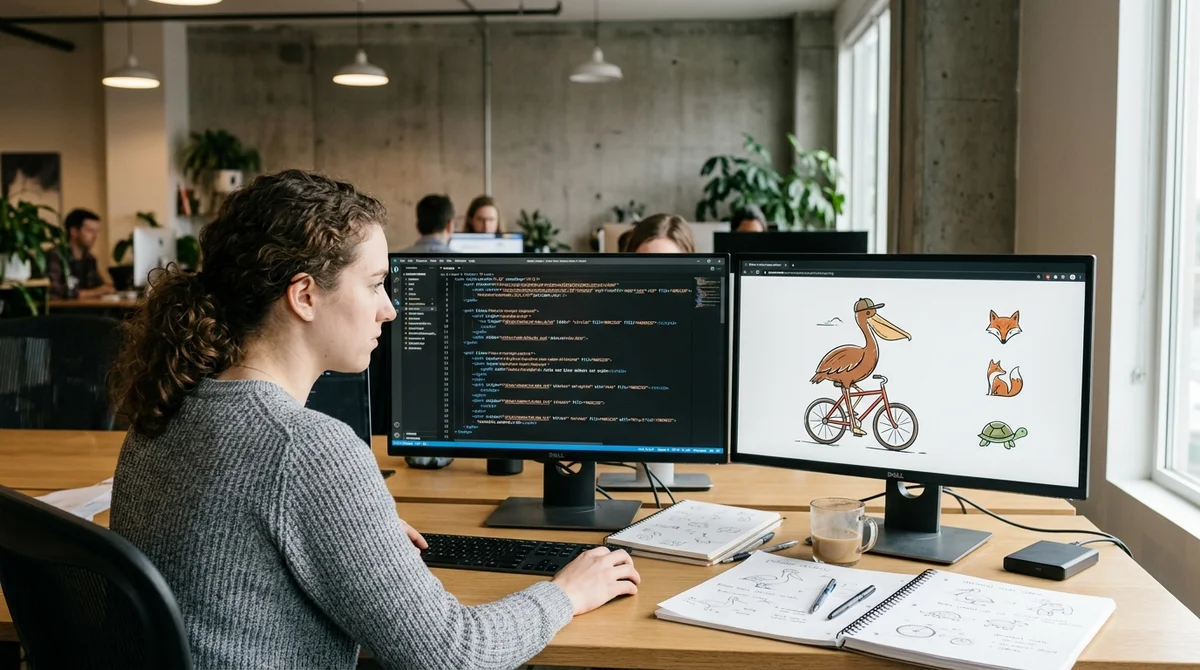
Pelicans on Bicycles: Simon Willison's Amusing Test for LLMs
Simon Willison, Django creator, invented a fun test for LLMs: asking an AI to draw an SVG pelican on a bicycle. The results reveal unexpected insights about neural…
Liquid AI Releases LFM2.5-8B: A Compact MoE Model with 128K Context
Warp Launched a Platform for Development Coordination Through AI Agents Based on GPT-5.5
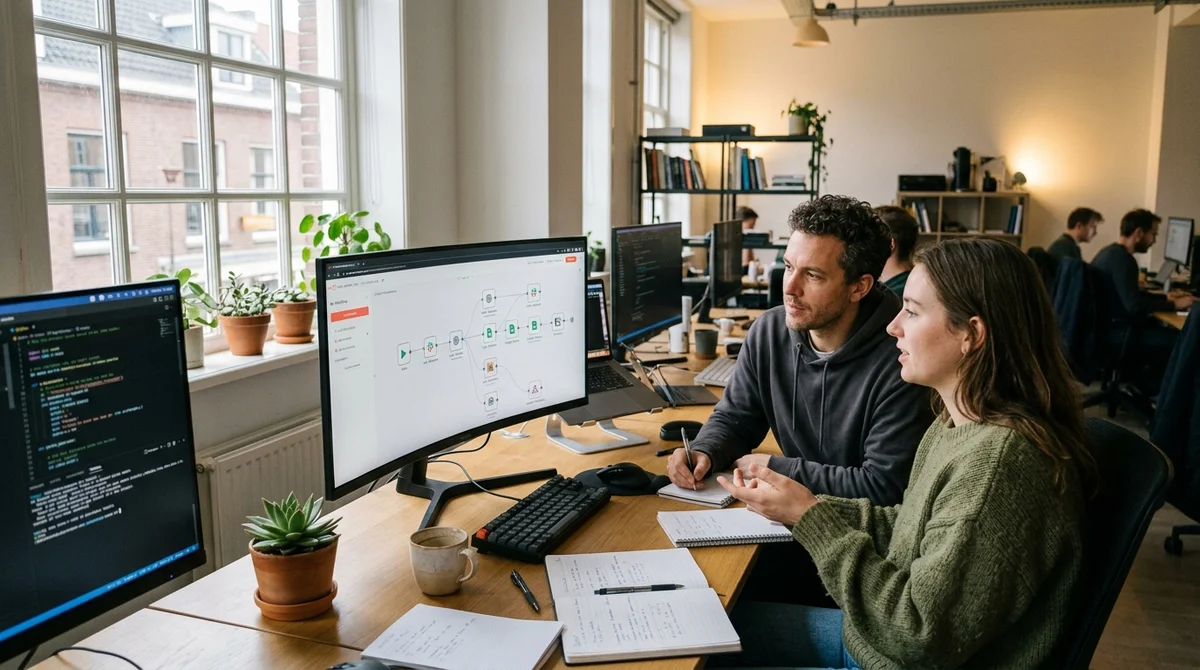
Developer Created an AI-Integrator Profession: How to Build a Workflow on n8n
Mistral AI Launches Connectors: Built-in Integrations for AI Agents
Australian tribunal overwhelmed: AI assistants doubled case flow
Australia's Fair Work Commission reported a 70% increase in workload over three years, partly due to the proliferation of generative AI tools in lawsuit preparation.
IBM and Artificial Analysis create benchmark: AI agents fail at IT tasks
Large language models scored less than 50% on the new ITBench-AA benchmark for assessing AI agents' ability to solve corporate IT tasks. This shows that full…