Why Bots Built on Hardened LLMs Get Hacked So Often: An Analysis of 14,000 GPTs
Base LLMs are protected against attacks, but the bots built on top of them are vulnerable. The culprit is the orchestration layer: system prompts, RAG, tools and webhooks. An analysis of 14,904 custom GPTs showed that this layered architecture is what becomes the weak point for attackers.
AI-processed from Habr AI; edited by Hamidun News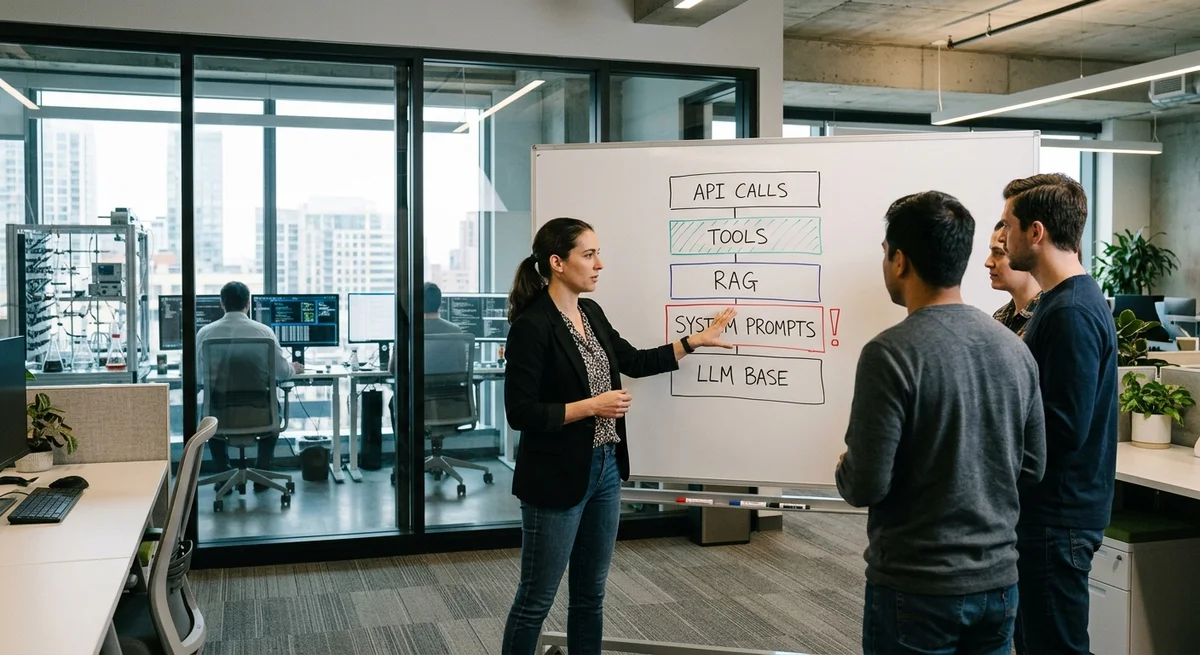
A secure base LLM does not guarantee a secure bot. A paradox? No, just architecture. When you take a protected model such as GPT or Claude and wrap it in a system prompt, then add RAG, tools and APIs, you create a new attack surface. This is called the orchestration layer, and it is where bots get hacked even though the model itself is protected.
How the base model is protected
Base LLMs go through serious safety training: developers teach them to refuse dangerous requests. OpenAI, Anthropic and other teams spend months making sure the model understands which requests are unsafe. On top of that comes RLHF (reinforcement learning from human feedback), which aligns the model with human preferences about what is ethical and what is not. The result: if you ask GPT directly to hack a website or hand over personal data, it will refuse.
Where the problems begin
But as soon as you wrap the model in a bot, whether a Telegram bot, a web app or an AI agent, you add a whole layer of components, each of which is potentially unsafe:
- System prompts: instructions to the bot that sometimes override the model's training and can be injected
- Conversation memory: a history of requests that keeps growing and can be used for a contextual attack
- RAG (Retrieval-Augmented Generation): external databases and documents that can be seeded with false data
- Tools and function calls: direct access to APIs, email, databases and payment systems
- Webhook logic and external services: untrusted data sources that can be compromised
Each layer adds a new attack vector. A system prompt can be injected through user input. Conversation memory can be clogged with prompt injection patterns. RAG can return poisoned data from a compromised source. Tools can be used to bypass the model's restrictions.
What the analysis showed
Researchers on arXiv analyzed 14,904 custom GPTs, public agents created by users on the OpenAI platform. The result: the vast majority are vulnerable to basic attacks on the orchestration layer. An attacker does not need to hack the model itself. Injecting the system prompt or poisoning a RAG source is enough.
Most vulnerabilities lie not in the model but in how it is wrapped.
That means you can use the safest LLM on the planet, and a poor architecture will cancel out its advantages. Bots get weaker as they scale, because every new component adds complexity and new entry points.
What this means
Securing an AI bot is not only a matter of choosing a model; it is a comprehensive architectural task. You need to protect system prompts from injection, validate input data, control RAG sources, limit tool permissions and log all actions. Otherwise, a fine LLM becomes a fine security hole.
- Nov 1, 2026Local models lose to Opus and Codex: 0.21 on a MacBook versus 1.00 for Codex
- Nov 1, 2026Kimi scores 96.2% on a 1C database analytics test and emerges as a fallback if Claude access is blocked
- Nov 1, 2026OpenAI Rewrites GPT Behavior Rules: Five Values and a Chain of Command
- Nov 1, 2026Google admits AI Mode cuts search revenue, shares fall 15%
Key Questions Answered
How the base model is protected?
Base LLMs go through serious safety training: developers teach them to refuse dangerous requests. OpenAI, Anthropic and other teams spend months making sure the model understands which requests are unsafe. On top of that comes RLHF (reinforcement learning from human feedback), which aligns the model with human preferences about what is ethical and what is not. The result: if you ask GPT directly to hack a website or hand over personal data, it will refuse.
Where the problems begin?
But as soon as you wrap the model in a bot, whether a Telegram bot, a web app or an AI agent, you add a whole layer of components, each of which is potentially unsafe: System prompts: instructions to the bot that sometimes override the model's training and can be injected Conversation memory: a history of requests that keeps growing and can be used for a contextual attack RAG (Retrieval-Augmented Generation): external databases and documents that can be seeded with false data Tools and function calls: direct access to APIs, email, databases and payment systems Webhook logic
What the analysis showed?
Researchers on arXiv analyzed 14,904 custom GPTs, public agents created by users on the OpenAI platform. The result: the vast majority are vulnerable to basic attacks on the orchestration layer. An attacker does not need to hack the model itself. Injecting the system prompt or poisoning a RAG source is enough. Most vulnerabilities lie not in the model but in how it is wrapped. That means you can use the safest LLM on the planet, and a poor architecture will cancel out its advantages. Bots get weaker as they scale, because every new component adds complexity and new entry po
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.