Russian Costs Twice as Much in ChatGPT, and Tokenization Is to Blame
In ChatGPT and other cloud LLMs, Russian text costs twice as much to process as English. The cause is how neural networks split text into tokens. An English word usually takes one token, while a Russian word needs 2-4 pieces. As a result, the effective context window shrinks by half.
AI-processed from Habr AI; edited by Hamidun News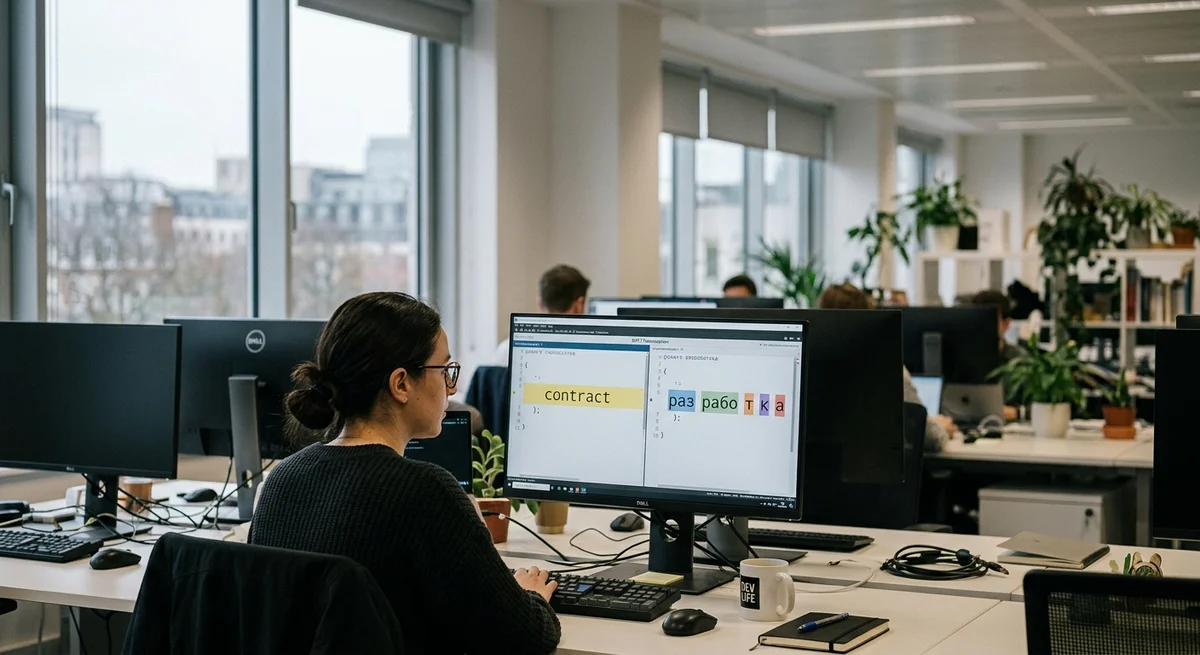
When you send a request to ChatGPT or another cloud-based neural network, the model doesn't work with letters and words directly. It first splits the text into tokens, small chunks of meaning that the model can process. That split determines how much a request costs, how fast the response arrives, and how much information fits into the context window at once.
How tokenization works
Tokenization is the process of cutting text into pieces, and different neural networks do it differently. English text gets cut very efficiently: a word usually takes one or two tokens. The word "contract" is always a single token. An English text of 1000 words needs roughly 1200-1500 tokens.
Russian is less fortunate: the same content requires 2-3 times as many pieces. The word «разработка» ("development") takes two to three tokens. «Программирование» ("programming") takes three to four. An adjective like «искусственный» ("artificial") can take four to five tokens. A Russian text of 1000 words needs 2500-3500 tokens.
This happens because English was used far more heavily than Russian to train today's large language models. Its vocabulary is better represented in the token dictionary, which model builders assembled from huge volumes of English-language content. To neural networks, Cyrillic remains a foreigner.
What it costs in practice
Because of this tokenization gap, Russian text in cloud services such as OpenAI costs roughly twice as much as English for the same amount of actual information. If you pay 1 dollar to process 1000 tokens of English text, Russian will cost 2 dollars.
The difference is easiest to spot on large projects: localizing an app into Russian, translating documentation, or running a Russian-language chatbot will cost twice as much as the same services for English-speaking users.
But the higher price is only the start of the problem. Russian text is processed noticeably slower because the model has to run through more tokens. More tokens mean a longer wait for a response.
The context window, the amount of memory in which the model can hold information, also shrinks by half in terms of actual content. If a model has a context window of 128 thousand tokens, in Russian you can fit only half as much information.
Who gets hit hardest
- Russian-speaking developers who use AI to work with documentation and code
- Companies that process large volumes of Russian text (translation, chatbots, analytics)
- Russian-language startups that build products on top of LLMs and can't afford OpenAI costs
- Researchers who work with the Russian language and need in-depth analysis through neural networks
- Writers and publishers who want to use AI to edit and rewrite texts
How to measure it on your own data
The author recommends checking the real token ratio for your specific texts: take a sample in English and in Russian, count the tokens through the OpenAI API, and compare. It takes about five minutes and shows the exact price for your use case.
What it means
The tokenization gap is a hidden tax on the Russian language in the era of large language models. It is not a developer error but a natural consequence of how these models were built: on English-language content from the first generation of the internet.
For the Russian-speaking community, this means accepting reality: either pay more and get slower results, or look for alternatives trained with better Cyrillic support.
- Nov 1, 2026OpenAI Rewrites GPT Behavior Rules: Five Values and a Chain of Command
- Nov 1, 2026Google admits AI Mode cuts search revenue, shares fall 15%
- Oct 31, 2026Author puts his script before an AI jury: the verdict cost 850 thousand tokens
- Oct 31, 2026Anthropic: Fold Subagents Back Into a Single Loop — One Customer's Tasks Ran Twice as Fast
Key Questions Answered
How tokenization works?
Tokenization is the process of cutting text into pieces, and different neural networks do it differently. English text gets cut very efficiently: a word usually takes one or two tokens. The word "contract" is always a single token. An English text of 1000 words needs roughly 1200-1500 tokens. Russian is less fortunate: the same content requires 2-3 times as many pieces. The word «разработка» ("development") takes two to three tokens. «Программирование» ("programming") takes three to four. An adjective like «искусственный» ("artificial") can take four to five tokens. A Russi
What it costs in practice?
Because of this tokenization gap, Russian text in cloud services such as OpenAI costs roughly twice as much as English for the same amount of actual information. If you pay 1 dollar to process 1000 tokens of English text, Russian will cost 2 dollars. The difference is easiest to spot on large projects: localizing an app into Russian, translating documentation, or running a Russian-language chatbot will cost twice as much as the same services for English-speaking users. But the higher price is only the start of the problem. Russian text is processed noticeably slower because
Who gets hit hardest?
Russian-speaking developers who use AI to work with documentation and code Companies that process large volumes of Russian text (translation, chatbots, analytics) Russian-language startups that build products on top of LLMs and can't afford OpenAI costs Researchers who work with the Russian language and need in-depth analysis through neural networks Writers and publishers who want to use AI to edit and rewrite texts
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.