Allen AI's EMO Model Learns to Specialize on Its Own
Researchers at Allen AI have found an interesting effect: when a large mixture of experts is trained on documents from different domains, each expert picks its own specialty. One becomes medical, another political, a third cinematic. Nobody told them what to do. The model stays efficient, too: only 12.5% of experts are activated to process each document, and quality barely drops.
AI-processed from Hugging Face Blog; edited by Hamidun News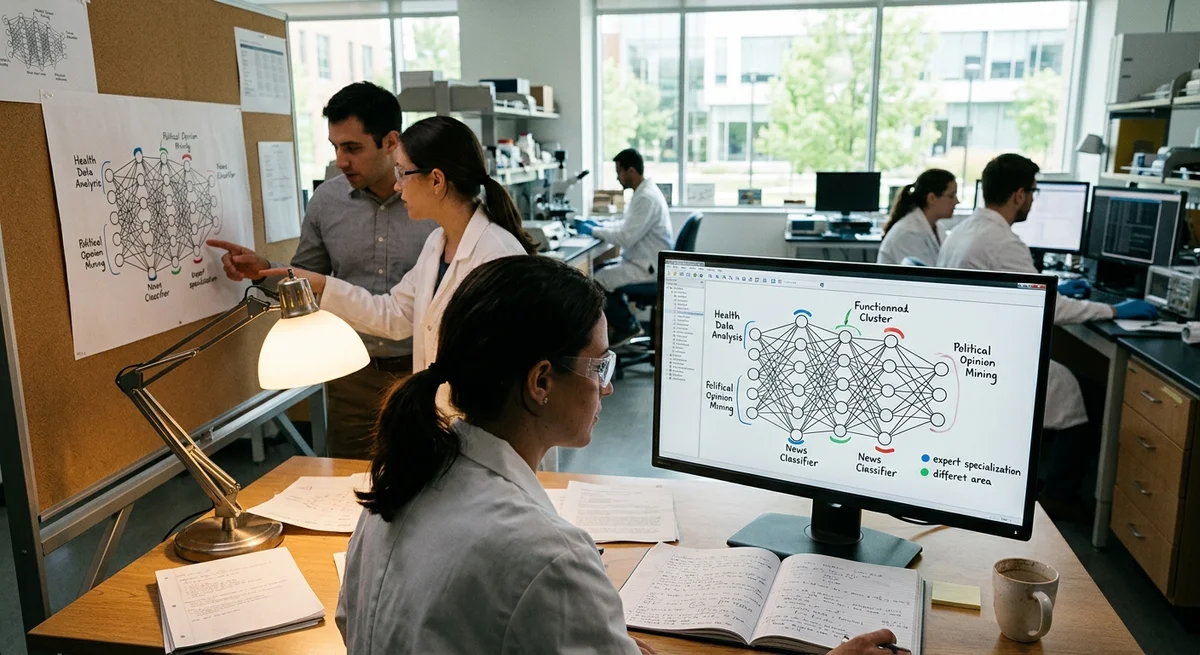
EMO (Emergent Modularity), a neural network from Allen AI, has shown unexpected behavior: when trained on a mix of documents from different domains, each expert specialized in one of them on its own, with no need for explicit data labeling.
How did the EMO model find its specialization without labels?
The model was trained on documents from several domains (medicine, politics, film, news), and each expert automatically settled on one of them, relying only on the content of the texts.
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.