LLM Aggregators: How to Pick Live Free Models and Not Lie About the Result
Picking a free model from a list seems simple. In practice, half the models are unstable, some vanish from the provider's listing, and quality varies. The fix is not an endless catalog but a smarter backend: list cleanup, health checks, fallback between brands, and an honest `actual_model` field in the response.
AI-processed from Habr AI; edited by Hamidun News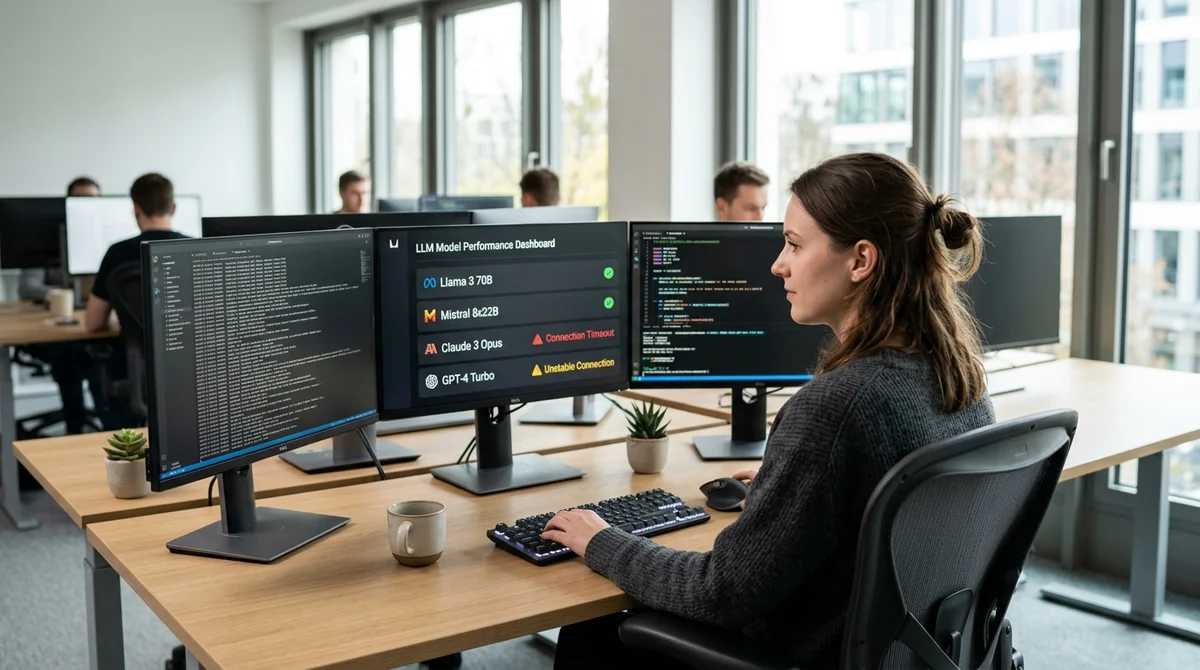
When a project adds an LLM picker, most teams take the most obvious route: a big list of models, the user picks one, the request goes out. Over the short term, it works. Over the long term, it starts to break.
Where the simple approach breaks
The problems show up not in the interface but in the behavior of providers and the models themselves:
- Unstable free models — listed as free, but they respond erratically and drop out during provider downtime
- Models disappear — it was in the listing yesterday; today the provider removed it or closed it to new users
- Quality drops — technically alive, but good only for demos or simple tasks
- Frontend and backend mismatch — the list in the interface is a day or two stale, while the backend knows a different reality
- Errors and redirection — you requested one model and got an error, or the answer came from a completely different model
The biggest problem: the interface does not know which model actually answered. The user chose Claude 3.5, but the answer came from Gemini, and the user never finds out. That creates confusion: if the quality of the answer does not match the selected model, the user loses trust.
A strict engineering loop instead of a catalog
The solution relies not on an endless list but on control at the backend:
Step 1: list cleanup. The backend gets the raw list of models from the provider and filters it: it keeps only suitable free options, discards unstable ones, and removes duplicates. You can add health checks, which periodically ping each model to see whether it is alive.
Step 2: one model per brand. Even if OpenAI has 5 free models in its listing, only one goes to the frontend: the most stable. This simplifies the user's choice and lowers the chance of landing on a bad model.
Step 3: fallback between brands. During a real request, if the first model returns an error, the system automatically tries the second, then the third. The user does not learn about the failure; for them it simply takes a bit longer.
Step 4: honesty in the response. Return not only the generated text but also actual_model, the model that really generated it. Now the interface can tell the user honestly: "This answer is from GPT 4o mini, because the primary model was down."
"The problem is not how to display a list of models nicely.
The problem is how to build a system that picks live free models and does not lie about the result" — that is the essence of the task.
This turns an unstable catalog into a predictable loop. If a provider removes a model, the backend notices at the next check and updates the list on the frontend. If a model goes down, fallback kicks in and the user gets an answer from another provider.
What this means
Choosing an LLM stops being a UI task and becomes an engineering task, with data cleanup, health checks, fallback logic, and honest tracking. For the product, that means reliability and fewer support questions. For the user, the choice works, answers arrive, and the interface does not lie.
- Nov 2, 2026NC State's AICG Framework Cuts MAE by 50.3% on Math Answer Grading
- Nov 2, 2026We Audited 929 Automations at Alpina: What Corporate AI Training Should Look Like in 2026
- Nov 2, 2026I Interrogated 6 AI Models About Myself Through a Procurement Manager's Eyes: Amazon, Esoterica, 'Telo Hudelo' and 5 Holes We Closed in a Day
- Nov 2, 2026TJ Digital: 23% of AI-cited pages open with a direct answer, versus 14% of uncited ones
Key Questions Answered
Where the simple approach breaks?
The problems show up not in the interface but in the behavior of providers and the models themselves: Unstable free models — listed as free, but they respond erratically and drop out during provider downtime Models disappear — it was in the listing yesterday; today the provider removed it or closed it to new users Quality drops — technically alive, but good only for demos or simple tasks Frontend and backend mismatch — the list in the interface is a day or two stale, while the backend knows a…
What are the key details on A strict engineering loop instead of a catalog?
The solution relies not on an endless list but on control at the backend: Step 1: list cleanup. The backend gets the raw list of models from the provider and filters it: it keeps only suitable free options, discards unstable ones, and removes duplicates. You can add health checks, which periodically ping each model to see whether it is alive. Step 2: one model per brand. Even if OpenAI has 5 free models in its listing, only one goes to the frontend: the most stable.
What this means?
Choosing an LLM stops being a UI task and becomes an engineering task, with data cleanup, health checks, fallback logic, and honest tracking. For the product, that means reliability and fewer support questions. For the user, the choice works, answers arrive, and the interface does not lie.
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.