How BERTopic and a Local LLM Help Rostelecom Analyze Massive Text Collections
An NLP developer at Rostelecom has presented a BERTopic pipeline that fully automates the analysis of large text collections: reviews, support tickets, comments and social media posts. The key improvement is a built-in local language model that generates interpretable topic names without sending data to the cloud, which keeps the data confidential. In practice, the method cuts manual work from several weeks to a few hours.
AI-processed from Habr AI; edited by Hamidun News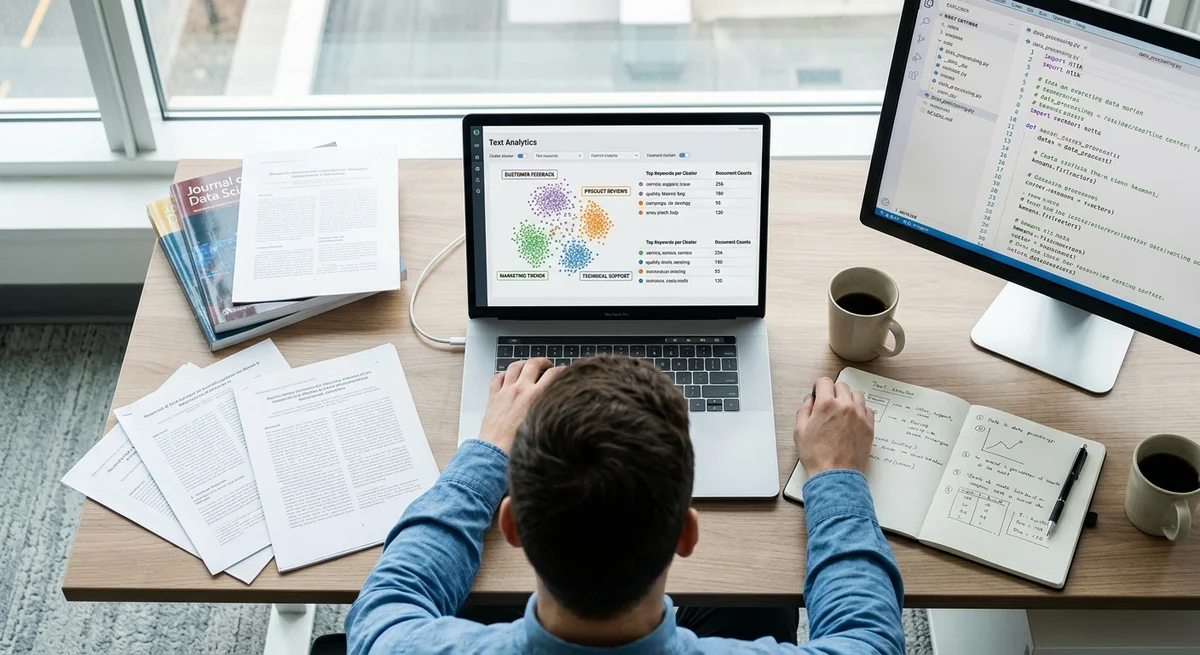
Automating text analysis is one of the most labor-intensive and underrated tasks in NLP. When a company receives tens of thousands of reviews, support tickets or comments a day, manual categorization is not just impossible but pointless from an ROI standpoint. Anton, an NLP engineer at Rostelecom, has proposed a solution: a pipeline built on BERTopic with an integrated local LLM that produces interpretable topic names.
Why automate text analysis
Large text collections are a gold mine of unstructured data for any company. Reviews contain complaints about specific bugs and shortcomings, support tickets reveal systemic problems and weak spots, and social media comments hold ideas for new features and products. But even a small team of analysts cannot sort through all of it by hand in a day or a week.
The classic approach is to read every text manually, grasp its meaning and assign it to a category. At volumes of 10,000 texts or more, this is economically unviable, grueling for the specialist and slow. Subjectivity adds to the problem: one analyst files a complaint under "network problems", another under "service quality", a third under "other". Consistency is lost and the conclusions become unreliable.
How BERTopic solves the clustering problem
BERTopic is a framework that combines several machine learning techniques to find topics in texts automatically. The process works like this:
- Embeddings (BERT): each text is converted into a vector of numbers (an embedding), so that semantically similar texts sit close together in a multidimensional space. For Russian text, you can use ruBERT or other models.
- Clustering (HDBSCAN): a fast algorithm finds natural groupings of texts in this space without requiring you to know the number of topics in advance.
- Interpretation: BERTopic generates a name for each cluster based on TF-IDF, the most significant words in the group.
The result? From the chaos of 50,000 texts you get, for example, 15 clear, natural topics: "internet problems", "billing questions", "mobile app bugs", "benefit requests" and so on.
There is a catch, though. The standard BERTopic interpretation often produces odd names like "абонент_услуга_номер" or "бага_баг_ошибка" (roughly "subscriber_service_number" and "glitch_bug_error"), which are hard to explain to the business. This is where a language model comes in.
Embedding a local LLM for interpretation
Instead of mechanically picking words from the cluster, a local language model (for example, Mistral 7B or Llama 2) reads the cluster's top words and top documents, then generates a full description in Russian: "Customers complain about slow internet speeds in rural areas, especially on weekends".
"Embedding a local LLM protects data confidentiality: all current data stays inside the company, with nothing sent to OpenAI, the Claude API or other cloud services.
This is critical for companies that work with sensitive information," Anton emphasizes.
A local model also runs faster than API requests and is completely independent of quotas, limits and per-token processing costs. The pipeline works without internet access, which lowers latency and makes the system more reliable.
Practical results and scaling
Rostelecom's pipeline can do in a few hours what used to take several weeks of manual work:
1. Load a set of texts into BERTopic (thousands or tens of thousands of records) 2. Get ready-made clusters with LLM-generated topic descriptions in language the business understands 3. Export the results to Excel, CSV or a database for further work by analysts and product managers
The pipeline is also reusable: a new batch has arrived in support? The pipeline retrains in minutes and again returns a structured result.
What this means for the NLP industry
NLP tools are moving out of the lab and academic papers into real production. When one engineer can assemble in a day a full-featured pipeline that used to require two to three weeks of manual work and the expertise of an entire team, NLP becomes a practical tool rather than a scientific experiment available only to large IT companies.
- Nov 1, 2026Local models lose to Opus and Codex: 0.21 on a MacBook versus 1.00 for Codex
- Nov 1, 2026Kimi scores 96.2% on a 1C database analytics test and emerges as a fallback if Claude access is blocked
- Nov 1, 2026OpenAI Rewrites GPT Behavior Rules: Five Values and a Chain of Command
- Nov 1, 2026Google admits AI Mode cuts search revenue, shares fall 15%
Key Questions Answered
Why automate text analysis?
Large text collections are a gold mine of unstructured data for any company. Reviews contain complaints about specific bugs and shortcomings, support tickets reveal systemic problems and weak spots, and social media comments hold ideas for new features and products. But even a small team of analysts cannot sort through all of it by hand in a day or a week. The classic approach is to read every text manually, grasp its meaning and assign it to a category. At volumes of 10,000 texts or more, this is economically unviable, grueling for the specialist and slow. Subjectivity add
How BERTopic solves the clustering problem?
BERTopic is a framework that combines several machine learning techniques to find topics in texts automatically. The process works like this: Embeddings (BERT): each text is converted into a vector of numbers (an embedding), so that semantically similar texts sit close together in a multidimensional space. For Russian text, you can use ruBERT or other models. Clustering (HDBSCAN): a fast algorithm finds natural groupings of texts in this space without requiring you to know the number of topics in advance. Interpretation: BERTopic generates a name for each cluster based on T
What are the key details on Embedding a local LLM for interpretation?
Instead of mechanically picking words from the cluster, a local language model (for example, Mistral 7B or Llama 2) reads the cluster's top words and top documents, then generates a full description in Russian: "Customers complain about slow internet speeds in rural areas, especially on weekends". "Embedding a local LLM protects data confidentiality: all current data stays inside the company, with nothing sent to OpenAI, the Claude API or other cloud services. This is critical for companies that work with sensitive information," Anton emphasizes. A local model also runs fas
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.