Thinking Machines Is Building an AI That Talks and Listens at the Same Time
Thinking Machines is working on an AI that listens and responds at the same time, as in a phone conversation. Conventional models work sequentially: they first process the full input, then generate the full response. The new architecture allows real-time reactivity, natural interruptions and barge-ins, as in a dialogue between people.
AI-processed from TechCrunch; edited by Hamidun News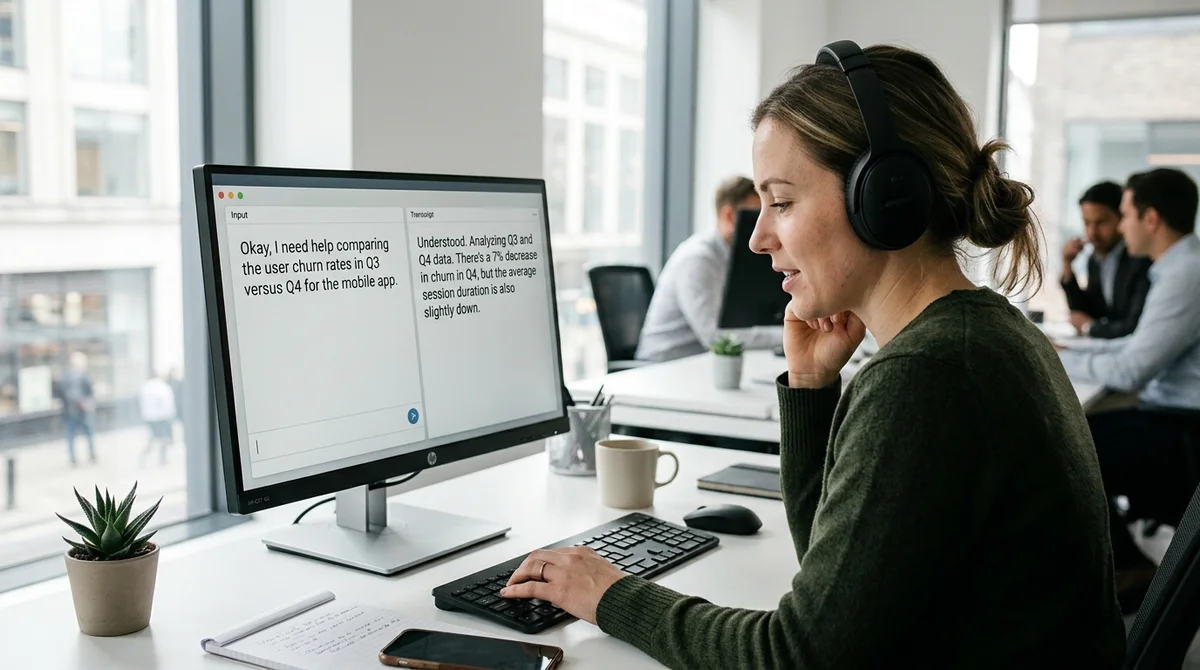
Every AI model today works on the same principle: you write, the model listens. You wait, the model answers. Thinking Machines is trying to change that with an architecture that processes your message and generates a response at the same time, like an ordinary phone call.
The problem with the current approach
All modern language models, from ChatGPT to Claude, work on a request-response basis. You send a complete message, the model processes it in full, then returns a complete answer. This makes it feel like you are talking to a robot, not a person.
Real conversation is different. People listen while they are forming a reply. You can interrupt the other person, clarify a detail, add context, and they react on the fly without starting over. Nobody waits for the other person to finish an entire speech before rethinking their answer from scratch. This creates a natural, organic flow of dialogue.
The current AI approach sets a rigid boundary: input complete → processing → output complete. There is no flexibility, no adaptation along the way, no sense of two-way communication.
What Thinking Machines is doing
The startup is developing a model that processes an input stream in real time and generates an output stream at the same time. Instead of waiting for the full input, the system starts answering while it is still receiving information from the user. This opens up several fundamentally new capabilities:
- Listening while responding: reacting to new data without reloading the context
- Natural interruptions: barging in, as in a live conversation between people
- Intonation adaptation: changing tone in real time based on vocal cues
- Nonverbal signals: taking gestures and facial expressions into account in video calls
- Minimal latency: no dead pauses between turns
For voice assistants this is critical. When you call a call center or order a taxi by voice, you do not want to wait 3–5 seconds for processing. You speak, and the assistant hears you and answers immediately, like a person.
The architectural difficulty
Processing input and generating output simultaneously requires a deep architectural overhaul. Transformers, which almost all modern LLMs are built on, are designed to work sequentially: read the entire context, then produce tokens one by one. Changing this core principle means rewriting the mechanics of attention, caching and prediction. The model has to maintain a growing context from the input stream while generating output, without losing the coherence and logic of its answer.
The practical challenges are just as serious: answer quality (do responses become hasty and incomplete?), latency (minimal delay is needed to feel natural), and memory management for growing streams. How do you keep the thread of the conversation when the response runs in parallel with the input? How do you avoid missing a detail from the end of a message if you have already started answering the beginning?
What this means
If this approach can be made to work, talking to an AI will stop feeling like interacting with a system. It will be a dialogue, a real conversation, without the stiffness and delay, closer to human communication.
For voice assistants, chatbots and especially call centers, this would be a critical improvement. A customer calls, and the assistant hears and reacts immediately; it can interrupt to ask for clarification and adapt its answer based on new information. This would raise satisfaction and speed up problem resolution several times over.
- Nov 2, 2026NC State's AICG Framework Cuts MAE by 50.3% on Math Answer Grading
- Nov 2, 2026We Audited 929 Automations at Alpina: What Corporate AI Training Should Look Like in 2026
- Nov 2, 2026I Interrogated 6 AI Models About Myself Through a Procurement Manager's Eyes: Amazon, Esoterica, 'Telo Hudelo' and 5 Holes We Closed in a Day
- Nov 2, 2026TJ Digital: 23% of AI-cited pages open with a direct answer, versus 14% of uncited ones
Key Questions Answered
What are the key details on The problem with the current approach?
All modern language models, from ChatGPT to Claude, work on a request-response basis. You send a complete message, the model processes it in full, then returns a complete answer. This makes it feel like you are talking to a robot, not a person. Real conversation is different. People listen while they are forming a reply. You can interrupt the other person, clarify a detail, add context, and they react on the fly without starting over.
What Thinking Machines is doing?
The startup is developing a model that processes an input stream in real time and generates an output stream at the same time. Instead of waiting for the full input, the system starts answering while it is still receiving information from the user.
What are the key details on The architectural difficulty?
Processing input and generating output simultaneously requires a deep architectural overhaul. Transformers, which almost all modern LLMs are built on, are designed to work sequentially: read the entire context, then produce tokens one by one. Changing this core principle means rewriting the mechanics of attention, caching and prediction. The model has to maintain a growing context from the input stream while generating output, without losing the coherence and logic of its answer.
Ship AI Faster with Founders, Engineers & Weekly Architecture Reviews
Inside Vibe Club (hamidun.com/club) — weekly live masterminds with Zhemal Khamidun, Tech Radar, full LMS access, and 370+ production Claude Code skills.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.