OpenAI explains what data ChatGPT trains on and how it protects privacy
OpenAI has laid out in detail how ChatGPT uses data for training and what privacy controls users have. The company says it uses Privacy Filter to mask personal information, and that users can turn off the use of new conversations for improving models in settings. For a more closed-off mode, there is Temporary Chat: these conversations do not appear in history, do not create memory and are deleted after 30 days.
AI-processed from OpenAI Blog; edited by Hamidun News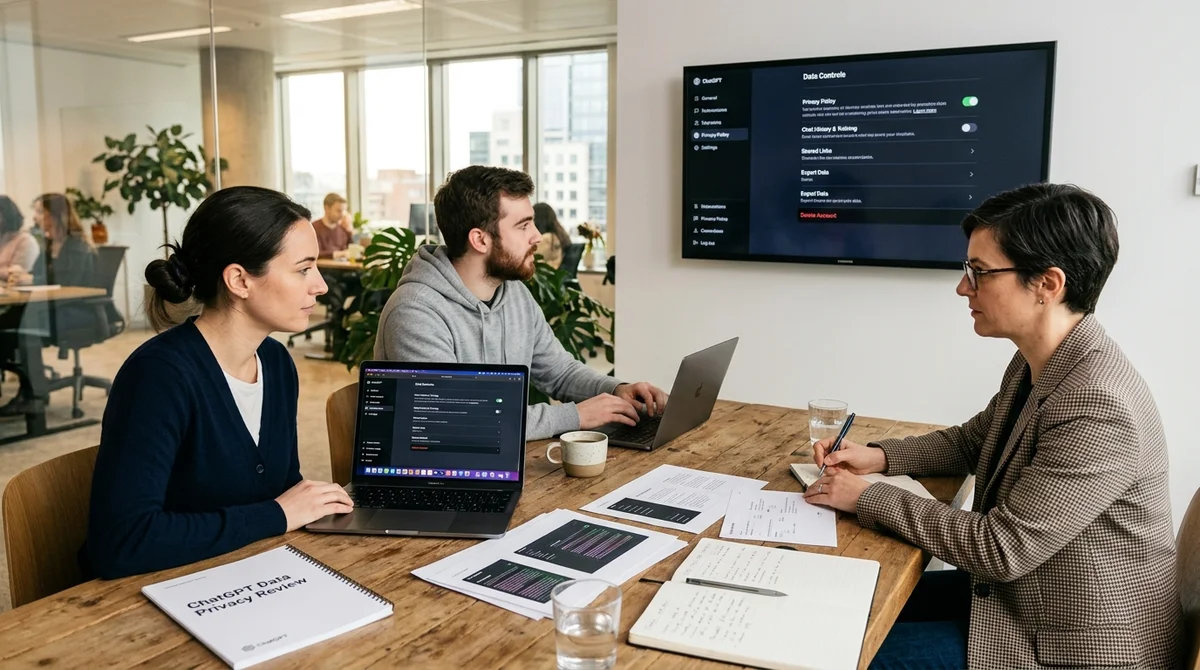
On May 6, OpenAI published a detailed explanation of how ChatGPT acquires knowledge about the world while trying not to pull unnecessary personal data into training. The company described the data sources, its internal filters and the settings users can use to limit how their own conversations are used.
Where the data comes from
In the post, OpenAI divides data sources into several categories. To train the models behind ChatGPT, the company uses publicly available information from the internet, data from partnerships, and material provided or generated by users, contractors and researchers. The idea is for the model to learn general patterns, facts and connections between topics, rather than memorize individual personal stories. According to OpenAI, it is this broad set of sources that helps make answers more useful, stable and safe.
The company also clarifies an important detail: for content from the open internet, only material that is freely and openly accessible is used for training. OpenAI gives public posts, blogs and discussions on open forums as examples. This does not settle questions about the limits of acceptable use of open data, but it shows the company is trying to formalize a rule: not everything on the web is automatically considered suitable for training if access to that content is restricted.
How personal information is removed
Before data enters training, OpenAI runs it through a set of safeguards meant to reduce the amount of personal information in datasets. The main one is Privacy Filter, a tool for finding and masking personal details in text. According to the company, the filter is applied at several stages of the process, including to public datasets and to user conversations when the person has the Improve the model for everyone setting turned on. OpenAI also says it has made Privacy Filter free for other developers, so the approach can be used outside ChatGPT.
A separate layer of protection concerns not training but ChatGPT's answers themselves. The service is supposed to refuse requests for private or sensitive information about specific people, although OpenAI openly acknowledges that mistakes are still possible. If personal information does appear in an answer and the person considers it inaccurate or inappropriate, they can submit a request through the privacy portal. The company also stresses that privacy and responding to serious risks, such as credible threats of violence, must work at the same time rather than get in each other's way.
"Protecting privacy is a central part of how we build
ChatGPT."
Which settings are available
The most practical part of the material is the list of user toggles that let people decide how much data to give the system. OpenAI emphasizes that control over conversations is not buried deep in documentation but placed right in the ChatGPT interface. In other words, this is not only about company principles but about quite practical actions: you can turn off the use of new chats in training, remove memory, or switch to a separate temporary mode for more sensitive requests.
- In Settings -> Data Controls you can turn off the Improve the model for everyone option. After that, new chats will stay in your history but will not be used to train models.
- Temporary Chat mode starts a one-off conversation: it is not saved in history, does not create memory and is not used to improve models.
- Temporary chats are kept for 30 days for safety purposes and then deleted.
- The Memory feature can be viewed, edited, cleared or turned off entirely if you do not want ChatGPT to remember past details.
- Users can also export their data, delete their account and submit a request through the privacy portal.
There is also a direct warning: users should not send ChatGPT sensitive information they would not be willing to share even in the context of review or processing by the system. This is an important caveat, because many people treat a chat interface as a private notebook or a safe interlocutor by default. OpenAI, by contrast, is trying to convey a more sober model of use: users have control tools, but responsibility for what exactly they enter into the service does not go away.
What this means
OpenAI is effectively trying to move the privacy conversation from general promises to a set of concrete rules and toggles. For users this is useful: it is clearer which data may take part in training, how to turn that off, and how a regular chat differs from Temporary Chat. For the market it is a signal that trust in AI products depends more and more not only on model quality but also on transparency in handling personal information.
- Nov 1, 2026Local models lose to Opus and Codex: 0.21 on a MacBook versus 1.00 for Codex
- Nov 1, 2026Kimi scores 96.2% on a 1C database analytics test and emerges as a fallback if Claude access is blocked
- Nov 1, 2026OpenAI Rewrites GPT Behavior Rules: Five Values and a Chain of Command
- Nov 1, 2026Google admits AI Mode cuts search revenue, shares fall 15%
Key Questions Answered
Where the data comes from?
In the post, OpenAI divides data sources into several categories. To train the models behind ChatGPT, the company uses publicly available information from the internet, data from partnerships, and material provided or generated by users, contractors and researchers. The idea is for the model to learn general patterns, facts and connections between topics, rather than memorize individual personal stories. According to OpenAI, it is this broad set of sources that helps make answers more useful, stable and safe. The company also clarifies an important detail: for content from
How personal information is removed?
Before data enters training, OpenAI runs it through a set of safeguards meant to reduce the amount of personal information in datasets. The main one is Privacy Filter, a tool for finding and masking personal details in text. According to the company, the filter is applied at several stages of the process, including to public datasets and to user conversations when the person has the Improve the model for everyone setting turned on. OpenAI also says it has made Privacy Filter free for other developers, so the approach can be used outside ChatGPT. A separate layer of protecti
Which settings are available?
The most practical part of the material is the list of user toggles that let people decide how much data to give the system. OpenAI emphasizes that control over conversations is not buried deep in documentation but placed right in the ChatGPT interface. In other words, this is not only about company principles but about quite practical actions: you can turn off the use of new chats in training, remove memory, or switch to a separate temporary mode for more sensitive requests. In Settings -> Data Controls you can turn off the Improve the model for everyone option. After that
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.