In 2026, AI startups are moving from single prompts to multi-agent pipelines
A good prompt and a polished UI no longer add up to a full AI product. In 2026, startups that need consistent results for users and businesses are moving to multi-agent pipelines: one agent gathers data, another generates, a third checks, and an orchestrator pulls everything into a final result. This architecture is what is beginning to separate a demo from a service that actually works.
AI-processed from Habr AI; edited by Hamidun News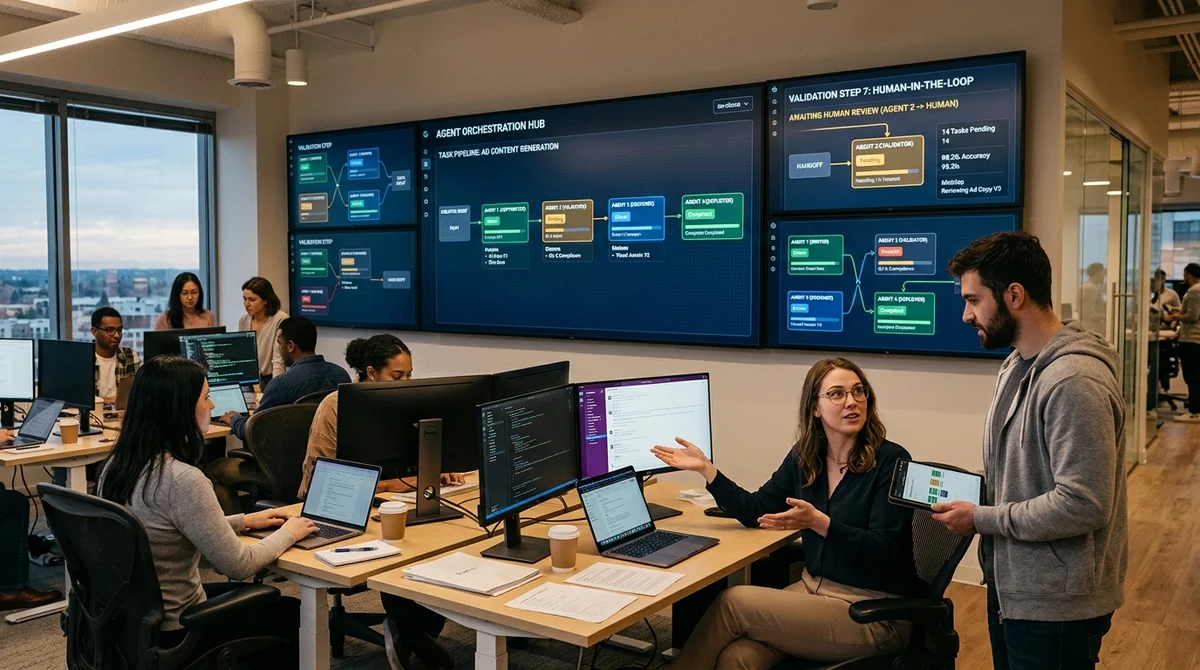
The AI services market in 2026 keeps running into an uncomfortable truth: a nice interface wrapped around one lucky prompt rarely makes a durable product. Teams that want to get AI to a working result are moving away from the "magic query" and building multi-agent pipelines, where different models and checks handle separate stages of a task.
Why one prompt is not enough
The logic of "take a powerful model, write a good system prompt and wrap it in a subscription" worked in the early market, but it quickly hit a ceiling. A single request can write a text, produce an idea or assemble a draft, but it holds long context poorly, cannot reliably check itself and breaks easily when user input is slightly more complex than expected. As a result, the product looks impressive in a demo but starts to fall apart in real scenarios that call for memory, task routing and quality control.
The problem is especially visible where products promise to automate a business process but in practice deliver a chat with one button. As long as the user asks a typical question, everything looks convincing. But once the system has to combine several sources, hold a format, verify figures and return a predictable answer, it starts producing different results from the same input. For B2B and team work this is close to a death sentence: such a tool is hard to build into an operational workflow.
What a pipeline looks like
The new approach is built not around a single model but around a chain of roles. One agent receives the task and clarifies the input data, a second looks for facts or documents, a third writes a draft, a fourth checks the logic, format and constraints, and an orchestrator assembles the result and decides whether the task needs another pass. Such a pipeline is noticeably harder to build, but it is closer to how strong teams work: not one universal performer, but several specializations with clear areas of responsibility.
A multi-agent pipeline is needed not for the sake of a buzzword, but for controllability. When each step is isolated, a team can improve the weak spot precisely: swap the model only for research, add validation rules only in the final review, keep memory only where it genuinely helps. This lowers the cost of errors and makes product development more engineering-driven and less intuitive. The team sees exactly where the output breaks and can fix that part without rewriting the whole system.
"One prompt is not a product."
What changes for startups
A multi-agent setup costs more to develop, but it delivers what most AI wrappers lack: repeatable results. Instead of hoping for a lucky generation, the team starts designing a process: where to validate data, how to catch hallucinations, how to reuse context, and when to ask a human for confirmation. This is where product value appears that is hard to copy in an evening. It turns AI from an answer generator into a managed service with clear SLAs.
- Breaking a task into stages instead of a single request
- Separate agents for search, generation and checking
- Escalation rules if the model is not confident in its answer
- Storage of intermediate context and decision history
- Quality metrics for every step, not only for the final answer
This approach also changes the economics of the product. Yes, a pipeline can cost more in tokens and infrastructure, but it reduces the price of errors: fewer manual redos, fewer refunds, less distrust from the customer. If a service promises a result rather than just "help with generation", stability starts to pay for the extra costs at an early stage of growth.
For the market, this is an important shift. The winners will not be those who first bolted an LLM onto an input form, but those who built a reliable architecture around the model. In 2026, the competitive advantage is not access to an API itself, but the ability to organize agents, tools and data into a single workflow without unnecessary magic.
What this means
The period when an AI product could be passed off as "one strong prompt plus a nice UI" is ending. If a team wants to sell not a demo but a stable service, it will have to think like an engineering system: break the task down, check the steps and build orchestration between agents.
- Nov 2, 2026Karpathy builds a YouTube clone with 6454 videos from Hacker News recommendations in two hours
- Nov 2, 2026Karpathy used Claude to build HackerTube from 6,454 videos recommended on Hacker News
- Nov 2, 2026Arca gives AI agents finance tasks lasting up to 10 days, but leaves the trades to humans
- Nov 2, 2026DeepSeek open-sources Super-agent prototype: p95 task completion time of 15.7 minutes vs. 29.5
Key Questions Answered
Why one prompt is not enough?
The logic of "take a powerful model, write a good system prompt and wrap it in a subscription" worked in the early market, but it quickly hit a ceiling. A single request can write a text, produce an idea or assemble a draft, but it holds long context poorly, cannot reliably check itself and breaks easily when user input is slightly more complex than expected. As a result, the product looks impressive in a demo but starts to fall apart in real scenarios that call for memory, task routing and quality control. The problem is especially visible where products promise to automat
What a pipeline looks like?
The new approach is built not around a single model but around a chain of roles. One agent receives the task and clarifies the input data, a second looks for facts or documents, a third writes a draft, a fourth checks the logic, format and constraints, and an orchestrator assembles the result and decides whether the task needs another pass. Such a pipeline is noticeably harder to build, but it is closer to how strong teams work: not one universal performer, but several specializations with clear areas of responsibility. A multi-agent pipeline is needed not for the sake of a
What changes for startups?
A multi-agent setup costs more to develop, but it delivers what most AI wrappers lack: repeatable results. Instead of hoping for a lucky generation, the team starts designing a process: where to validate data, how to catch hallucinations, how to reuse context, and when to ask a human for confirmation. This is where product value appears that is hard to copy in an evening. It turns AI from an answer generator into a managed service with clear SLAs. Breaking a task into stages instead of a single request Separate agents for search, generation and checking Escalation rules if
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.