An open-source stack of 6 models and 9 agents shows how to build an AI team on a single server
One GPU server, six open-source models and nine agents: that is the setup for an autonomous AI team that designs, writes, tests and deploys new agents by itself. Instead of one general-purpose model, roles are split by strengths: reasoning for the orchestrator, code generation for the builder, tool use for the critic. The key saving is instance sharing: 9 agents run on just 3–4 models. The author also describes three deployment options, from a single RTX 4090 to an A100 cluster.
AI-processed from Habr AI; edited by Hamidun News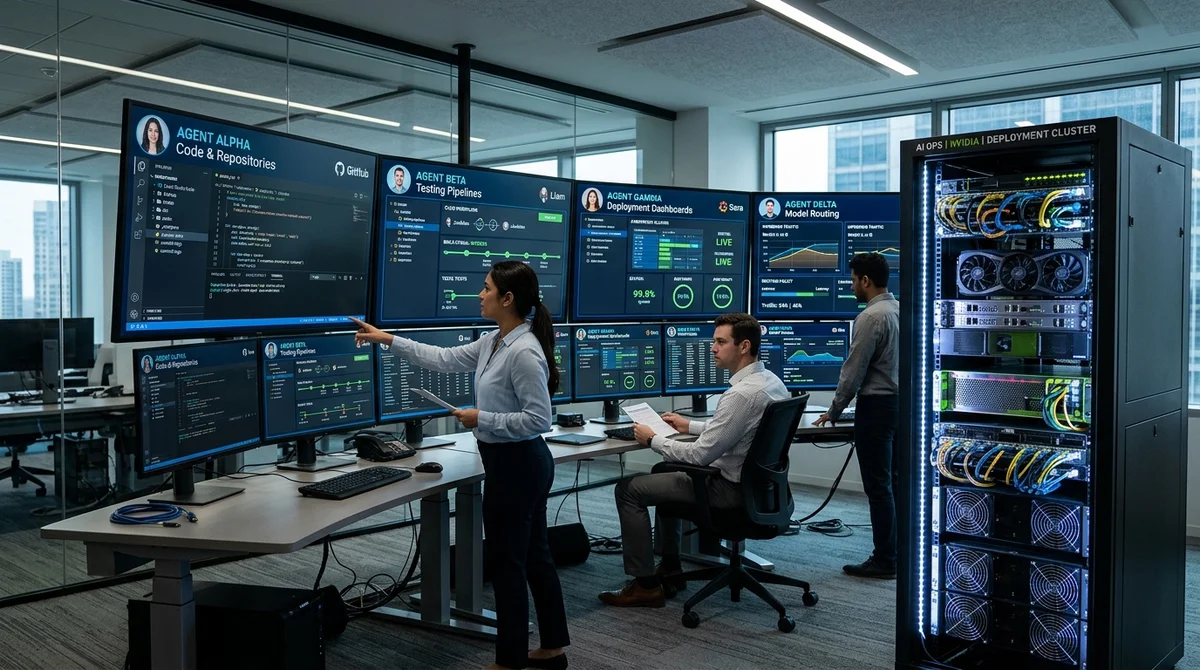
An autonomous team of nine AI agents can design, write, test and deploy new agents without human involvement. It does not need a set of closed APIs: the setup is built on six open-source models and, in its base configuration, fits on a single GPU server.
How the team is organized
Instead of one "universal" model, the author built a pipeline of nine roles. Some agents handle task definition and architecture; others handle writing code, quality checks, testing and release. The result is not one big assistant but a small engineering organization in which each member does a narrow slice of the work.
This approach cuts down on chaos: an agent does not have to plan the system, write modules, run tests and assess its own mistakes all at once. The key idea is that autonomy comes not from magic but from splitting the process into stages. If an agent understands only its own section and receives an already structured task as input, the requirements for the model become clearer. The orchestrator must be able to reason and hold context, the builder must generate code reliably, and the critic must spot problems in tool use and execution scenarios. So the gain comes not from one super-model but from precisely assembling roles into a working pipeline.
Roles and benchmarks
The author explicitly rejects the idea of a "best model overall." Instead, roles are matched to what benchmarks show. For the orchestrator, reasoning matters, so the reference point is a GPQA score of 88.4%. For the builder, code generation is critical, and the benchmark is HumanEval at 92.7%. For the critic, understanding tool use and agent behavior in tasks matters more, so tau-bench, with a result of 87.4%, is used. This specialization is why six different open-source models are used instead of a single GPT-class model for every case.
- Orchestrator: strong reasoning, prioritization and task decomposition
- Builder: code generation and fast passes over engineering changes
- Critic: checking tool use, solution quality and weak points in the pipeline
- Other roles: tests, deployment and service stages, where shared instances can be reused
Nine agents do not mean nine full models in memory at once. One practical trick is instance sharing: several roles share the same model if their workloads and task profiles are similar. As a result, a nine-agent system can run on just three or four model instances. This sharply reduces VRAM use, simplifies maintenance and brings the architecture closer to real production rather than a demo with an unlimited budget.
Hardware and launch
The infrastructure side is interesting in its own right. The author describes three deployment configurations, from a single RTX 4090 with 24 GB of memory to an A100 cluster with a combined 211 GB. Between these extremes, you can choose a balance of speed, quality and parallelism. To cut costs, the setup uses quantization, a well-designed inference stack and an interactive dashboard that helps track roles, load and task progress. In other words, this is not only about picking models but also about a proper operating environment for them.
The practical takeaway is simple: open-source agentic work is no longer a lab toy. Where such setups were once associated with either expensive APIs or heavy clusters, this one shows a more down-to-earth way to start. A small team can begin with one server, test whether the pipeline is viable, and then scale it as workloads grow. The price now looks like an engineering choice rather than a barrier that immediately rules out most teams.
What this means
The market is moving from the idea of one "magic" model toward role-oriented systems, where the right composition matters more than a loud name in an API. For business, this is a signal: autonomous AI teams can be assembled from open-source components right now, provided they are treated as infrastructure and process rather than as a single chat window.
- Nov 2, 2026DeepSeek open-sources Super-agent prototype: p95 task completion time of 15.7 minutes vs. 29.5
- Nov 2, 2026Bun creator uses Claude Code to port 750K lines from Zig to Rust in 11 days
- Nov 2, 2026Microsoft releases 4B model Mage-VL-Cowork, which solves 66.0% of OSWorld-Verified tasks
- Nov 2, 2026Meta's Muse assistant keeps dossiers on loved ones and gets root on Ubuntu by default
Key Questions Answered
How the team is organized?
Instead of one "universal" model, the author built a pipeline of nine roles. Some agents handle task definition and architecture; others handle writing code, quality checks, testing and release. The result is not one big assistant but a small engineering organization in which each member does a narrow slice of the work. This approach cuts down on chaos: an agent does not have to plan the system, write modules, run tests and assess its own mistakes all at once. The key idea is that autonomy comes not from magic but from splitting the process into stages. If an agent understa
What are the key details on Roles and benchmarks?
The author explicitly rejects the idea of a "best model overall." Instead, roles are matched to what benchmarks show. For the orchestrator, reasoning matters, so the reference point is a GPQA score of 88.4%. For the builder, code generation is critical, and the benchmark is HumanEval at 92.7%. For the critic, understanding tool use and agent behavior in tasks matters more, so tau-bench, with a result of 87.4%, is used. This specialization is why six different open-source models are used instead of a single GPT-class model for every case. Orchestrator: strong reasoning, prio
What are the key details on Hardware and launch?
The infrastructure side is interesting in its own right. The author describes three deployment configurations, from a single RTX 4090 with 24 GB of memory to an A100 cluster with a combined 211 GB. Between these extremes, you can choose a balance of speed, quality and parallelism. To cut costs, the setup uses quantization, a well-designed inference stack and an interactive dashboard that helps track roles, load and task progress. In other words, this is not only about picking models but also about a proper operating environment for them. The practical takeaway is simple: op
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.