AWS shows how to build an AI engine for A/B testing on Amazon Bedrock and DynamoDB
AWS has published a hands-on walkthrough of an AI engine for A/B testing built on Amazon Bedrock, ECS, DynamoDB, and MCP. Instead of assigning variants at random, the system takes user context into account while the experiment is running. This approach can speed up the search for winning hypotheses, get more value out of traffic, and push testing closer to personalization. The trade-off is that it requires careful logging and tight control over the statistics.
AI-processed from AWS Machine Learning Blog; edited by Hamidun News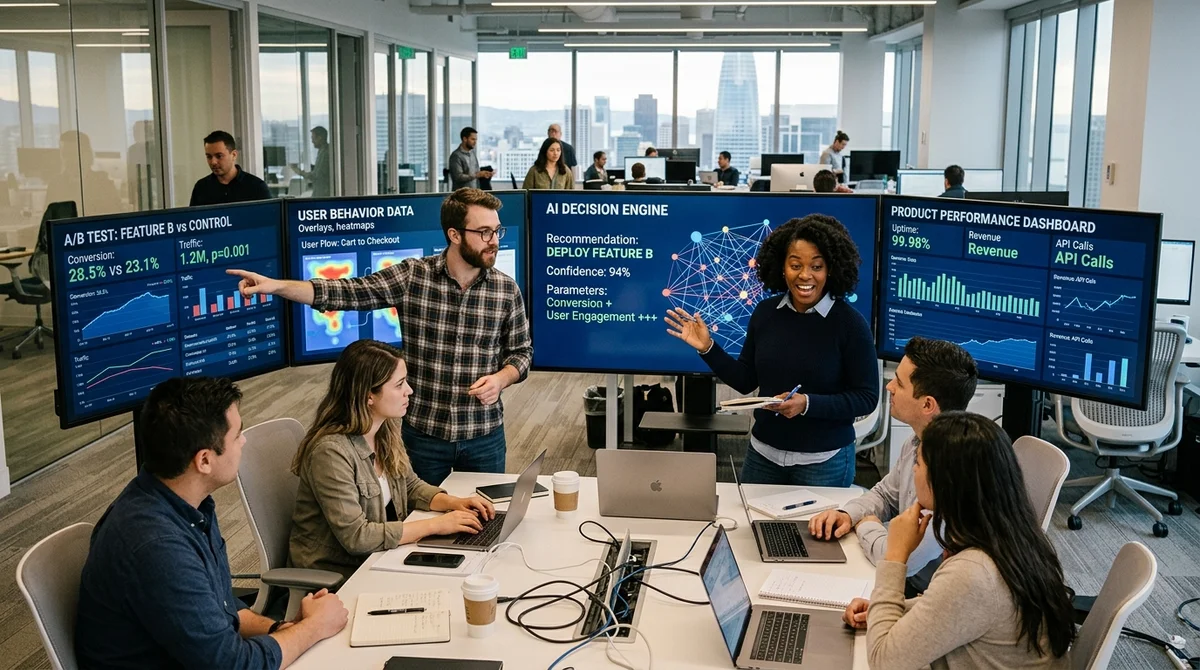
AWS has shown how to turn a standard A/B test into a context-aware AI mechanism. Instead of distributing variants at random, a system built on Amazon Bedrock analyzes signals about the user and helps decide which variant to show at the moment of the experiment.
How the A/B test changes
A traditional A/B test usually splits the audience at random and then compares conversions. The AWS approach keeps the core idea of an experiment but adds a decision-making layer at the point where a variant is served. The model receives context: what the user is doing, where they came from, which device they're on, how the current session is going, and which variants are actually available within the test. Based on that, the system can pick a variant more precisely than a simple 50/50 split.
This brings the test closer to how a product really behaves, where the same screen performs differently for new and returning users, mobile and desktop traffic, and high-value and low-value segments. The more useful signals the system sees, the faster it finds winning combinations and the fewer impressions it wastes on a clearly weaker variant. For growth teams, this is no longer just post-launch analytics — it's an attempt to influence the outcome while the experiment is still running.
How the architecture works
AWS proposes building the engine from four core components. Amazon Bedrock handles the LLM logic; Amazon ECS runs the container service that receives requests from the application; Amazon DynamoDB stores experiment state and results; and the Model Context Protocol acts as the layer that passes tools and structured context to the model. The point isn't to bolt a chat model onto your tests, but to give it controlled access to data, rules, and decision history.
- Amazon Bedrock — analyzes context and proposes which variant to show
- Amazon ECS — runs the orchestration service and the experiments API
- Amazon DynamoDB — stores configurations, assignments, and metrics
- MCP — describes the available models, data, and actions
- Application — sends user context and receives the decision
In a typical flow, the application sends the service an experiment ID, session parameters, business rules, explicit constraints, and the list of available variants. The ECS service gathers the relevant signals, passes them to the model via Bedrock, and gets back an assignment decision. The choice and its downstream results are then recorded in DynamoDB so the team can verify exactly how the system made its decision and keep the experiment reproducible for later analysis.
Benefits and risks
The main payoff of this approach isn't just personalization, but smarter use of traffic during the test. If one variant performs better for a specific segment, the system can act on that sooner than a classic setup with strict randomization. That's especially valuable wherever each impression is expensive: e-commerce, subscriptions, ad landing pages, SaaS onboarding, and any product with a small volume of high-quality traffic, where mistakes are especially costly.
But this design comes at a price. The more actively the model intervenes in traffic allocation, the harder it becomes to keep the experiment statistically clean and to explain why a given user saw a particular variant. In practice, an engine like this requires strict logging rules, clear limits on which signals can be used, and separate oversight of the balance between exploration and exploitation. Otherwise, a company ends up with a slick AI layer but loses trust in the results of the test itself.
What it means
The AWS post signals a shift from "AI as a text generator" to AI as a layer for product decision-making. For growth teams, it's a sign that A/B tests are gradually turning from passive analytics into a managed system in which the model helps allocate traffic rather than just tallying results after the fact.
- Oct 31, 2026Worldwide Express hands disputed invoices to AI agents and cuts unresolved disputes by 75%
- Oct 30, 2026AWS gives coding agents a live site preview straight from an isolated session
- Oct 30, 2026MoEngage Opens 400 Private APIs to AI Agents Through AgentCore Gateway, Without Building Its Own MCP Servers
- Oct 29, 2026NVIDIA Nemotron 3.5 Super VL: 120B Parameters, 12B Active, Running on AWS
Key Questions Answered
How the A/B test changes?
A traditional A/B test usually splits the audience at random and then compares conversions. The AWS approach keeps the core idea of an experiment but adds a decision-making layer at the point where a variant is served. The model receives context: what the user is doing, where they came from, which device they're on, how the current session is going, and which variants are actually available within the test. Based on that, the system can pick a variant more precisely than a simple 50/50 split. This brings the test closer to how a product really behaves, where the same screen
How the architecture works?
AWS proposes building the engine from four core components. Amazon Bedrock handles the LLM logic; Amazon ECS runs the container service that receives requests from the application; Amazon DynamoDB stores experiment state and results; and the Model Context Protocol acts as the layer that passes tools and structured context to the model. The point isn't to bolt a chat model onto your tests, but to give it controlled access to data, rules, and decision history. Amazon Bedrock — analyzes context and proposes which variant to show Amazon ECS — runs the orchestration service and
What are the key details on Benefits and risks?
The main payoff of this approach isn't just personalization, but smarter use of traffic during the test. If one variant performs better for a specific segment, the system can act on that sooner than a classic setup with strict randomization. That's especially valuable wherever each impression is expensive: e-commerce, subscriptions, ad landing pages, SaaS onboarding, and any product with a small volume of high-quality traffic, where mistakes are especially costly. But this design comes at a price. The more actively the model intervenes in traffic allocation, the harder it b
Delegate Deep Research, Coding & Multi-Step Workflows to Nomad Agent
Deploy autonomous task execution with Nomad Agent (agent.nomadnet.ai) — automated web research, data synthesis, code generation, and MCP tool orchestration.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.