Machine Learning Mastery names five main barriers to scaling agentic AI in 2026
Machine Learning Mastery has published a breakdown of why agentic AI is still hard to scale in production in 2026. The main bottlenecks are exploding orchestration complexity, weak observability, unpredictable costs, immature testing methods and lagging safeguards. Without these layers, autonomy quickly turns into a source of failures, risks and budget overruns, especially for businesses with real users and SLAs.
AI-processed from Machine Learning Mastery; edited by Hamidun News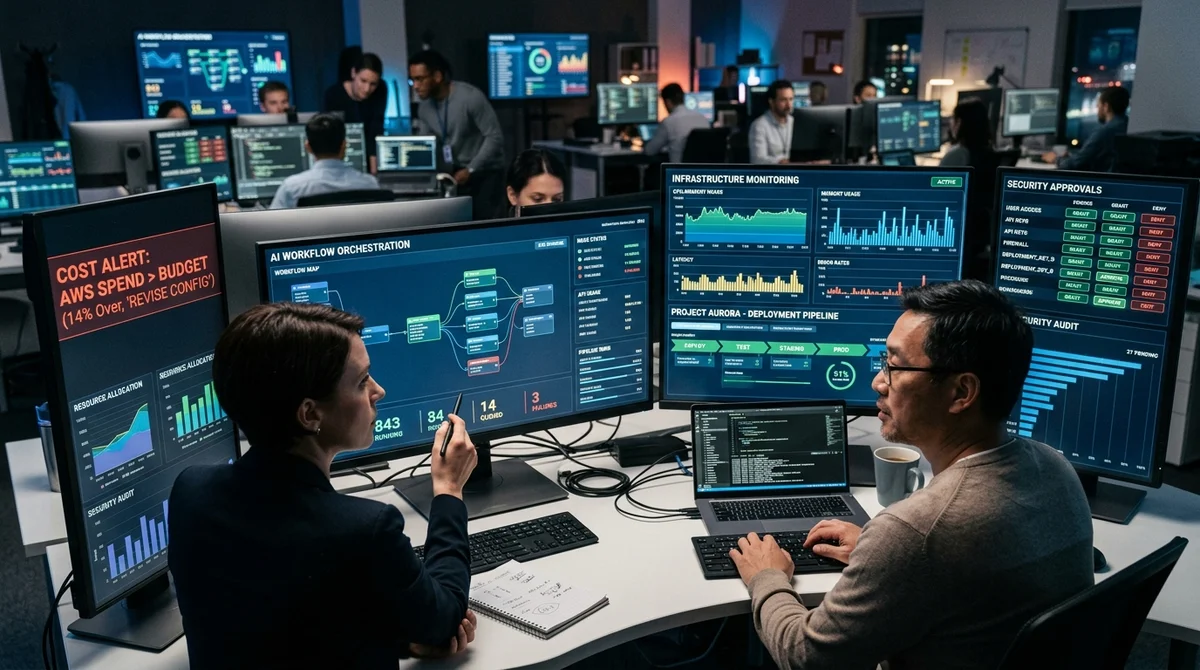
Machine Learning Mastery has published a piece on five problems that slow the mass adoption of agentic AI in production. Its central point is simple: between an impressive demo and a system that runs reliably under load lies a separate engineering layer, and that layer is what breaks most often right now.
Where orchestration breaks
While there is a single agent doing a narrow task, the pipeline seems under control. But once the system starts handing tasks to other agents, picking tools on the fly and retrying failed steps, complexity grows not linearly but almost explosively. Teams run into coordination problems more than model limitations: agents wait on each other, asynchronous scenarios hit race conditions, and an error in one step triggers a cascading failure in another.
"Demos look impressive, and prototypes feel like magic."
That is why a setup that holds up calmly at a hundred requests per minute can fall apart at tens of thousands. As a result, companies build their own orchestrators, then discover that this layer turned out to be the most expensive and most fragile part of the entire stack. For ML teams this is a shift in mindset: picking a good model is no longer enough, you also have to design a distributed system with predictable behavior under load.
Observability and money
The second problem is weak observability. Ordinary metrics such as latency and throughput are no longer enough: with agentic AI you need to see the entire execution path. Why did the agent pick one tool over another? Why did it repeat a step three times? Why did the final result fail if every intermediate stage looked normal?
Deep-tracing infrastructure for these scenarios is still immature, and the behavior of the systems themselves is non-deterministic. The same request can go down different branches, so reproducing and fixing incidents is noticeably harder.
Against this backdrop, a third issue quickly surfaces: cost. A single agentic request often consists of dozens of LLM calls, and in production that instantly turns into a large bill. Even a price of around 15 cents per scenario looks tolerable only until volume reaches hundreds of thousands of runs per day.
So engineering teams are already betting on a few basic techniques:
- routing simple subtasks to cheaper models
- aggressive caching of intermediate results
- a kill switch for runaway loops and endless retries
- hard limits on the number of steps, calls and attempts
The problem is that savings almost always conflict with quality. Cut the number of steps and the risk of error rises. Move some tasks to a cheaper model and the result is less stable. Above all, budgets are hard to forecast in advance: a non-standard case can trigger a long chain of retries and make a single request dozens of times more expensive than usual.
Testing and control
The fourth barrier is the lack of a mature approach to testing. Classic software relies on deterministic behavior, and classic ML relies on a fixed input/output pairing. Agentic AI breaks both models at once. Today teams check such systems with LLM-as-a-judge, scenario-based test suites and simulations in synthetic environments, but there is no common standard yet. Benchmarks are fragmented, tooling is scattered, and human review remains the main safety net, even though it scales poorly.
The fifth problem is governance and safety. An agent no longer just writes text: it sends emails, changes data, calls external services and can potentially launch transactions. That means access rights, action confirmation, scope restrictions and detailed auditing are needed. But the tighter the safeguards, the weaker the sense of autonomy and the smaller the product's wow effect.
Regulation adds pressure too: once such systems directly affect customers, questions of liability, compliance and the verifiability of decisions stop being theoretical.
What this means
The agentic AI market has run into the infrastructure around demos, not the quality of the demos themselves. The winners will not be those who assemble the next agent fastest, but those who get orchestration, tracing, testing, budgets and safeguards in place before everyone else.
- Nov 1, 2026Local models lose to Opus and Codex: 0.21 on a MacBook versus 1.00 for Codex
- Nov 1, 2026Adobe's EditAgent judge picks a usable edit 81.3% of the time, versus 74.8% for EditScore
- Nov 1, 202616 models tested on 7 search tools: Exa averaged 10.5 out of 14, SearXNG about 3
- Nov 1, 2026Google's StreamVibe video agent beats other models by 10.7% on response timing and quality
Key Questions Answered
Where orchestration breaks?
While there is a single agent doing a narrow task, the pipeline seems under control. But once the system starts handing tasks to other agents, picking tools on the fly and retrying failed steps, complexity grows not linearly but almost explosively. Teams run into coordination problems more than model limitations: agents wait on each other, asynchronous scenarios hit race conditions, and an error in one step triggers a cascading failure in another. "Demos look impressive, and prototypes feel like magic." That is why a setup that holds up calmly at a hundred requests per minu
What are the key details on Observability and money?
The second problem is weak observability. Ordinary metrics such as latency and throughput are no longer enough: with agentic AI you need to see the entire execution path. Why did the agent pick one tool over another? Why did it repeat a step three times? Why did the final result fail if every intermediate stage looked normal? Deep-tracing infrastructure for these scenarios is still immature, and the behavior of the systems themselves is non-deterministic. The same request can go down different branches, so reproducing and fixing incidents is noticeably harder. Against this
What are the key details on Testing and control?
The fourth barrier is the lack of a mature approach to testing. Classic software relies on deterministic behavior, and classic ML relies on a fixed input/output pairing. Agentic AI breaks both models at once. Today teams check such systems with LLM-as-a-judge, scenario-based test suites and simulations in synthetic environments, but there is no common standard yet. Benchmarks are fragmented, tooling is scattered, and human review remains the main safety net, even though it scales poorly. The fifth problem is governance and safety. An agent no longer just writes text: it sen
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.