AtScale: Enterprise AI Agents for Analytics Need Guardrails, Not Bigger Models
AtScale warns that in enterprise analytics, scaling up the model doesn't fix the core problem: chaos in data and business definitions. If AI agents work with conflicting interpretations of revenue, margin, and churn, and have no lineage or source of record, they simply produce confident but wrong answers faster. The fix, according to AtScale, is a semantic layer, shared calculation rules, access control, and strict guardrails.
AI-processed from TNW; edited by Hamidun News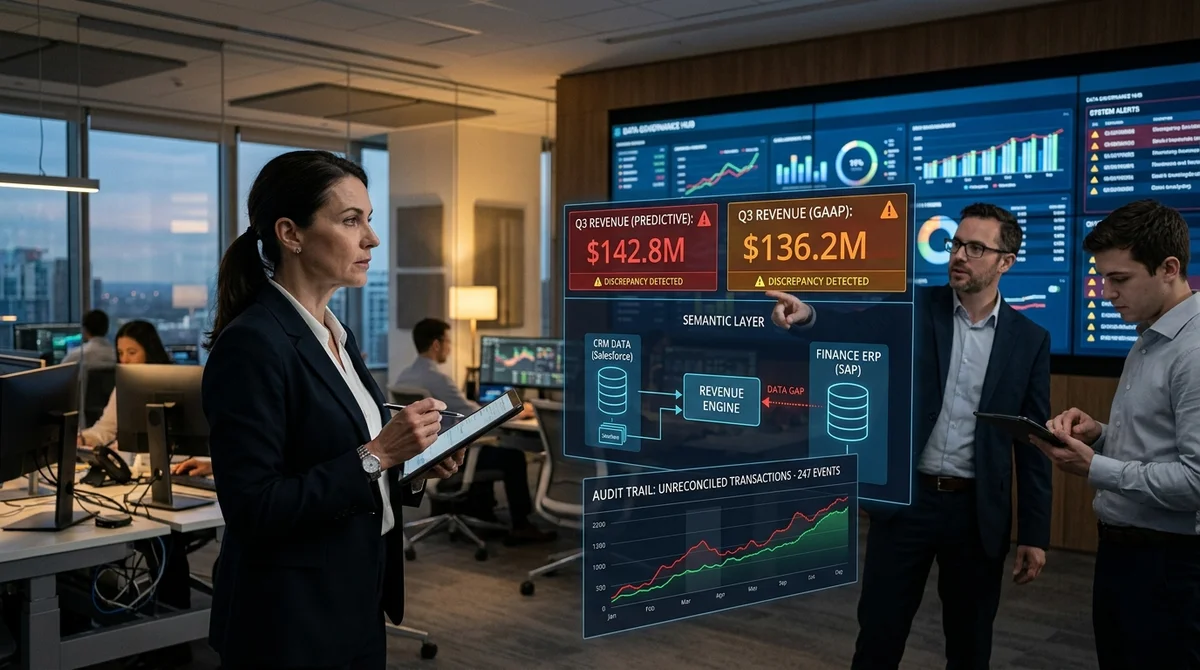
AtScale argues that the main risk of enterprise AI agents in analytics has less to do with model size than with the quality of the context the model works in. If an agent queries fragmented data without shared business rules, it can quickly produce an answer that sounds plausible but is wrong.
Why size doesn't help
Large companies often hope the next, bigger model will fix its predecessor's mistakes on its own: reason better, interpret queries more precisely, and reconcile numbers more carefully. But a model has no magic way of knowing which definition of gross margin or revenue a particular company actually uses. More parameters won't resolve long-standing contradictions between dashboards, reconstruct the provenance of metrics, or create an audit trail.
AtScale also cites a TDWI study in which almost half of respondents described their AI governance initiatives as immature or very immature. The logic is simple: if the source data and definitions are chaotic, more compute doesn't reduce the error — it scales it. The agent answers faster, more confidently, and across more tasks, but the structural problems stay the same. The company ends up not with reliable analytics, but with a more convincing version of the same old mess.
Where analytics breaks
The biggest risk appears where multiple systems and teams work with the same metrics but understand them differently. One agent pulls data from the finance warehouse, another from a CRM or BI tool, and both appear to answer the same question. Without shared context between them, discrepancies stop being a rare error and become the normal mode of operation.
That's why the article offers a short formula that sums up the problem well:
"Confident. Clean. Wrong."
According to AtScale, the typical failures here are quite predictable. An agent may rely on a source where a metric is defined differently than it is by a neighboring team. It may return a result without a clear explanation of how it got there. It may build a conclusion on data it should never have accessed in the first place. And when an answer can't be traced back to a controlled source of record, the company loses the ability to quickly verify the error, assign accountability, and roll back a bad decision without manual reconciliation.
What guardrails are needed
AtScale suggests treating guardrails not as a brake on AI, but as the infrastructure that makes autonomy possible at all. In analytics, the company argues, a model shouldn't work directly with raw tables and each team's local rules, but through a shared semantic layer. This layer doesn't copy or physically change the data; instead, it defines a single meaning for business terms, calculation rules, and access boundaries for every application and agent.
- Unified definitions of revenue, churn, margin, and other key metrics
- Constraints on calculation business logic regardless of the tool
- Lineage visibility: where an answer came from and what data went into it
- Access control: which datasets an agent is allowed to query at all
- Standardization of metrics across departments and platforms
The point of this approach is that model performance and system accountability are separate problems. The model handles reasoning, while the governance layer defines what exactly it reasons over and how the result can be verified. If that layer is built properly, multiple agents across different systems start speaking the same business language. If it isn't, every new integration, process, and additional AI tool only drives up the cost of errors, manual checks, and redone analysis.
What this means
Enterprise AI is becoming less constrained by the parameter race and more by data architecture. That's bad news for companies hoping to "just buy a smarter model" and call the problem solved, and good news for those willing to invest in a semantic layer, governance, and traceability. Those elements, not model size on its own, will determine whether AI analytics can be trusted in real business processes.
- Nov 2, 2026Karpathy builds a YouTube clone with 6454 videos from Hacker News recommendations in two hours
- Nov 2, 2026Karpathy used Claude to build HackerTube from 6,454 videos recommended on Hacker News
- Nov 2, 2026Arca gives AI agents finance tasks lasting up to 10 days, but leaves the trades to humans
- Nov 2, 2026DeepSeek open-sources Super-agent prototype: p95 task completion time of 15.7 minutes vs. 29.5
Key Questions Answered
Why size doesn't help?
Large companies often hope the next, bigger model will fix its predecessor's mistakes on its own: reason better, interpret queries more precisely, and reconcile numbers more carefully. But a model has no magic way of knowing which definition of gross margin or revenue a particular company actually uses. More parameters won't resolve long-standing contradictions between dashboards, reconstruct the provenance of metrics, or create an audit trail. AtScale also cites a TDWI study in which almost half of respondents described their AI governance initiatives as immature or very i
Where analytics breaks?
The biggest risk appears where multiple systems and teams work with the same metrics but understand them differently. One agent pulls data from the finance warehouse, another from a CRM or BI tool, and both appear to answer the same question. Without shared context between them, discrepancies stop being a rare error and become the normal mode of operation. That's why the article offers a short formula that sums up the problem well: "Confident. Clean. Wrong." According to AtScale, the typical failures here are quite predictable. An agent may rely on a source where a metric i
What guardrails are needed?
AtScale suggests treating guardrails not as a brake on AI, but as the infrastructure that makes autonomy possible at all. In analytics, the company argues, a model shouldn't work directly with raw tables and each team's local rules, but through a shared semantic layer. This layer doesn't copy or physically change the data; instead, it defines a single meaning for business terms, calculation rules, and access boundaries for every application and agent. Unified definitions of revenue, churn, margin, and other key metrics Constraints on calculation business logic regardless of
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.