Leman Tech shows how it combined LLM, RAG and classic ML in tech support
Leman Tech explained how it rebuilt its support after a surge in requests: classic ML keeps the bulk classification, while an LLM with RAG is switched on only for complex domain-specific queries in the corporate environment. The approach raised automated classification to 76%, sped up successful answers by more than 20 times and took load off expensive specialists, without extra risk, delays or blind automation.
AI-processed from Habr AI; edited by Hamidun News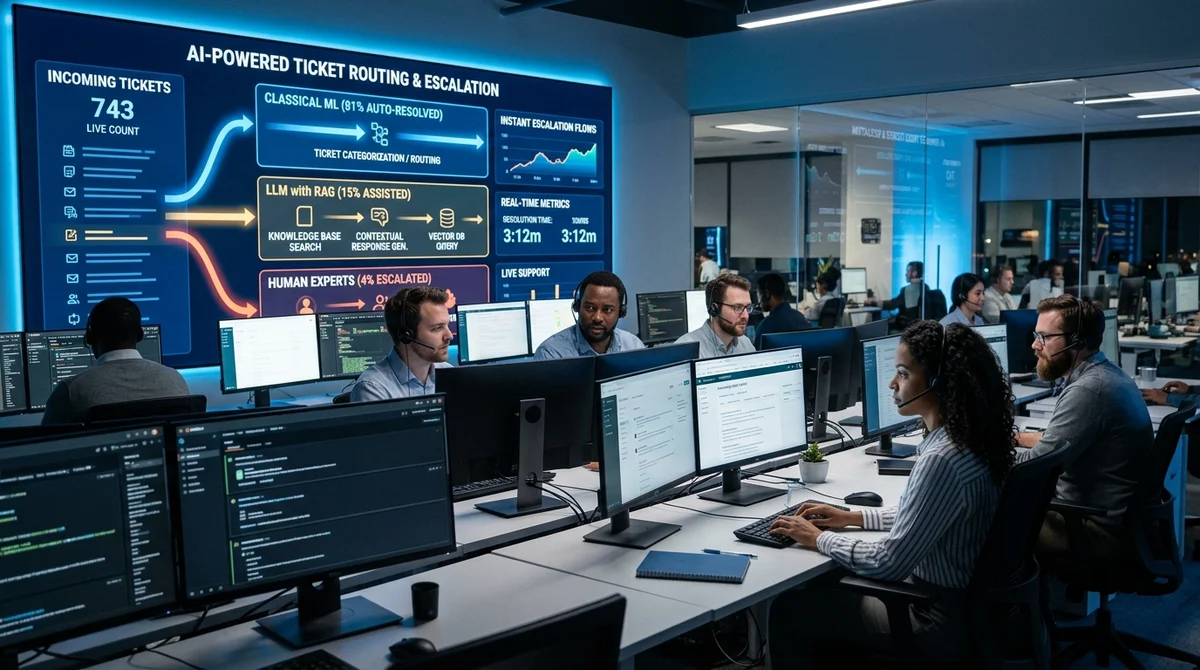
Leman Tech explained how it rebuilt its Service Desk automation after the flow of requests grew. The company did not replace all of support with one big model. Instead, it built a hybrid setup: classic ML keeps the bulk classification, and an LLM with RAG is brought in only where it delivers real value.
Why the old ML is not enough
The Leman Tech ecosystem includes more than 500 business systems, 2,500 service operations and about 100 thousand support requests per month. At that load, model quality is not the only concern: the cost of errors, response speed and compute costs matter too.
The base stack of boosting models and TF-IDF worked fine for a long time. A model with extra features such as job title, workplace and time of the request reached an F1 of about 0.86 and covered a large share of standard routes. But as the number of scenarios grew, that stopped being enough.
The team tested LSTM, GRU, BERT, RoBERTa, Electra, Yandex Foundation Models and LoRA adapters for open LLMs. Some approaches lost to boosting on metrics, and others proved too expensive to train. In the end, the best classification result came not from a "pure" LLM approach but from a transformer with extra tabular features and additive attention. That setup raised F1 macro to 0.89 and took better account of the context of each employee.
Where RAG is switched on
The LLM in this architecture does not try to solve everything. It is enabled only for request classes where the user needs a meaningful answer based on internal documentation, not just correct ticket routing.
One example is support for the MLOps platform, where employees need answers about Kubeflow, Jenkins and internal pipelines. Here the request goes into the chat, passes through the classifier and lands in a RAG loop built on Qwen2.5 8B with a custom embedder. If the answer is in the knowledge base, the user gets it in about 60 seconds. If the model is unsure of the result, or the person presses the command to switch to a specialist, the ticket goes straight to a live expert without waiting under the normal SLA.
This matters: the LLM is not put in front of the person as an extra barrier. It serves as a fast first layer where the time of expensive L4 specialists can be saved without losing control over quality.
- Qwen2.5 8B runs in a quantized CPU version
- The custom embedder was trained on 10 thousand triplets
- Knowledge base search accuracy reached 92% Hit@3
- Escalation triggers when the confidence score falls below 0.7
- The user can switch to a human instantly
What worked better
A separate part of the case is auto-resolutions. The team found recurring request templates that can be closed without involving support, but it did not blindly automate every frequent answer. For selection it used Qwen2.5 14B: the model assessed whether a person could realistically solve the problem alone from the instructions, or whether nothing would work without an employee. This filtered out false templates such as password resets, where the email is standard but a specialist still has to perform the action.
"Using an LLM everywhere, as is fashionable now, is not advisable."
After this selection, production again runs not an LLM but a lightweight model: logistic regression. It trains quickly, costs almost nothing at inference and can serve the stream of requests continuously.
As a result, Leman Tech reports automated classification rising from 55% to 76%, classification accuracy of up to 92% when thresholds are taken into account, and successful auto-resolutions and bot answers becoming more than 20 times faster. The LLM did not replace classic ML here; it took a narrow but valuable place in the chain.
What this means
The Leman Tech case illustrates the current mature logic of adopting generative AI in support: expensive LLMs do not have to be the core of the whole system. Often the best result comes from a hybrid, where classic ML quickly sorts the flow, RAG answers only in complex domain areas, and a human joins without friction when the model's confidence is insufficient. For corporate teams, this is probably a more realistic path than trying to move the entire Service Desk onto one universal model.
Key Questions Answered
Why the old ML is not enough?
The Leman Tech ecosystem includes more than 500 business systems, 2,500 service operations and about 100 thousand support requests per month. At that load, model quality is not the only concern: the cost of errors, response speed and compute costs matter too. The base stack of boosting models and TF-IDF worked fine for a long time. A model with extra features such as job title, workplace and time of the request reached an F1 of about 0.86 and covered a large share of standard routes. But as the number of scenarios grew, that stopped being enough. The team tested LSTM, GRU,
Where RAG is switched on?
The LLM in this architecture does not try to solve everything. It is enabled only for request classes where the user needs a meaningful answer based on internal documentation, not just correct ticket routing. One example is support for the MLOps platform, where employees need answers about Kubeflow, Jenkins and internal pipelines. Here the request goes into the chat, passes through the classifier and lands in a RAG loop built on Qwen2.5 8B with a custom embedder. If the answer is in the knowledge base, the user gets it in about 60 seconds. If the model is unsure of the resu
What worked better?
A separate part of the case is auto-resolutions. The team found recurring request templates that can be closed without involving support, but it did not blindly automate every frequent answer. For selection it used Qwen2.5 14B: the model assessed whether a person could realistically solve the problem alone from the instructions, or whether nothing would work without an employee. This filtered out false templates such as password resets, where the email is standard but a specialist still has to perform the action. "Using an LLM everywhere, as is fashionable now, is not advis
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.