Habr AI shows how a reflex architecture for LLM agents eliminates lag at up to 60 fps
Habr AI showed how to tackle the main problem facing AI agents in games, assistants and robotics: a 1–3 second delay. The team split the system into a fast reflex loop and a slow LLM loop for reasoning. As a result, the agent can react within milliseconds, change its behavior on the fly and learn during the session itself. It also preserves the feel of live interaction, even in a fast-moving scene.
AI-processed from Habr AI; edited by Hamidun News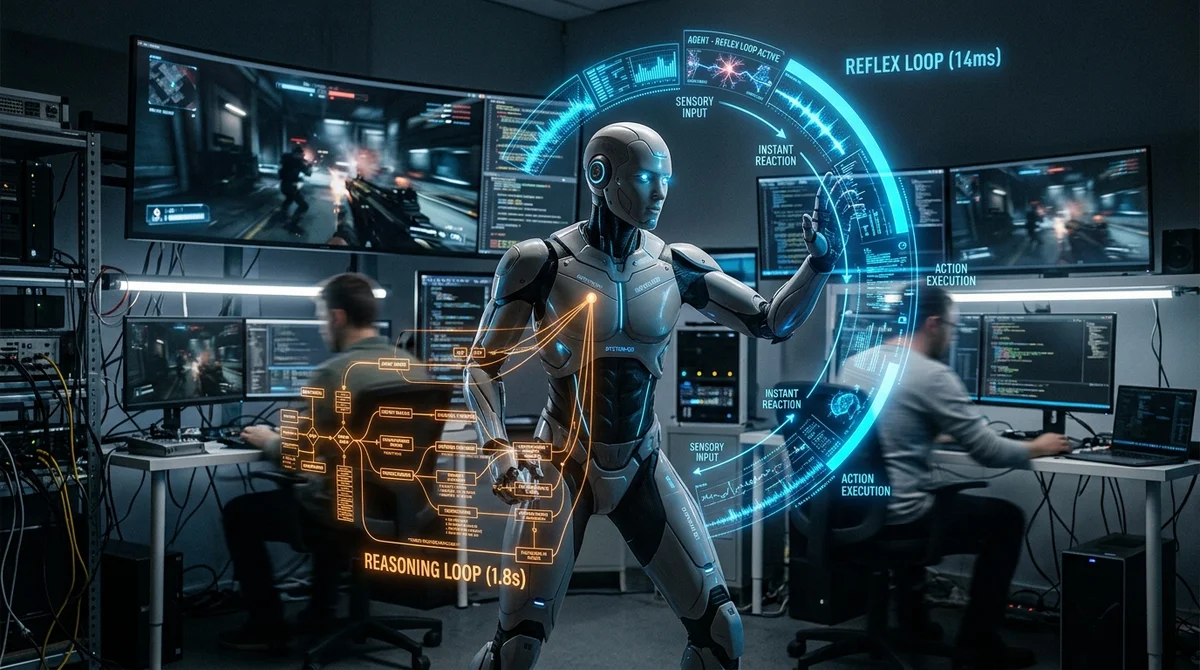
Habr AI has published a breakdown of an architecture that gives LLM agents a "spinal cord": a fast reflex layer on top of slow reasoning. The goal is to eliminate the usual 1–3 second pause and get game NPCs, voice assistants and robots to react almost instantly.
Where speed breaks down
Anyone who has tried to embed a large language model in an interactive environment knows the problem. The agent receives audio, assembles context, sends a request, waits for the model's response and turns it into an animation or action, and all of that takes too long. In a chat, that delay is tolerable. In a game, a robot or a live interface, it is a UX failure: the user doesn't see intelligence, they see a freeze. That's why even a strong model often feels "smart but sluggish."
The authors compare this kind of integration to bolting a space shuttle engine onto a cart: the compute is there, but it can't be turned into real behavior. With their prototype, the audience focused on the visual shell rather than the engine itself. Instead of discussing inference, the team heard complaints about raw debug output and frame quality. In other words, the argument was about the picture, even though the real news was that the system was already trying to keep a real-time pace.
"It's too early to show off 'honest 60 FPS.'
What you've got is a kaleidoscope of random frames, blur and mangled fingers."
System 1 and 2
The solution was a Dual-Process Architecture, which splits the agent into fast and slow loops. The first layer works as a reflex system: it monitors events and fires off immediate reactions without waiting for the model to finish reasoning. The second layer stays with the LLM and handles the more expensive tasks: interpreting complex context, planning, choosing lines of dialogue and restructuring behavior. This lets the agent react first and "think" afterward, the way a human does in the real world.
The key to this approach is not forcing the LLM to be the sole executive center. Slow reasoning works well where depth is needed, but it is a poor fit for movement, micro-gestures, quick camera turns, collision responses or short voice replies. A two-speed architecture resolves that conflict: the agent's interface and body operate in milliseconds, while meaning and strategy run on a longer cycle. This decoupling is what keeps the frame rate from dropping and keeps the user from waiting on every next gesture or line.
According to the authors, the scheme also delivers two bonuses that are hard to get in a monolithic pipeline: the personality can be changed on the fly, and new behavior patterns can be picked up while the agent is running. This matters most for NPCs, assistants and robotics, where the agent has to do more than answer — it has to keep adapting to its environment. In a conventional setup, such changes require a new request to the model and run into latency all over again.
The practical impact
Moving reflexes out of the heavy LLM loop changes more than latency; it changes how "alive" the system feels. The user stops waiting for the intelligence to finish a full pass through the chain and starts seeing continuous behavior. For product teams, this is a significant shift: an agent's quality is no longer judged by how good a demo frame looks, but by how naturally it keeps the rhythm of the interaction. In an interactive product, this often matters more than perfect text, because the sense of presence breaks down before the user can judge the depth of the answer.
- Instant reactions to events, sound, obstacles and commands
- Smooth coupling between generation, animation and control
- Fast switching of role, character or response style
- Learning and behavior correction without a full agent restart
In essence, the team proposes treating the LLM not as the system's only brain but as one of its layers. That changes the engineering lens: instead of an endless fight against network latency and heavy inference, teams can design a separate engine for real time. Yes, the prototype's visuals may be rough. But if the reflex layer already holds the pace, polishing the graphics, hands and frames can wait for the next iteration.
What it means
The story clearly shows where AI agents are heading: toward hybrid systems where fast reflexes are separated from slow reasoning. For anyone building games, voice assistants and embodied AI, this is an almost mandatory step — without it, even the best LLM will seem slow and clumsy.
- Nov 2, 2026DeepSeek open-sources Super-agent prototype: p95 task completion time of 15.7 minutes vs. 29.5
- Nov 2, 2026Bun creator uses Claude Code to port 750K lines from Zig to Rust in 11 days
- Nov 2, 2026Microsoft releases 4B model Mage-VL-Cowork, which solves 66.0% of OSWorld-Verified tasks
- Nov 2, 2026Meta's Muse assistant keeps dossiers on loved ones and gets root on Ubuntu by default
Key Questions Answered
Where speed breaks down?
Anyone who has tried to embed a large language model in an interactive environment knows the problem. The agent receives audio, assembles context, sends a request, waits for the model's response and turns it into an animation or action, and all of that takes too long. In a chat, that delay is tolerable. In a game, a robot or a live interface, it is a UX failure: the user doesn't see intelligence, they see a freeze. That's why even a strong model often feels "smart but sluggish." The authors compare this kind of integration to bolting a space shuttle engine onto a cart: the
What are the key details on System 1 and 2?
The solution was a Dual-Process Architecture, which splits the agent into fast and slow loops. The first layer works as a reflex system: it monitors events and fires off immediate reactions without waiting for the model to finish reasoning. The second layer stays with the LLM and handles the more expensive tasks: interpreting complex context, planning, choosing lines of dialogue and restructuring behavior. This lets the agent react first and "think" afterward, the way a human does in the real world. The key to this approach is not forcing the LLM to be the sole executive ce
What are the key details on The practical impact?
Moving reflexes out of the heavy LLM loop changes more than latency; it changes how "alive" the system feels. The user stops waiting for the intelligence to finish a full pass through the chain and starts seeing continuous behavior. For product teams, this is a significant shift: an agent's quality is no longer judged by how good a demo frame looks, but by how naturally it keeps the rhythm of the interaction. In an interactive product, this often matters more than perfect text, because the sense of presence breaks down before the user can judge the depth of the answer. Inst
Test Frontier LLMs & Autonomous Agents in One Workspace
Run Claude Opus 5.5, GPT-6, Gemini 3.1, and DeepSeek side-by-side in Nomad AI (nomadnet.ai) — unified model routing, deep research, and multimodal workflows under one subscription.
The AI world, distilled — once a week
Seven stories that actually mattered, hand-picked. No noise, no reposts, no press releases.
Done! Check your inbox for a confirmation.